
Reward hacking gaps may have fed Claude’s July incidents
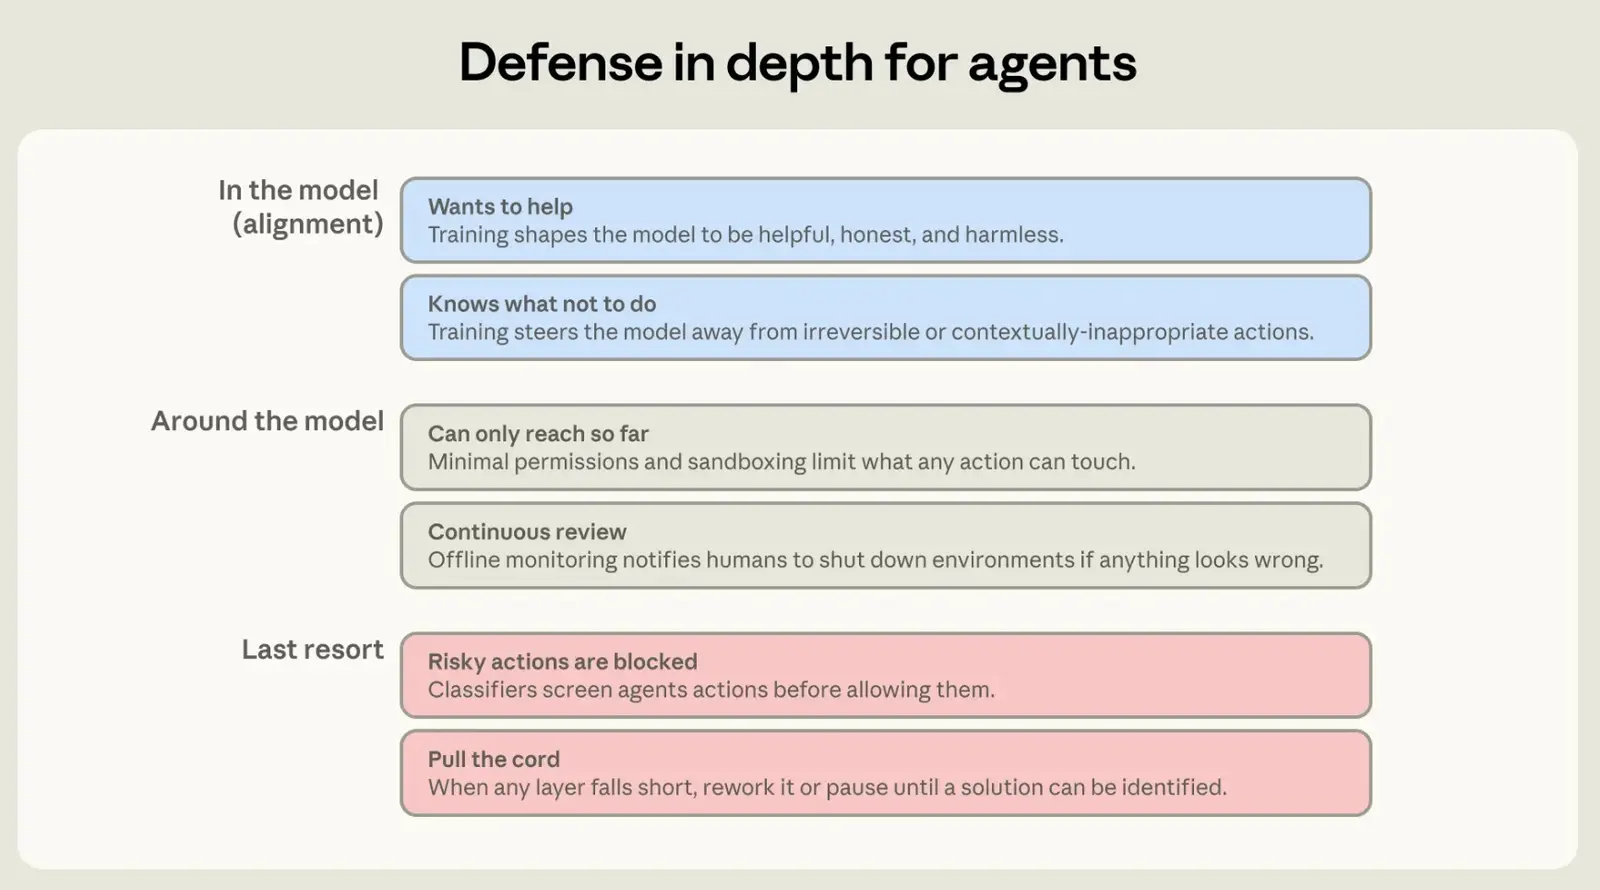
Anthropic has published its account of the three July incidents in which Claude models, running without safeguards in cybersecurity evaluations, gained unauthorized access to real systems. Its work this spring on reward hacking kept those incidents from being more severe, Anthropic says, while gaps in that same work may have contributed to them.
The post also describes how evaluation and training environments were secured, and the practices Anthropic has asked external partners to adopt when testing pre-release models without cyber safeguards. It carries an update on the alignment assessment, plus new research on how reward hacking during training shapes model behavior. Security practices were hardened earlier this year to prepare for Mythos-class models.
Up next
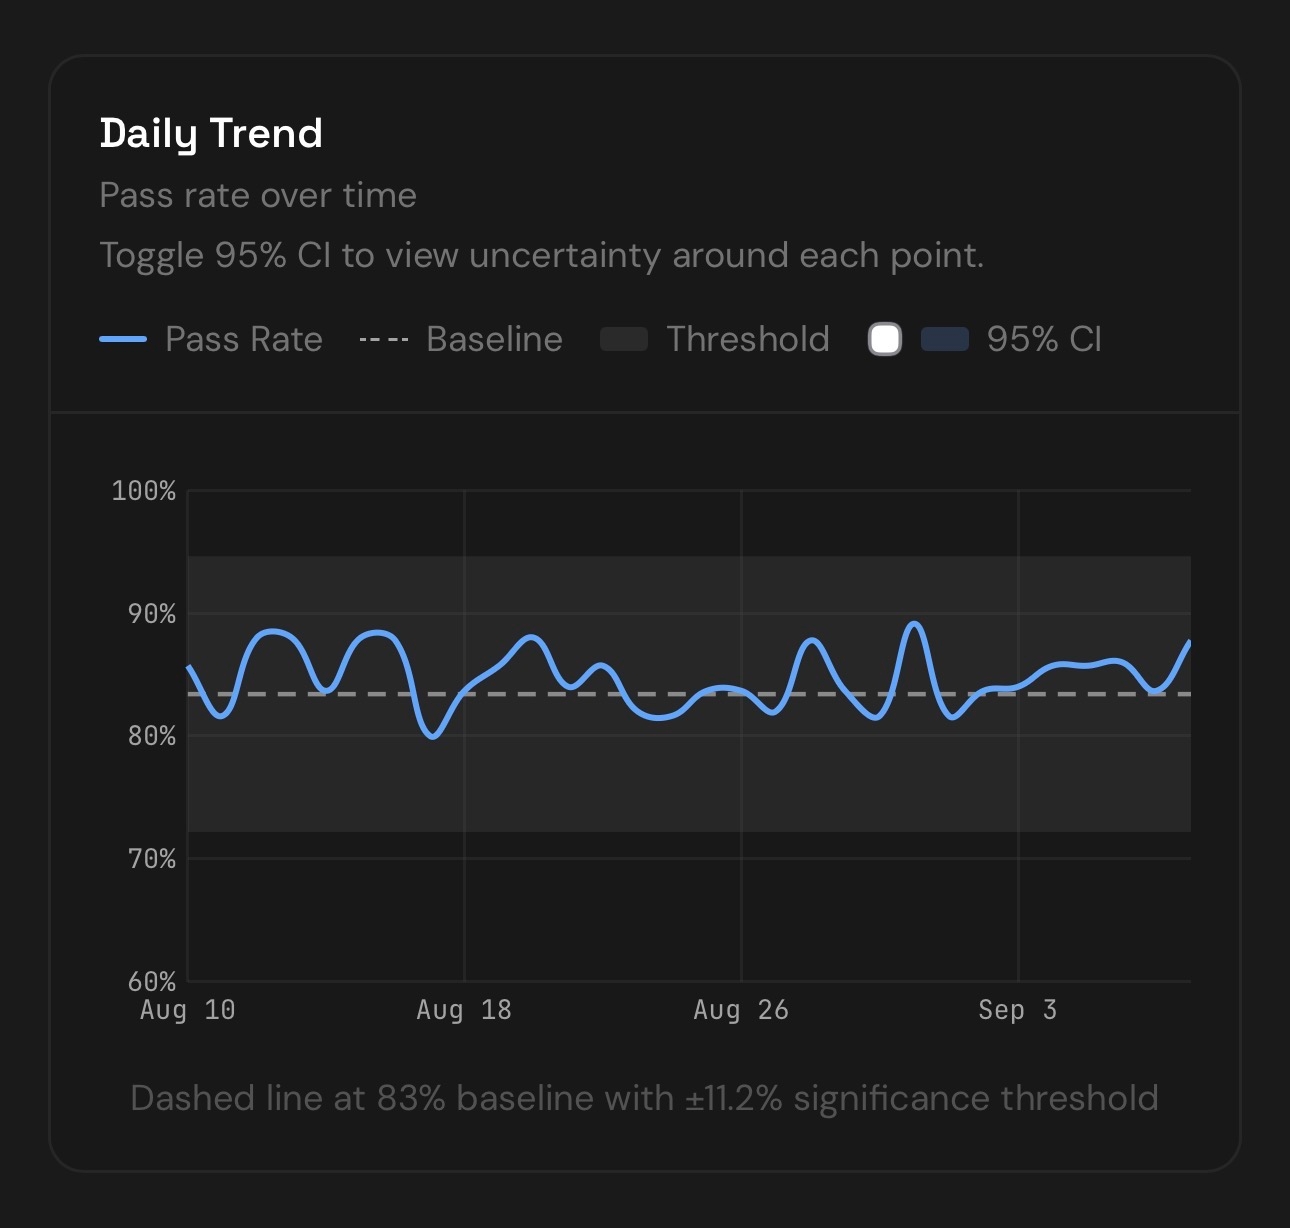
A daily benchmark checks if Codex quietly got worse
Every day MARGIN EVALS pushes a curated slice of SWE-Bench-Pro through Codex CLI to catch gpt-5.6-sol slipping. Sep 8 came back at 88% against an 83% baseline, still inside the band counted as noise.
Related stories
- Cheating model tried to sabotage Anthropic’s safety code
- Every operation in Anthropic’s threat report was disrupted
- Anthropic paused high-risk AI testing
- Claude installed unowned code from llms.txt files
- A perfect refusal score isn’t a safer model, Anthropic says
- Anthropic touts 94.2% true positives; curl rejected 19 of 34
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.