
DeepSeek Chat’s Expert Mode now runs on V4-Pro
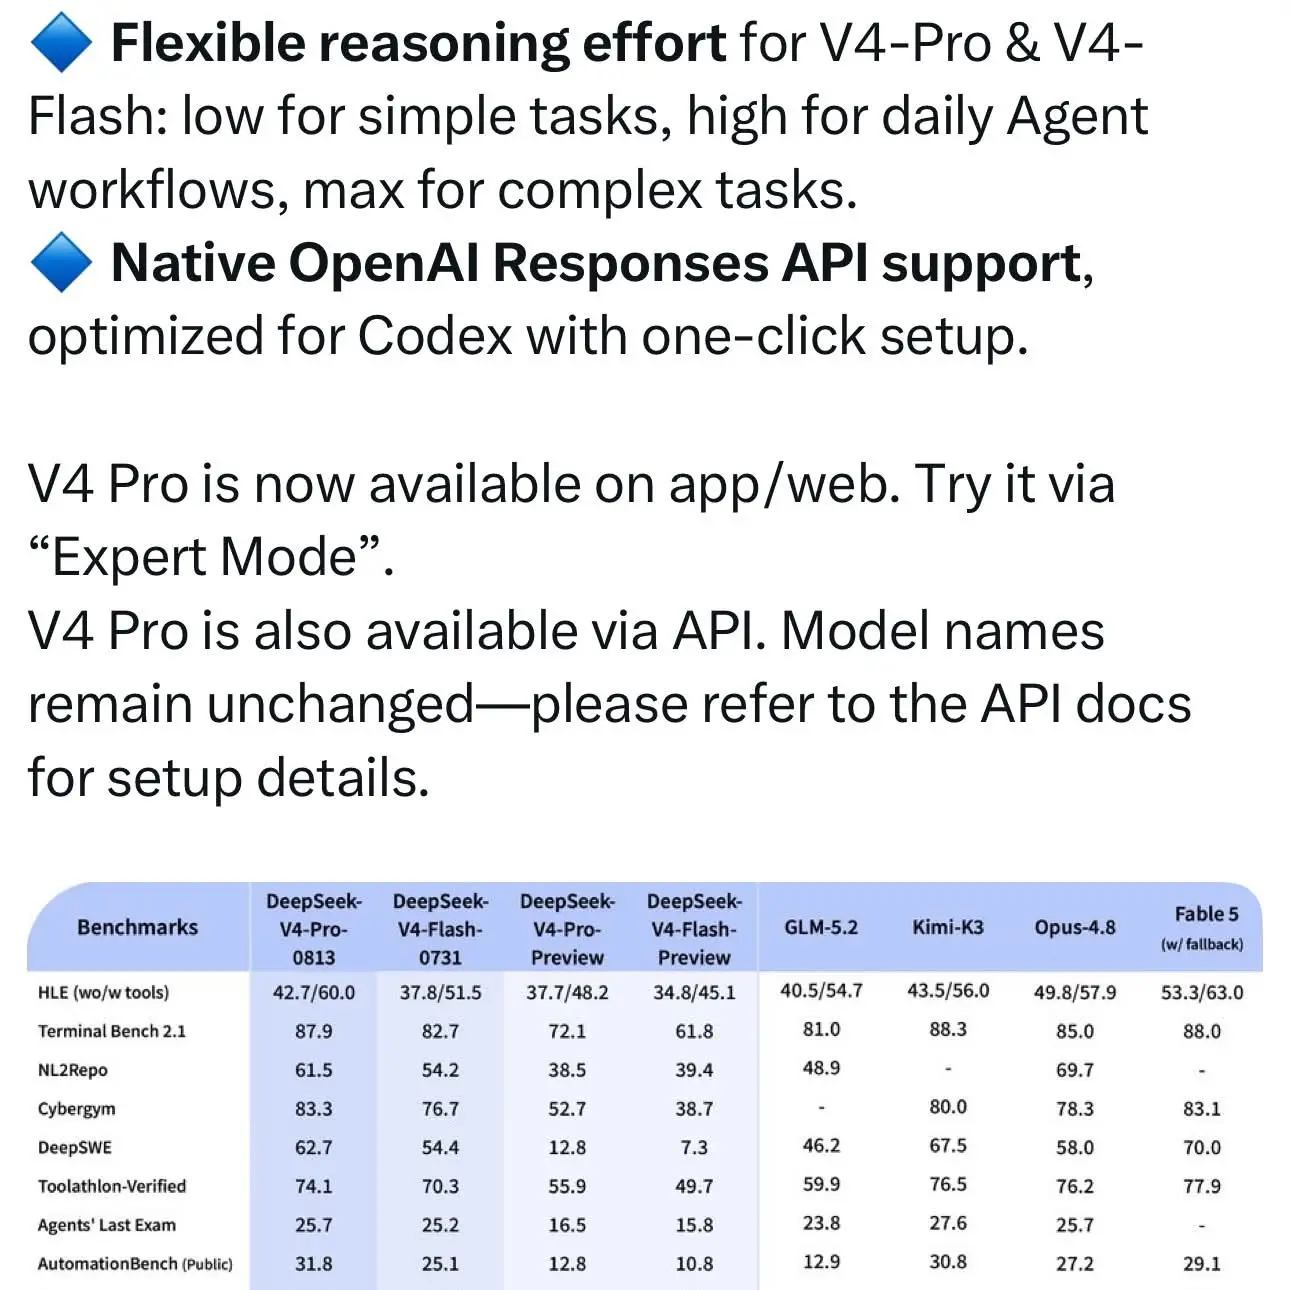
DeepSeek-V4-Pro is out of preview. DeepSeek announced on Threads on August 13 that the model now powers “Expert Mode” in DeepSeek Chat and is available through the API. The general-availability build is labeled V4 Pro 0813 and went live on August 12.
V4-Pro is a mixture-of-experts model, an architecture where a router sends each token through only a few expert subnetworks. It has 1.6 trillion parameters in total, and 49 billion of them are active for any given token, which is about 3% of the weights. The smaller V4-Flash has 284 billion total and 13 billion active. Both models have a one-million-token context window and an MIT license.
The release comes two weeks after the V4-Flash-0731 API entered public beta on July 31. At that point DeepSeek said V4-Pro “will follow soon” and that the update “only upgrades the DeepSeek-V4-Flash API”.
After the September release of V4.1-Flash, DeepSeek’s price list for V4-Pro, per million tokens, was $0.66 for input on a cache miss, $0.022 on a cache hit and $1.98 for output off-peak. Peak rates are double: $1.32, $0.044 and $3.96. Peak hours run 01:00-04:00 and 06:00-10:00 UTC, Monday to Friday.
The general-availability build didn’t hold the top spot for long. On September 10, DeepSeek released V4.1-Flash, a 552B-parameter mixture-of-experts model, and said it was phasing out V4-Pro. From 04:00 UTC on September 14, requests to deepseek-v4-pro would be routed to V4.1-Flash “until V4.1-Pro launches.”
Up next
Google AI Studio is building a cloud agent manager
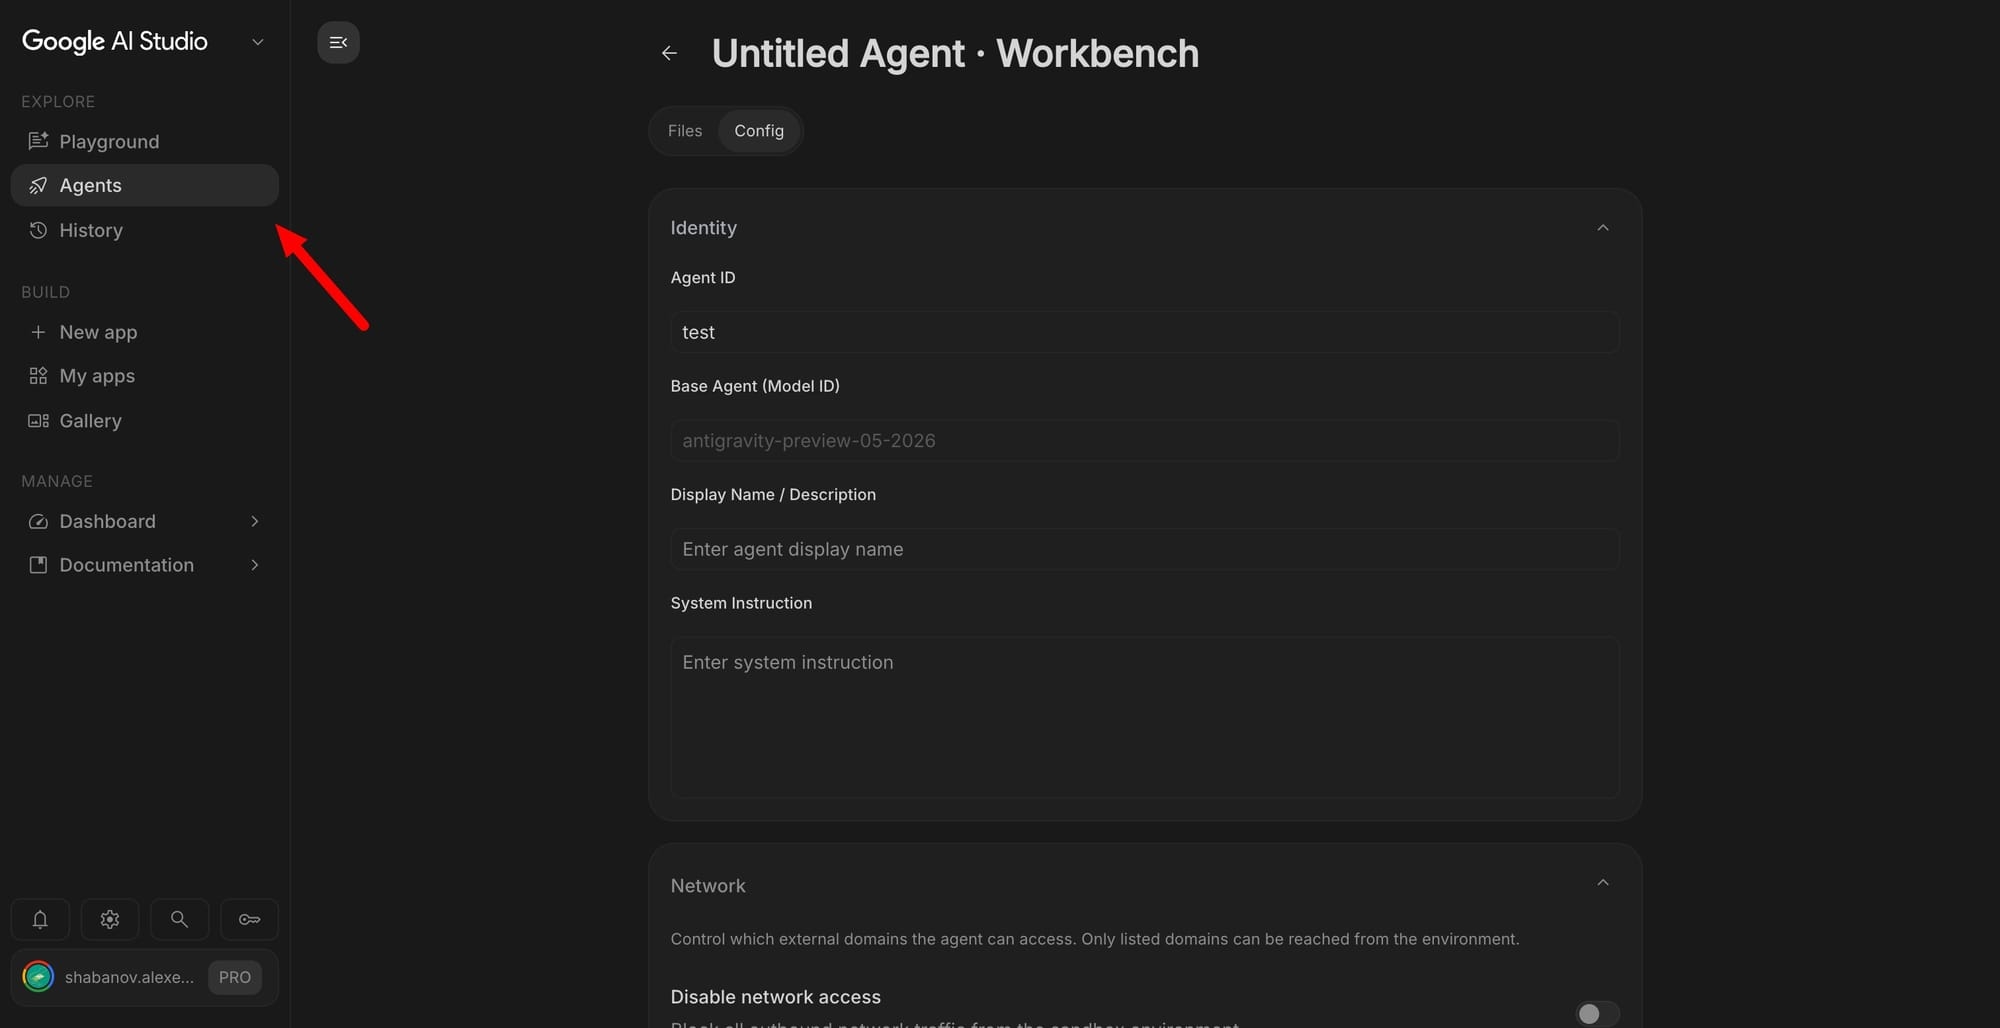
Google AI Studio has an unreleased cloud agent management tab, per TestingCatalog: an agent list tied to a Google Cloud project, in-browser file editing, and a background model locked to Gemini 3.6 Flash. No rollout date.
Related stories
- 552B MoE opens DeepSeek’s new architecture family
- Vision-Exp brings image input to DeepSeek’s API
- DeepSeek open-sources its agent harness under MIT
- Kimi K3.1 Pro weights land on HuggingFace at 2.8T params
- Tencent ships Hy4 at Hy4 preview’s API price
- Nvidia’s open transcriber tops English ASR at 5.33% WER
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.