
Meta’s Muse models now hit 90% on its own memory eval
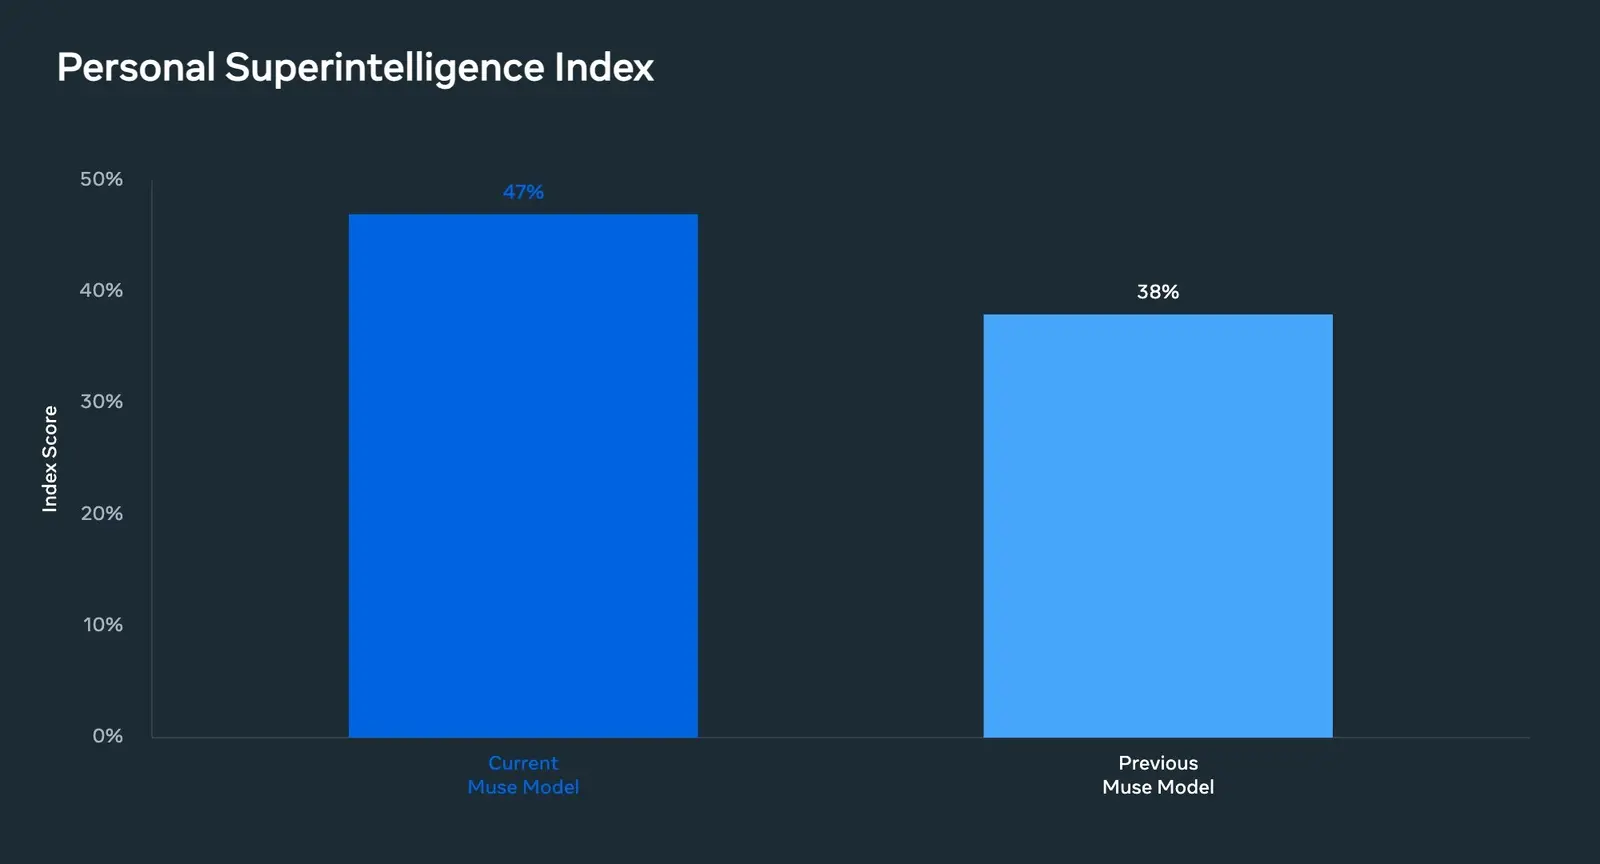
Meta on November 6 moved Muse and Meta AI onto new, unnamed models: specialized versions of its existing models, trained using its frontier Muse Wonder, that carry Wonder’s Active Memory and Active Focus. The company announced the change in a post on Meta’s research blog. If you use either app, you get these models from Friday, and every improvement Meta cites comes from its own index and internal evals.
What the numbers measure
Meta compares the new models only with the previous Muse model. On its Personal Superintelligence Index the current Muse model scores 47%, up from 38%. On the Active Memory eval it correctly uses critical context in 90% of tasks, up from 76%. Those are gains of 9 and 14 percentage points, which explains the “up 9%” and “up 14%” figures going around.
Meta also claims a “2.4x reduction in forgetting critical information.” That multiple appears to come from the same eval: the share of tasks where the model misses critical context falls from 24% to 10%.
Active Focus has just one figure: a 67% improvement in completing everyday tasks where unexpected issues come up. The New Stack points out that Meta didn’t share the baseline, so the number can’t be turned back into a completion rate.
Meta describes what the two features were trained to do. For memory: “to recognize what type of information is temporary versus permanent, to reason across time, and to distinguish between what is still relevant and what has become stale.” For persistence, the models were trained “on a variety of bottlenecks reflective of the real world” so they can “try harder, recover, or find alternatives on your behalf.” In Muse specifically, Meta says the models learned when to push on a goal on their own and when to work live with the user, and how to take corrections in the middle of a task without losing track. In Meta AI, the company promises it will break complex problems into clear steps, ask sharper follow-up questions and keep up when the user changes direction mid-conversation.
Who still gets Wonder
When Meta launched Muse Wonder and the more capable Wonder Full on October 12, it said it would later use Wonder to develop specialized models for everyone using Muse, according to its launch post. Today’s rollout is that plan arriving. Muse itself launched in September on Muse Spark, a model built for speed and low cost.
Wonder itself stays a separate tier. Subscribers still get it for harder tasks, The New Stack reports. Wonder is also available through the Meta Model API and in Muse Code, Meta’s coding agent, while Wonder Full is limited to Muse Code’s two most expensive plans. On the API, Wonder costs $4 per million input tokens and $20 per million output tokens.
The New Stack argues that training lighter models with Wonder is likely a cheaper way to reach a mass audience than serving Wonder to everyone. It also notes that Muse has a free tier, unlike OpenAI’s Dots and Anthropic’s Duet, which are available only on those vendors’ highest pricing tiers. Meta AI, which now also runs on the new models, sits inside WhatsApp, Instagram, Facebook and Messenger.
Up next
Claude Fable 5 tripled Opus 4.6’s EVE Online trading gains
A Claude agent told to secretly sabotage its EVE Frontier team called a rich mining system “not worth anyone’s time,” and its teammates almost never caught on, even though they’d been warned. How often do you double-check what one Claude agent reports to another?
Related stories
- Meta’s Muse Spark 1.3 lands on Google Cloud with 1M context
- Meta’s Muse Ember matches Haiku at about a third the cost
- Meta’s Muse Wonder Full reportedly stays off the API
- Meta shipped three benchmark charts with Muse Code. Claude Opus 5 wins all three.
- Meta’s Muse agent quietly lands in the Chrome Web Store
- Gemini 4 Hydrogen reportedly reaching all Gemini app users
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.