
Nvidia launches a smaller, faster Nemotron model and a router to put it to work
Nvidia says routing between models can cut the cost of a task to roughly a third. In its own internal tests, pairing its open models with Anthropic’s Opus 4.8 held frontier-level accuracy while spending about one third of what Opus alone would cost per task.
The plumbing for that is NeMo Switchyard, an open source Rust library for building model routers, released Tuesday. Kong, OpenRouter, and LiteLLM are already integrating it.
The same day brought Nemotron 3.5 Lightning to the open Nemotron 3 family: 30 billion parameters, mixture-of-experts. On reasoning it lands close to the larger Nemotron 3 Super, though both sit below Google’s Gemma 4 31B on Artificial Analysis’ Intelligence Index. Nvidia claims inference speeds up to 4x higher.
Nemotron 3.5 Lightning is on Hugging Face, ModelScope, and OpenRouter. Switchyard is on GitHub.
Up next
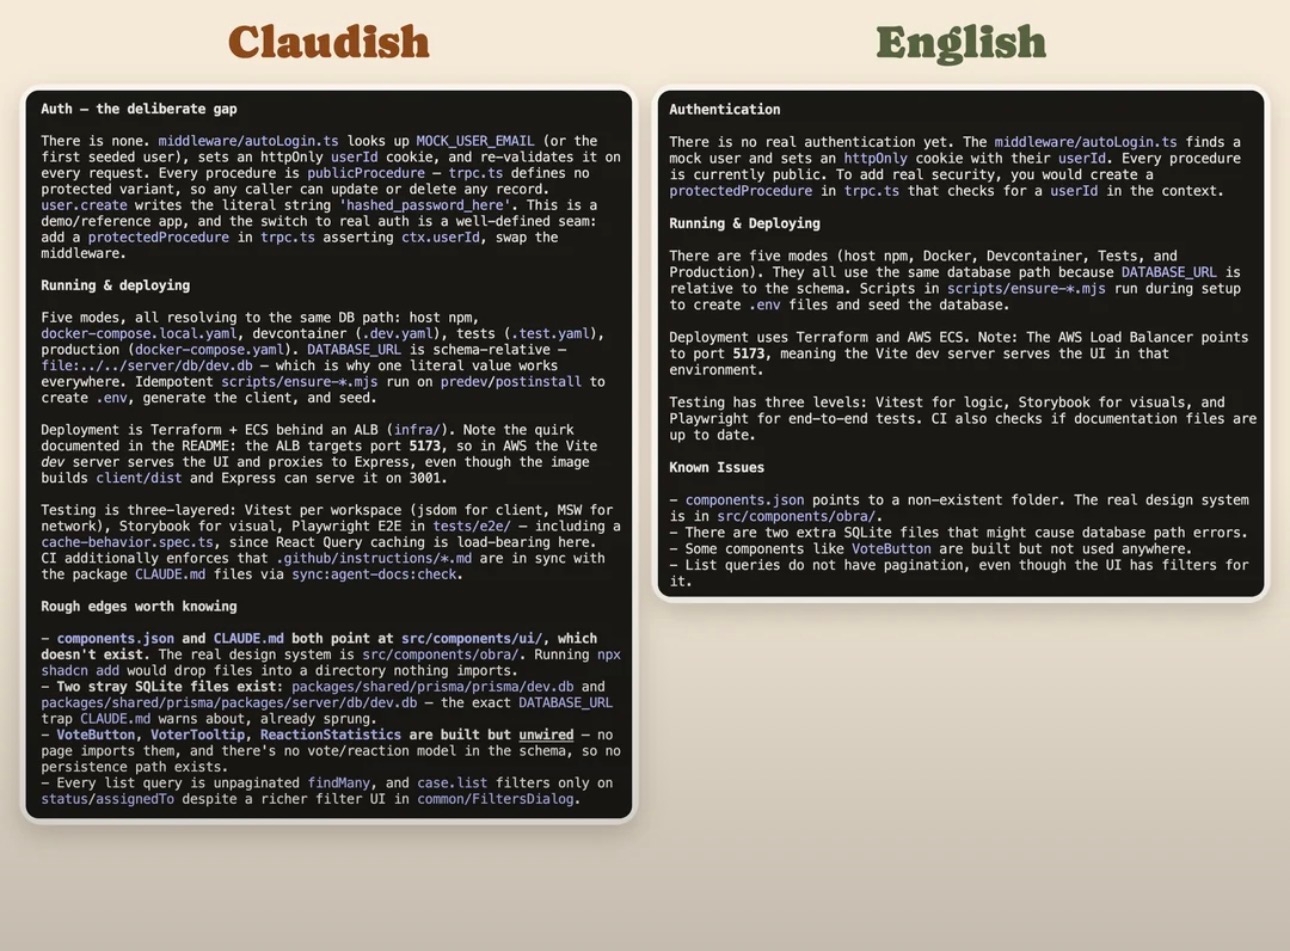
A Claude Code plugin rewrites Claude’s answers in plain English
A new MIT-licensed Claude Code plugin, claudish-to-english, pipes every Claude message through a local Ollama model and displays a plain-language version of it. The default is Gemma 4 at 26B, about a 17 GB download. Tool calls and the saved transcript keep the original text.
Related stories
- Nvidia’s open transcriber tops English ASR at 5.33% WER
- Hugging Face sends language model calls via OpenRouter
- Gemini Decisions API scores 1,000 questions in one call
- No Zero Data Retention for Claude Fable 5.2 on AI Gateway
- Kimi K3.1 Pro weights land on HuggingFace at 2.8T params
- Tencent ships Hy4 at Hy4 preview’s API price
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.