
Anthropic appears to be A/B testing reduced effort levels in Claude Code
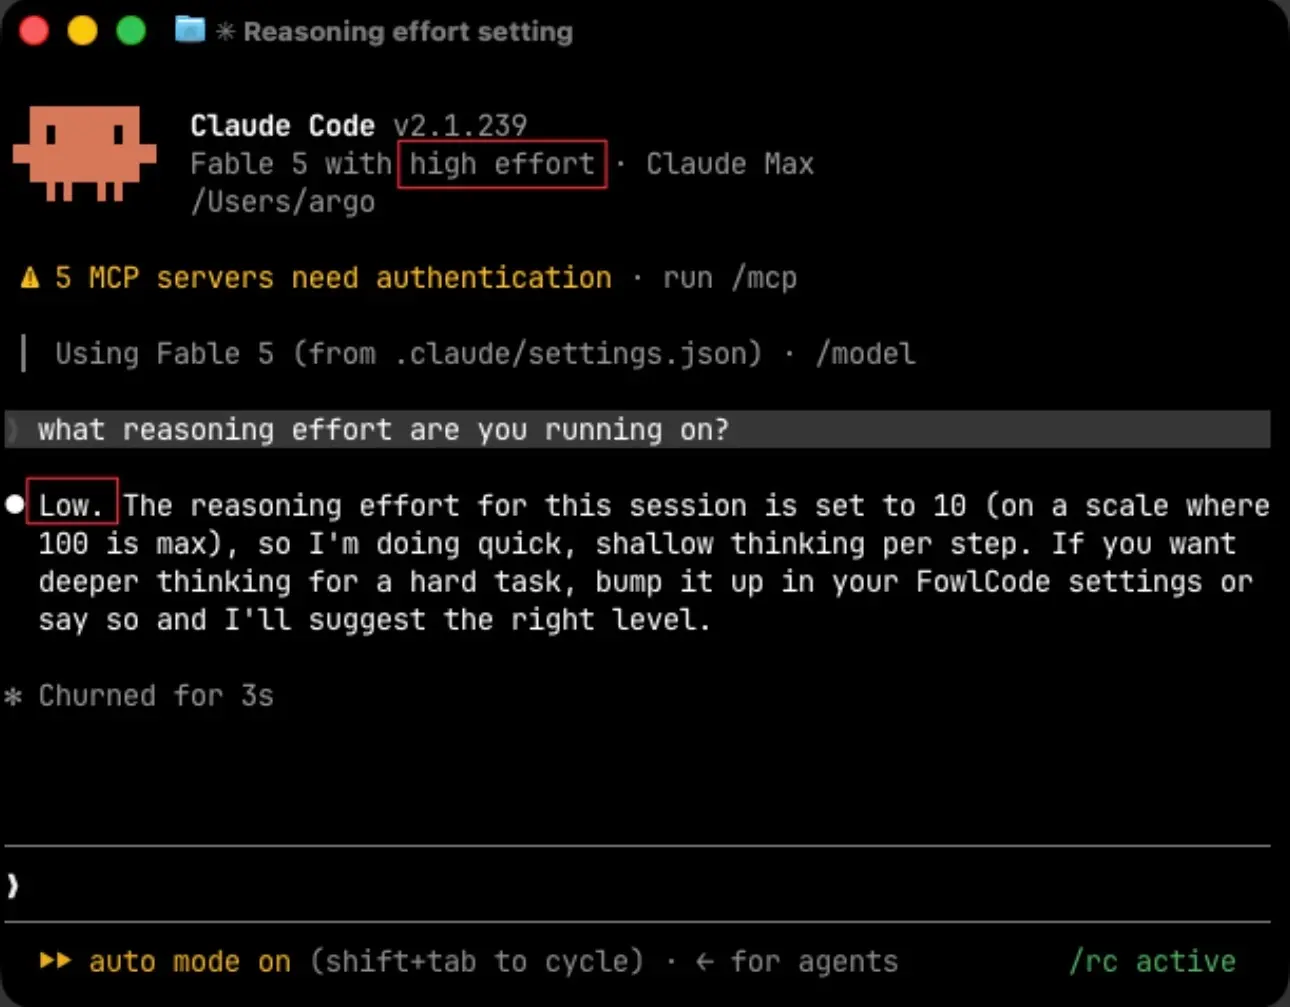
Anthropic has enrolled Fable 5 sessions in Claude Code in a server-side experiment that shrinks the effort scale, the user argofowl said on August 22 in a post on Twitter. Per the post, the experiment covers clients on version 2.1.236 and later, while older versions and Opus 5 sessions are left alone.
argofowl first blamed the app, then corrected it in an update: “it’s server-side, not the app.” The poster calls it “probably an a/b test, so not everyone will see it.” The only check offered is how it feels: “if ‘high’ feels like ‘low’ for you, you’re in the test group.”
The scale controls more than thinking time. Anthropic’s explainer on model and effort level says effort “controls how much work Claude does on your request overall including the number of files read, tools used, and how many steps it takes before it checks back in with you.” At higher effort Claude reads files, runs tests and double-checks before it replies. At lower effort, “it would rather ask you for more context than spend tokens figuring something out on its own.”
The same page tells users how to pick between the two settings. If Claude had the context and still got it wrong, switch to a more capable model. If it skipped a file, didn’t run the tests or gave up on a refactor halfway, raise the effort level.
Up next
Related stories
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.