
Sonnet 5 keeps telling testers it’s GPT-4
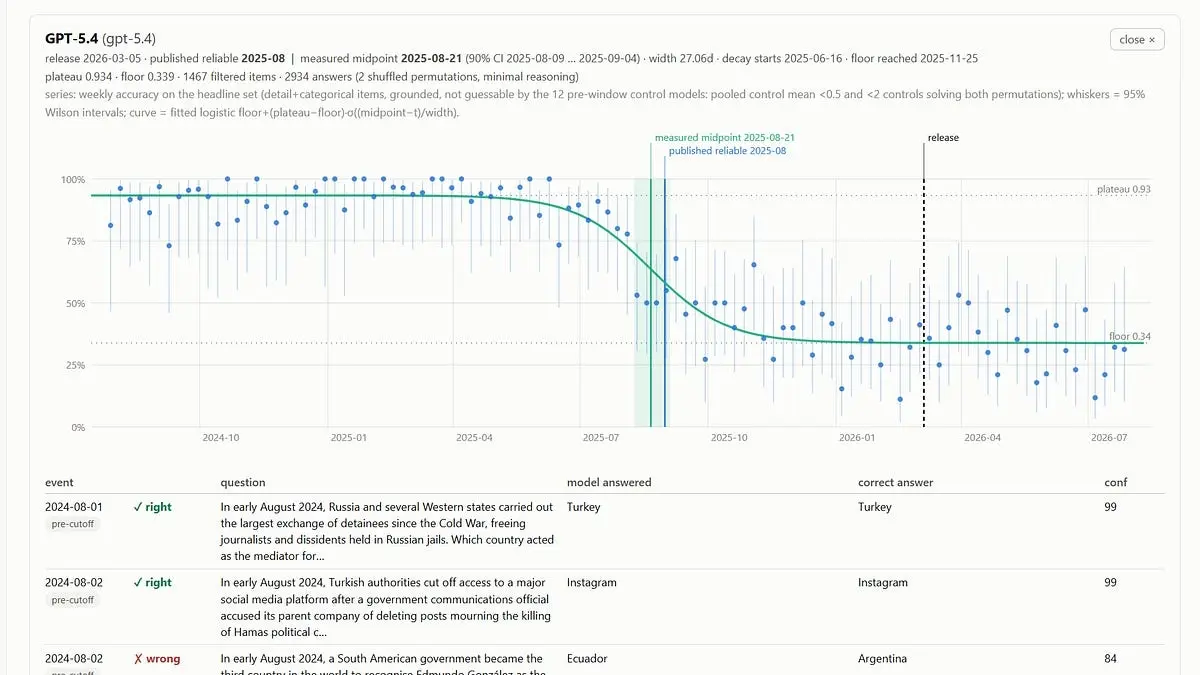
An independent researcher probed the pretraining cutoffs of Claude and GPT models through the official APIs, using an 8-option quiz built from daily Wikipedia facts to find the point where a model loses the signal from its training data.
His read: Anthropic’s models from Opus 4.7 onward came out of a single pretraining run with a cutoff around the end of December 2025. Opus 5 is the odd one out. Its stated knowledge cutoff is in May, but on the measurements it knows no more than models cut off in January.
The self-identification probes are stranger. Across 50 queries per model, Sonnet 5 regularly called itself GPT-4, while OpenAI’s models never once claimed to be another lab’s model. Claude models reproduced the measured quirks of OpenAI models 68% of the time; OpenAI models did the same for Claude in 8% of cases. The researcher’s guess is that old ChatGPT conversations ended up in Claude’s training mix.
Up next
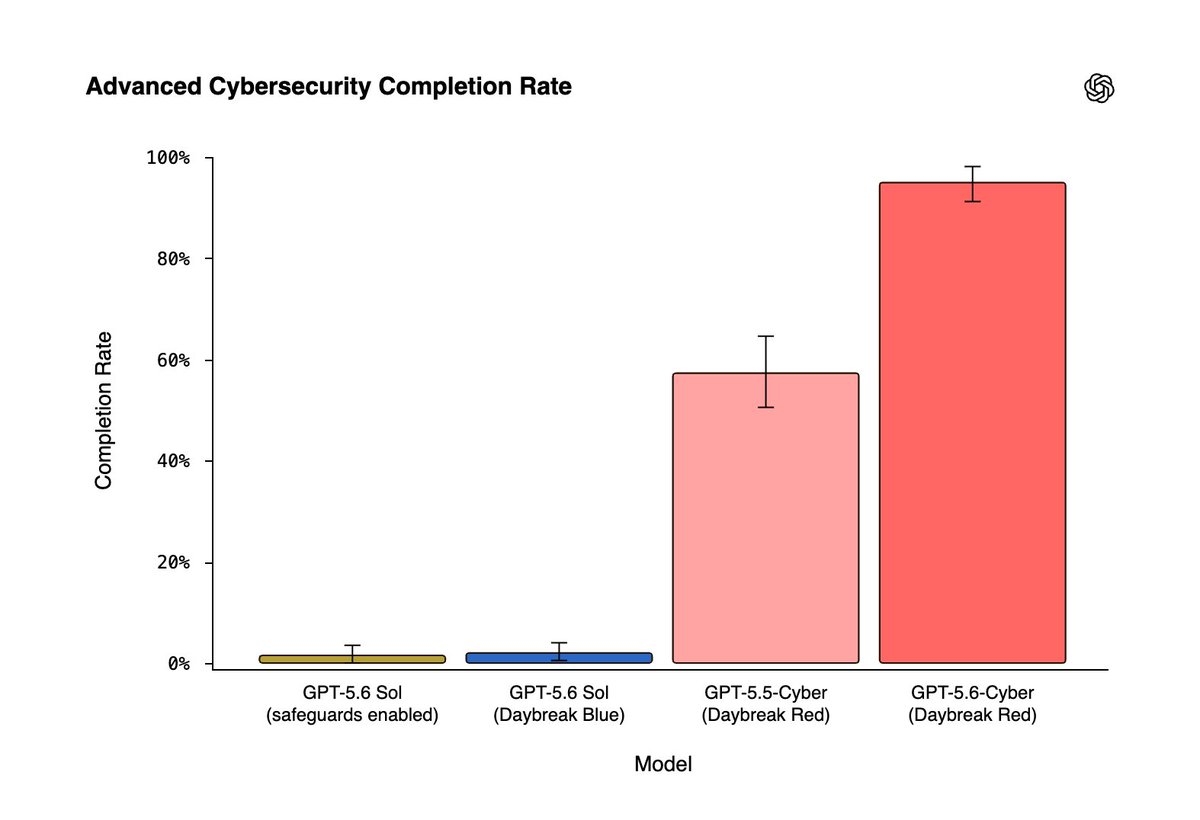
OpenAI puts GPT-5.6-Cyber behind a new Daybreak Red tier, Video
OpenAI says GPT-5.6-Cyber has already found previously unknown vulnerabilities in widely used open source software, including Chrome’s V8 engine. The model, built for authorized vulnerability research, is gated behind a new Daybreak Red tier for experienced defenders.
Related stories
- Claude’s cipher project writes off the gold bar codes
- Claude’s raw thinking never leaves the server
- Claude stamps 2026 onto “best X” search queries
- Claude learned proteins, not just papers about them
- Anthropic bought a biotech with one full-time employee
- A perfect refusal score isn’t a safer model, Anthropic says
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.