
Meituan’s LongCat-2.5 runs 49B of its 1.6T parameters
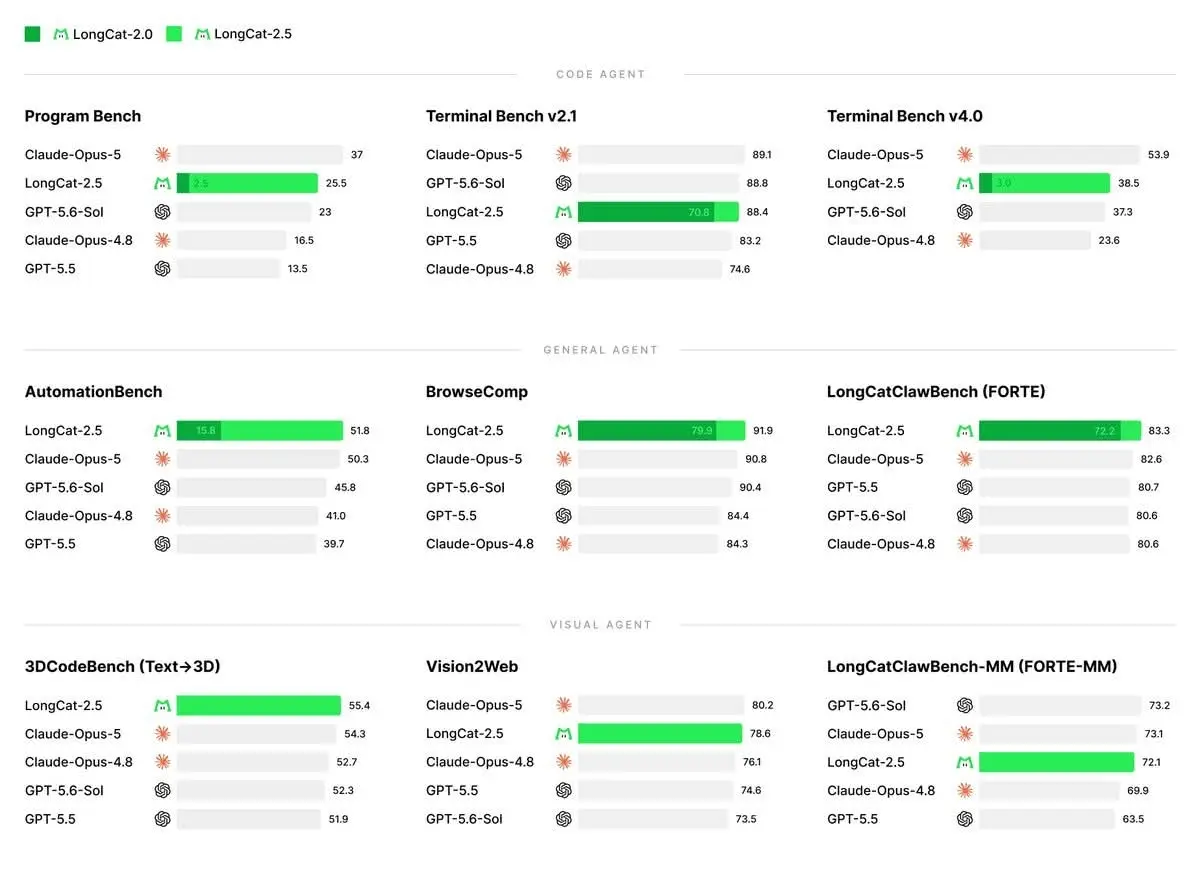
Meituan has put LongCat-2.5, a multimodal model that activates 49B of its 1.6T parameters per token, on its APIs, the company said in a November 2 post on the Meituan LongCat blog. If you’re considering it for coding or long agent runs, keep in mind that the comparison with GPT-5.5, GPT-5.6-Sol, Claude-Opus-4.8 and Claude-Opus-5 comes from Meituan’s own announcement.
LongCat-2.5 is a native multimodal model with a 1M-token context window. Meituan built it for long-horizon agentic tasks and coding, and says it improves on visual understanding and coding. Its total parameter count matches LongCat-2.0, the mixture-of-experts model Meituan released before it, which runs about 48B active parameters per token.
In the LongCat-2.0 repository, Meituan scored its previous model at 59.5 on SWE-bench Pro. That only edged out GPT-5.5 at 58.6, and it trailed Claude Opus 4.8 at 69.2. Those rival scores carry an asterisk, which in the repo means they were not measured in-house under Meituan’s unified harness. LongCat-2.0’s own score was measured there.
Up next
Codedict cuts Claude Code tokens 63%, but cost only 26%
A local code index cut Claude Code tokens by 63% in its author’s benchmark, yet the dollar cost fell only 26%, since the cached context each session pays for stays put. Have your Claude Code sessions run into the usage limit on a big repo?
Related stories
- Kimi K3.1 Pro lands just behind Opus 5.5 on Terminal-Bench
- Qwen3.8-Omni-Flash takes video and audio in a 1M window
- Microsoft claims a No. 2 Arena finish for MAI-Image-2.6. The leaderboard says otherwise.
- Microsoft’s MAI Cyber 2 Flash matches GPT-6 Astra
- Microsoft’s MAI Code 2 claims 96% of Opus 5.5 at 5% of price
- Qwen4-Max scores 43 on Artificial Analysis, 9 above Qwen3.8
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.