
Nemotron 3.5 Super VL gives NVIDIA’s 120B agent model eyes
NVIDIA on October 15 released Nemotron 3.5 Super VL, an open vision-language model. It keeps the layout of Nemotron 3 Super: 120B total parameters, 12B active per token, and up to 1M tokens of context. The difference is input. The March model read only text, and this one also takes images, document pages and video frames. It still answers in text only.
The checkpoint behind the announcement is a base model, built for further pre-training, fine-tuning, reinforcement learning and distillation. NVIDIA’s model card sends people who want a finished model to two post-trained releases: BF16 for customization and NVFP4 for optimized deployment. The license has changed too. Nemotron 3 Super came out on March 11 under the NVIDIA Nemotron Open Model License, and the 3.5 weights ship under OpenMDW 1.1, which permits commercial use and modification.
Kari Briski, NVIDIA’s VP for open models and software, says the model delivers “leading accuracy on multimodal agentic tasks — instruction following, tool use, multistep business workflows, and visual understanding — comparable with NVIDIA’s largest reasoning model at roughly one-fifth the parameter count,” The News Stack reported.
How the backbone was retrained
The language backbone starts from Nemotron 3 Super Base. NVIDIA first trained a shared multi-token prediction (MTP) head for 100B tokens with the backbone frozen. It then ran 1T tokens of distillation from Nemotron 3 Ultra Base, in which the larger model’s outputs act as the training signal for the smaller one. Four more stages follow: 100B tokens of continued pre-training on Indic languages, a 35B-token run that stretches context to 1M, 67B tokens of software-engineering mid-training at 256K context, and a final 9B-token long-context recovery pass. Together that second phase comes to about 211B tokens, roughly a fifth of the distillation run.
The software-engineering mix goes beyond plain code. It covers repositories, issue–pull-request pairs, commit diffs, build and CI logs, and agent trajectories. Only after all that does a C-RADIO vision encoder and a connector attach the backbone to visual input.
The architecture interleaves three kinds of layers. Mamba-2 layers are state-space blocks that handle long sequences without the quadratic cost of attention. Mixture-of-experts layers carry 512 routed experts each, and ordinary attention layers sit between them. Accepted inputs are jpeg and png images, mp4 video up to two minutes, and documents as page images with accompanying text. The 1M window is shared by everything: the prompt, the visual inputs, conversation history, tool results and the response. NVIDIA notes that individual deployment recipes may use a smaller window to fit GPU memory and concurrency. The foundation data runs through December 2025 and covers English, 19 other spoken languages and 43 programming languages. Listed hardware is Hopper and Blackwell, and the listed runtimes are PyTorch, Megatron-LM and NeMo.
The card only gives benchmarks for the text-only base backbone, measured before vision training: 76.25 on MMLU-Pro, 66.16 on GPQA Diamond (5-shot, chain of thought), 47.61 on LiveCodeBench and 86.56 on Global MMLU averaged across eight languages.
Two accounts of faster decoding
On the model card, a shared MTP head predicts future tokens recursively, which gives the model native speculative decoding. That head is inherited: Nemotron 3 Super was already the first model in the family with MTP layers, its technical report says. The News Stack describes the speed-up as LiLiCorr, a technique where a smaller helper model drafts several tokens ahead and Super VL checks them together instead of generating each one in turn. NVIDIA claims this makes generation on DGX Spark up to 2.3 times faster than decoding without speculation.
Against Qwen and the rest
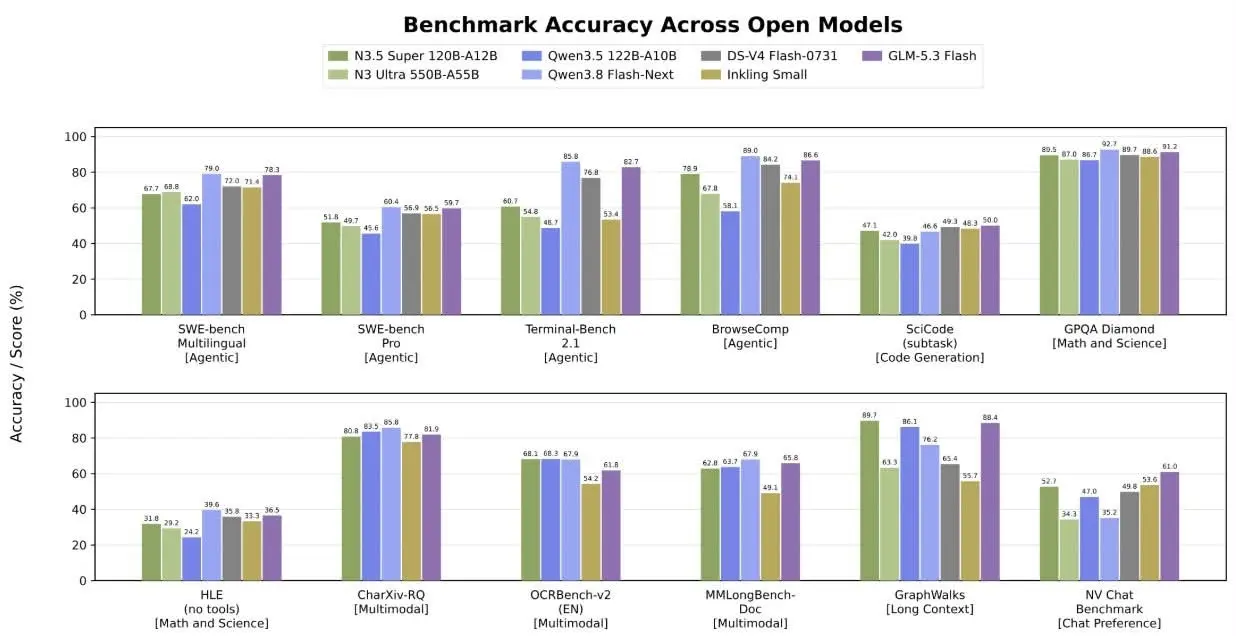
All comparisons come from NVIDIA’s own evaluations, as relayed by The News Stack. Against Alibaba’s Qwen3.5-122B-A10B, which has 122B total and 10B active parameters, Super VL wins on GPQA-Diamond and Terminal-Bench 2.1 and comes in slightly lower on SWE-bench Verified and MMLongBench-Doc. The terminal gap is large, 66.7 to 48.7. The coding deficit is small, 71.1 to 71.9. Qwen3.8-Flash-Next beats Super VL on all five tests, though extra embedding and prediction components bring its total to about 180B parameters. Thinking Machines’ Inkling-Small runs the same 12B active out of 276B total. It trails Super VL on terminal tasks and scores higher on instruction following.
NVIDIA also puts Super VL ahead of its own Ultra on Hermes Bench, 63.44% to 56.33%, and on LangChain’s behavioral evaluations, 87.05% to 84.3%. For documents, NVIDIA says the focus is on OCR, tables, charts and structured information. On the CharXiv chart-reasoning benchmark it reports 80.8%, against 63% for Nano Omni, and 84% when the model can interpret Python code.
Speed is where NVIDIA leans hardest. It reports finishing 10,000 SWE-bench Pro tasks four times faster on four B200 GPUs, but the same chart, The News Stack noted, puts Super VL’s accuracy below both Qwen3.8-Flash-Next and DeepSeek V4 Flash. So the headline speed win comes with an accuracy cost on NVIDIA’s own chart.
Bolt: 74B in 24GB
NVIDIA released two smaller models alongside Super VL, according to The News Stack. Nemotron 3.5 Bolt 74B-A9B 24GB is derived from Super VL and activates 9B of its 74B parameters at a time. Two-bit quantization, which stores weights at very low precision, brings its memory footprint down to 24GB, and the model uses mixed precision that includes two-bit experts. Bolt scores 51.0 on Terminal-Bench 2.1, against 44.4 for Qwen3.6-35B-A3B and 37.2 for Gemma4 26B-A4B. Both rivals were tested in BF16. NVIDIA is optimizing Bolt for RTX Spark and DGX Spark, with support in llama.cpp, Ollama, LM Studio and vLLM, and pitches it for everyday agent tasks on laptops: multistep reasoning, tool calling and web browsing.
The smallest model, Nemotron 3.5 Bolt E4B 4GB, is scheduled for later in October. It targets conversational and physical agents on GeForce RTX, Jetson and Spark hardware, such as device assistants and interactive characters that need multiturn tool use and awareness of what state an app is in.
Up next
AI industryModel releasesanalysis
Krea 3 edits a 2K image in under 8 seconds, Video
Krea 3 finishes a 2K image edit in under 8 seconds for about $0.06, while Nano Banana Pro took about 26.8 seconds and $0.135 in Krea’s own comparison. With AI image edits, is it one careful prompt or a string of quick retries for you?
Related stories
- Nvidia’s open transcriber tops English ASR at 5.33% WER
- Liquid AI’s 2B-active model beats Qwen on LiveClaw
- Aleph Alpha puts a 1M-context model on your own servers
- Kimi K3.1 Pro weights land on HuggingFace at 2.8T params
- Tencent ships Hy4 at Hy4 preview’s API price
- FLUX 3 Image Klein’s 5.6B count leaves out its encoder
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.