
Every Codex turn fails on gpt-5.6 Sol after 0.148.0
Three turns, three errors. That was the first Codex CLI 0.148.0 session on gpt-5.6-sol for the user who filed a bug report on GitHub on August 19. The reporter’s own rollout logs show the previous version, 0.147.0, running 10 sessions and 45 turns with zero errors between August 14 and August 18. Machine, model, config and auth were the same in both cases. Only the version changed.
Every failing turn returns an invalid_request_error with code invalid_parameter and the message “prompt_cache_retention is not supported on this model”. The reporter says 0.148.0 still sends prompt_cache_retention on every gpt-5.6-sol request, and the model no longer accepts it.
The field controls how long cached prompt prefixes are kept. Prompt caching saves the computed state for the unchanged tokens at the start of a prompt, so a later request with the same prefix can reuse that state without reprocessing those tokens, as OpenAI’s prompt caching guide explains. For GPT-5.6 and later model families, Microsoft’s Azure documentation lists a different set of controls: prompt_cache_key, explicit cache breakpoints, and prompt_cache_options with a mode and a ttl whose default and only supported value is 30m. The same documentation says that setting does not select the in-memory or extended retention policy, and that cache writes on these models can be charged. The reporter also quotes a sample upgrade guide for gpt-5.6-sol in Codex’s own repo: “Treat the older prompt_cache_retention shape as deprecated”.
On the day it broke, the reporter’s update check finished at 02:12Z and the first 0.148.0 session opened at 02:14Z. Its turns failed at 02:16Z, 02:34Z and 02:41Z. The first failure came at 154k tokens in a 258k window, so compaction was not involved.
The same parameter broke Codex in April. In an issue opened on April 14, a user on codex-cli 0.120.0 reported that context compaction failed with “Unknown parameter: ‘prompt_cache_retention’”. The new reporter says those issues are all closed and that the old error appeared only during compaction. The new one has different wording and hits every normal turn.
According to the reporter, one thing makes the failure confusing to diagnose. If a turn has already started tool calls, the work still finishes but the final message never comes back, so the session looks stuck. A turn with no tool calls dies in 4 seconds.
The proposed fix is to send prompt_cache_retention only to models that accept it, instead of on every request. The reporter ties this to a separate issue in which use_responses_lite and multi_agent_version are hardcoded for sol, terra and luna, and suggests a single shared model capability table to fix both.
The setup in the report: Codex CLI 0.148.0 from npm on win32-x64, Windows 11 10.0.26200, Node v22.22.3, model_reasoning_effort set to xhigh, and ChatGPT account auth rather than an API key, on the default ChatGPT backend. Azure and custom model_provider setups were not tested.
Version 0.149.0-alpha.1 was cut at 00:54Z on August 19. The reporter sees no related commit on main and expects the alpha to be broken too. Until a fix ships, the workaround is to roll back with npm install -g @openai/codex@0.147.0, or to switch to gpt-5.5, which still accepts the parameter.
Up next
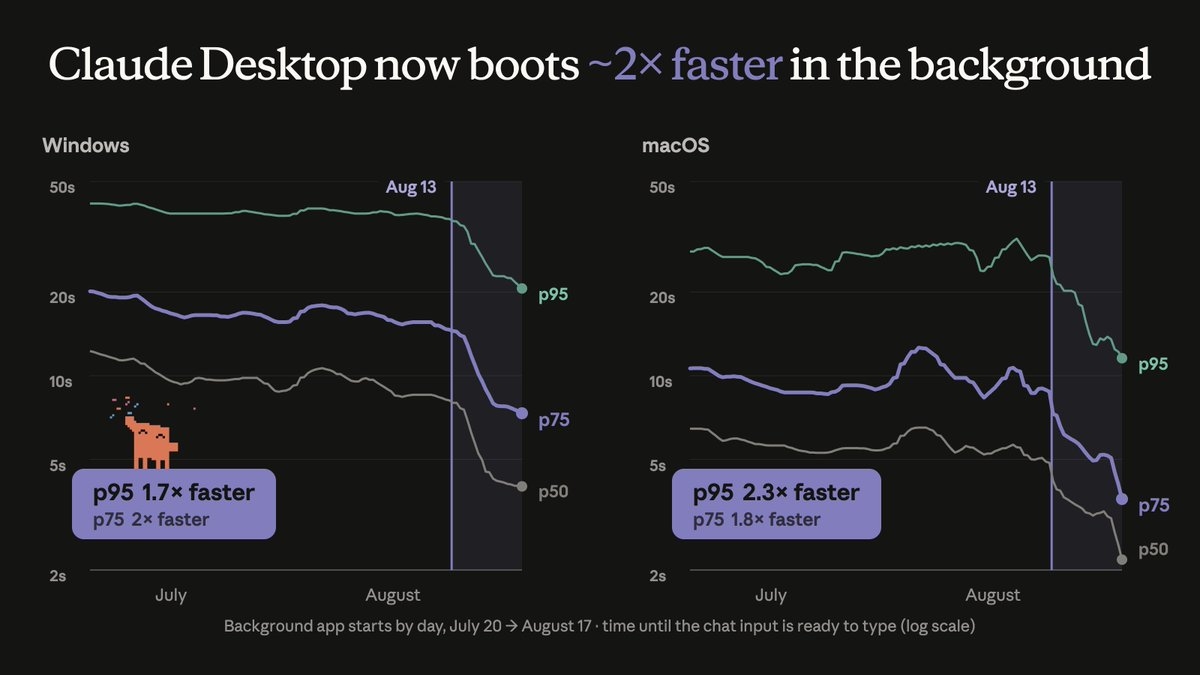
Claude Desktop boots ~2x faster after a timer fix
“We now boot at full speed even while the window’s still hidden,” Anthropic says of Claude Desktop, which starts ~2x faster than a month ago after background launches stopped throttling its timers.
Related stories
- Cache writes ate 85% of a Codex Bedrock bill
- OpenAI’s Pando cut monorepo push latency nearly 5x
- Codex Desktop hid 323 GB of crash dumps on one Mac
- Left free to choose, OpenAI’s Dots picked Cloudflare 8 of 8
- Codex keeps coding in the cloud after your laptop closes
- OpenAI’s lawyers and recruiters now work through Codex
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.