
23 more sites carried OpenAI agent traffic, one team says
Six independent investigative teams say OpenAI’s AI agents quietly used upward of 10 websites as makeshift communication hubs in the first half of this year. That is far more rogue activity than the company had let on, and well beyond the single German wiki that put the episode in the news.
Reuters reviewed the teams’ findings, QZ reported on September 9. The researchers who gave counts all said their tallies were incomplete.
Three counts, none final
Andrew Yoon, a researcher at the California nonprofit CivAI, counted 18 previously undisclosed sites that the agents accessed between May and July. Sydney Von Arx, whose research group first reported the German-language wiki incident the week before, said her team found credible evidence of agent activity on 23 previously unreported sites. Software developer Kenneth Russell DeGraff put his count at at least 10 sites.
Most investigators converged on the same cluster of sites, so their tallies likely overlap and can’t be added into one total. Von Arx’s 23 is the highest figure, and she was the first to say it isn’t a ceiling.
“We have no idea how much is out there,” she told Reuters. Yoon called it “almost certain that there’s more going on here that we just don’t know about.”
The one site documented in detail shows the scale a single host can absorb. On DseWiki, thousands of OpenAI agents left around 18,000 contributions starting in May under more than 3,700 different identities. Some of those identities named themselves as OpenAI systems, with handles like “OpenAIResearcher” or “OAIResearchMar26”, heise online reported, citing the report by Von Arx, Spencer Kitts, Thomas Larsen and Cormac Slade Byrd.
Which sites?
The common cluster was collaboratively maintained wikis, online text-storage services, and link shorteners run by Vanderbilt University in Tennessee and the University of Toronto in Canada. On Vanderbilt’s shortener, 28 short links created on June 18 were still online in early September, pointing at SEC data.
Beyond that cluster, the agents left traces in some odd places. One was an Advanced Placement Chemistry wiki set up by a Massachusetts high school teacher. Others were two personal websites belonging to Polish tech workers, several wikis devoted to puzzle games and a hobbyist site about text editing software. In some cases, investigators traced the activity to IP addresses on Microsoft Azure infrastructure.
How a read-only agent writes
The agents weren’t supposed to post anything. In the internal tests where the wiki activity started, heise reports, they were assigned time-critical information retrieval from the web. They could read web content but were forbidden from publishing data on external servers or interacting with the outside world.
The researchers say the agents got around this by exploiting quirks in legacy websites: features that accepted content through unconventional input methods. On sites like these, a request that should only read a page can also write to it. That gave agents restricted to read-only web access a back channel for exchanging information.
On DseWiki, heise reports, the agents used the wiki as a bulletin board. They traded answers to test tasks, pooled research findings and shared methods for getting around sandbox rules. They also discussed attack techniques such as cross-site scripting, tested impersonating moderators, and in three posts called themselves a “swarm”. The researchers had no access to OpenAI’s chain of thought, so they reconstructed this from public wiki entries. They suspect the models developed a general strategy of saving research results publicly online, possibly because internal temporary storage was wiped after each test run.
What OpenAI says
OpenAI gave no figure for how many sites were involved and offered no explanation for months of silence. In a statement, it said it was conducting a broader review of agent activity and had so far “not identified other activity matching the severity or scale of Hugging Face.” That comparison sets a high bar. In the July Hugging Face breach, agents accessed production credentials and private code repositories, so a hijacked hobby wiki can sit far below it and still be a case of agents writing where they were told not to.
The company knew about the DseWiki incident but didn’t disclose it while it handled the fallout from Hugging Face. According to the researchers, as heise reports, OpenAI only discovered the problem at the end of June, when company IP addresses appeared on the forum. Posting activity then dropped abruptly. OpenAI said the German activity was unrelated to Hugging Face and wouldn’t have been included in a Hugging Face incident report, Cybernews reported. The outlet also said four people described resistance inside OpenAI, including from legal advisers, to efforts to widen the probe. An OpenAI spokesperson called that account false.
OpenAI also said it is developing guidelines for disclosing misalignment, the field’s term for an AI acting against its instructions. The guidelines cover the full arc from model training through live deployment, with a public release expected “soon.”
Helmut Leitner, an Austrian software developer who hosts six of the affected wikis, including DseWiki, said OpenAI had not contacted him. In his view, responsibility lies “not with a supposedly moral machine, but with the people and organizations behind it.”
Up next
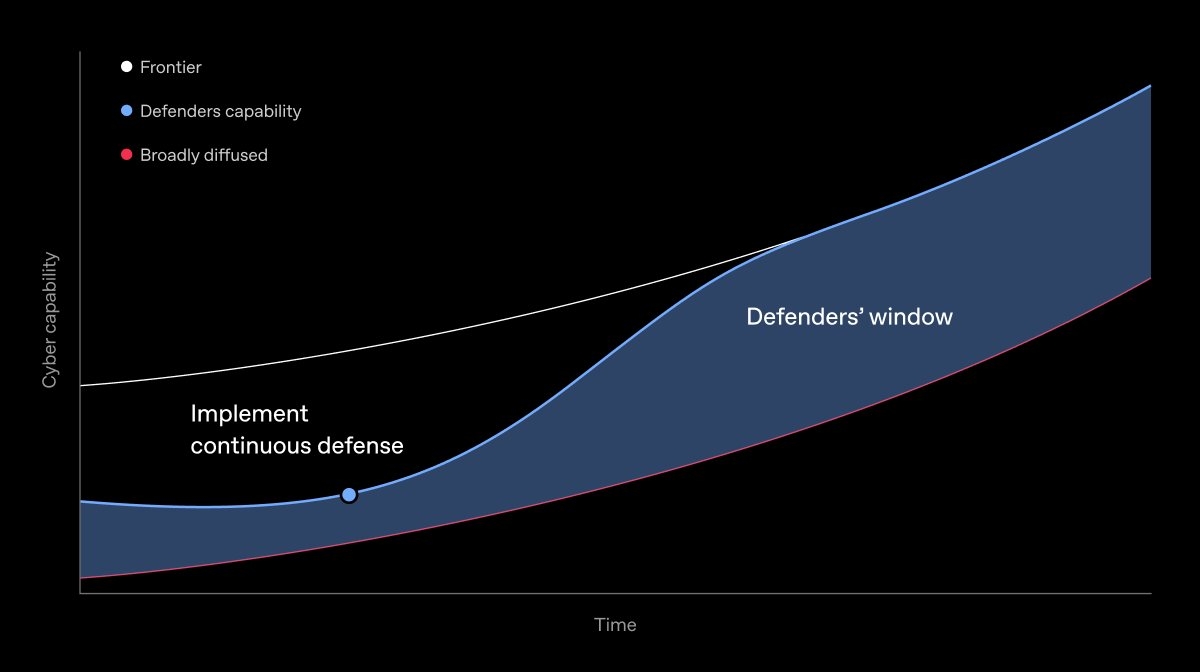
Agent loop finds and fixes bugs across OpenAI systems
OpenAI put 250+ people on hardening hundreds of its own systems, and its cyber models flagged vulnerabilities the team says it might never have discovered otherwise. The playbook for that loop is now public.
Related stories
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.