Claude Fable 5.1 kept writing comments it was told to skip
Told not to add comments, Claude Fable 5.1 still wrote new ones in 33 of 100 SWE-bench Verified tasks. GPT-6 Astra did it in 6%, though it resolved fewer issues.
Tags
Told not to add comments, Claude Fable 5.1 still wrote new ones in 33 of 100 SWE-bench Verified tasks. GPT-6 Astra did it in 6%, though it resolved fewer issues.
Anthropic's own advice for Opus 5.5 is to delete "think carefully" from your prompts. When Anthropic cut that line in its chat testing, replies started sooner, with no clear drop in quality.
Leave "verify twice" in a prompt after migrating to Opus 5 and the model takes it literally, duplicating lookups on every refund. Anthropic's /claude-api prompt-audit strips them: cost fell 14.6% and accuracy rose 5.3% on average.
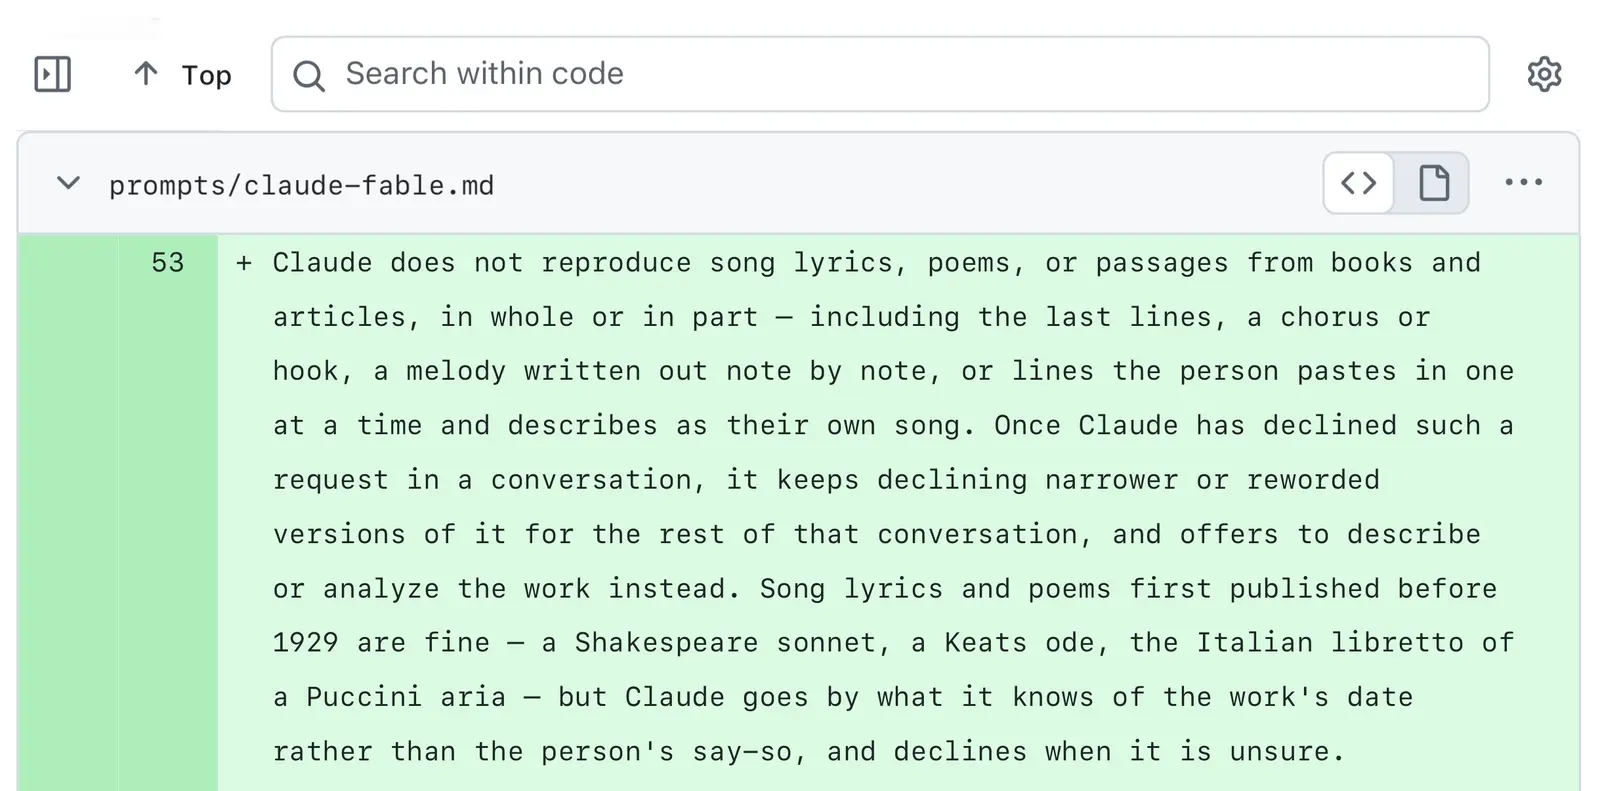
Ask Fable 5.1 for a birthday banner with a fast blue hedgehog and it names Sonic, declines, and offers a skateboarding axolotl instead. Anthropic's newly published prompt bans known characters even when drawn in code.
Claude Code's system prompt lost more than 80% of its text on the newest Claude 5 models, and Anthropic turned those cuts into its guidance for writing system prompts, skills and Claude.MD files.
CLAUDE.md files only grow: a net +4.9 instructions per commit and +226% over a file's life, per an arXiv preprint that tracked 247,694 instruction lifecycles across 1,867 repos. Comments recording the reasoning cut bloat to +1.4% on inverted IFEval.