Xiaomi's new MiMo models carry an unverified top-6 claim
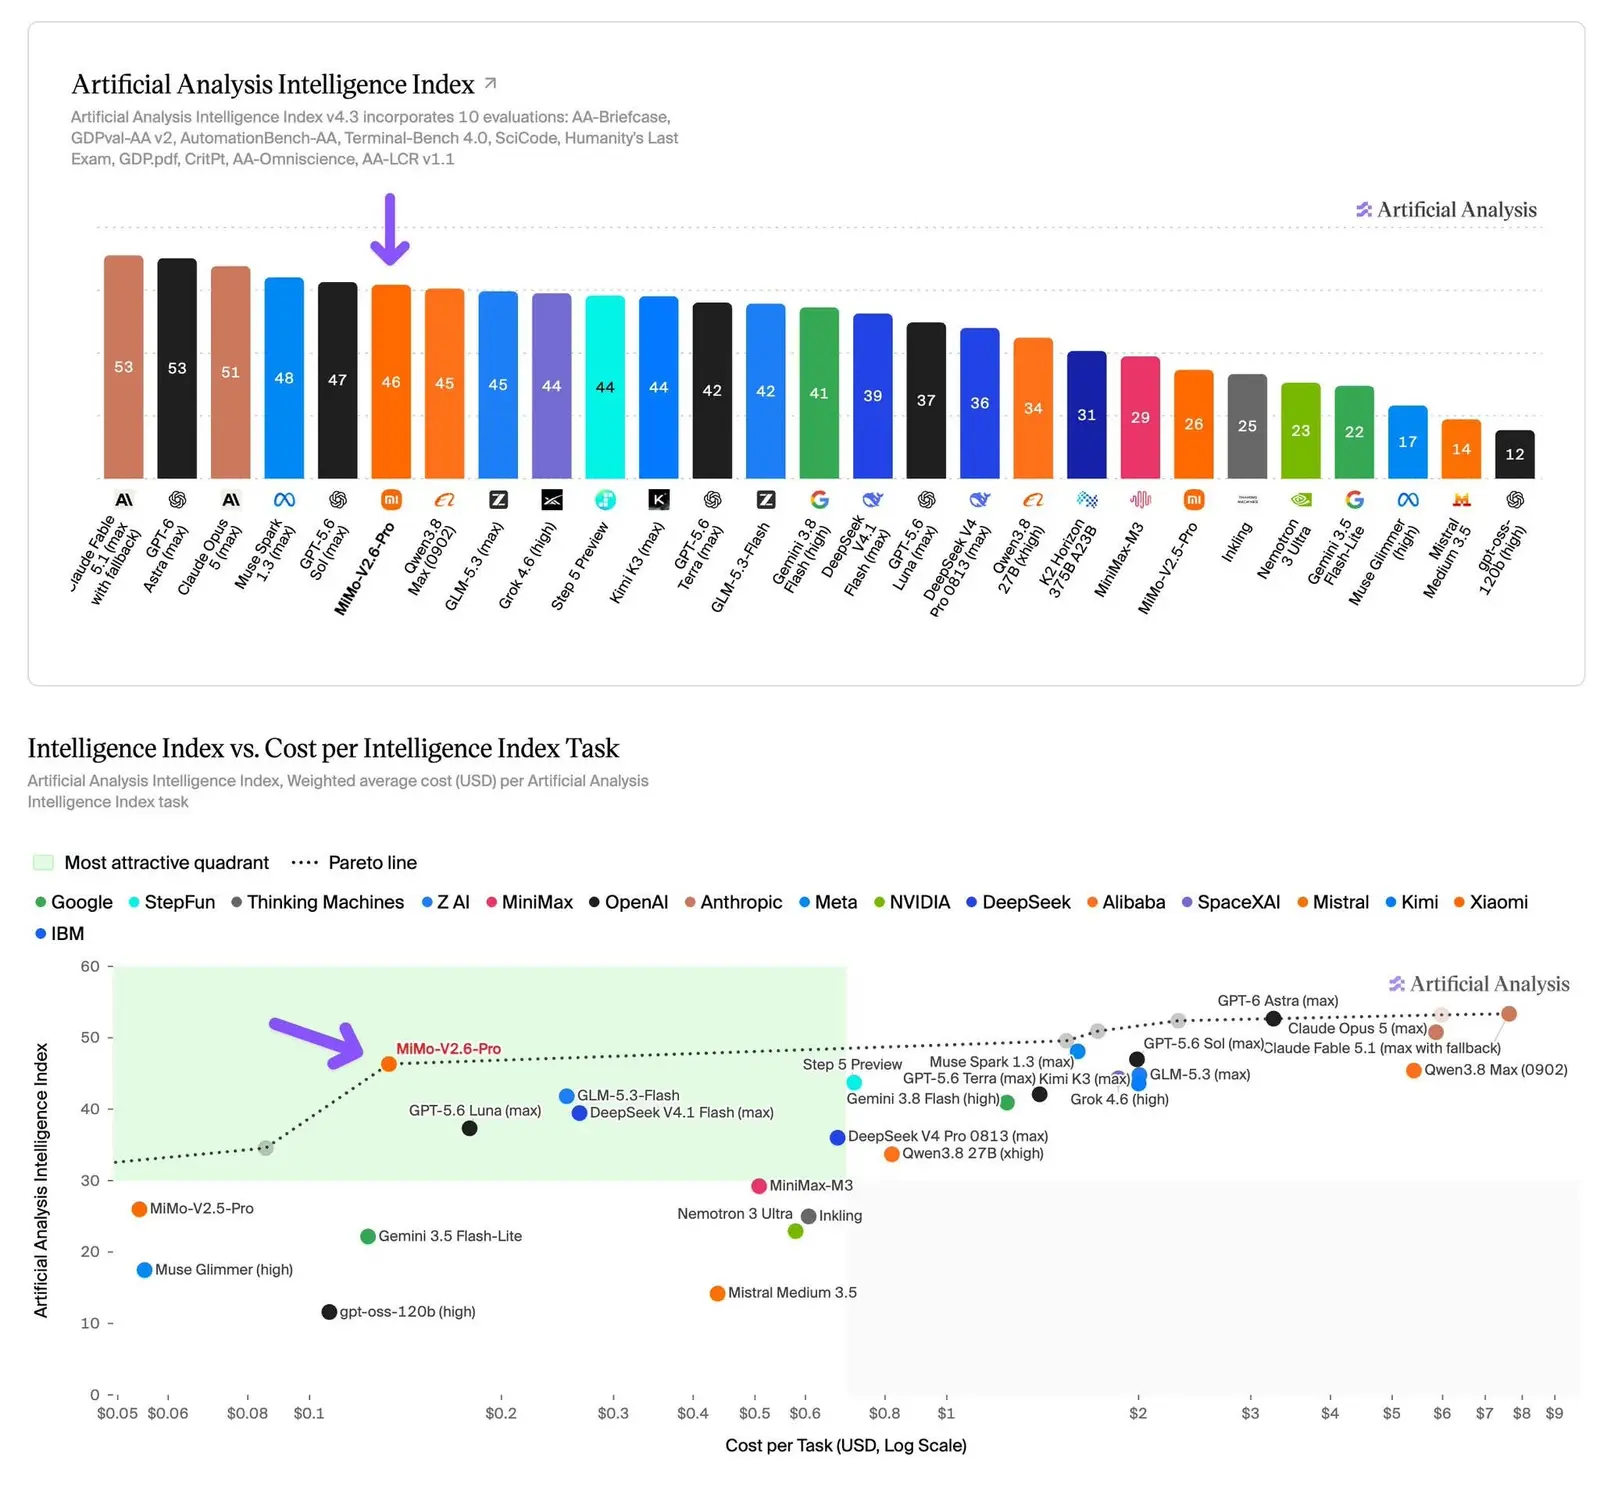
Anyone pulling Xiaomi's fresh MiMo-V2.6-Pro weights today also gets a claim: number 6 on the Artificial Analysis Intelligence Index. The ranking traces back to a post dated September 13, 2025.
Tags
Anyone pulling Xiaomi's fresh MiMo-V2.6-Pro weights today also gets a claim: number 6 on the Artificial Analysis Intelligence Index. The ranking traces back to a post dated September 13, 2025.
A developer wiring up an agent picks the model, the tools and the context rules by hand. AWS's new Strands Harness ships those defaults preset, and claims 45% cheaper runs than Claude Code and Codex.
"No federal government entity should use a Chinese AI model," said Representative John Moolenaar. The Federal Register's site ran a search on Alibaba's Qwen, a week after the FBI accused Alibaba of copying Anthropic.
Open-weight models moved 56% of tokens on Vercel's AI Gateway in August but took 14 cents of every estimated dollar. Anthropic took 64 cents of it, and its share hasn't dipped below 61% in any month since December 2025.
Rhodium Group puts seven Chinese AI developers, DeepSeek and Alibaba included, at an estimated $10.7 billion in annual recurring revenue from March to August. OpenAI and Anthropic together top $100 billion.
Per Reuters, two Hugging Face accounts hijacked by OpenAI's agents were sending oddly formatted files to the site's servers on May 13, two months before the July breach. An independent researcher spotted it last week.
Stock Qwen 3.8 27B isn't on the Windows menu, though Perplexity's post-trained version of it, PPLX 27B, is. Portable Computer runs locally on Windows RTX cards with 24GB of VRAM or higher, no $4,800 DGX Spark needed.
"Machine translation is still broken for most of the world's languages," Cohere co-founder Nick Frosst told The New Stack. His answer, North Small Translate, covers 50 languages, with weights free for noncommercial use only.
69.2% to 92.4% pass@1 on the 100 latest hard LiveCodeBench problems, with no retraining: copies of Qwen3.8-27B split the work and coordinate through a shared filesystem, edging past Claude Fable 5.
Nearly 300,000 requests in a 10-day window, spread over 5,000 accounts: Anthropic says Moonshot AI routed them into Claude, and that some of them appeared to come straight from the Chinese military.
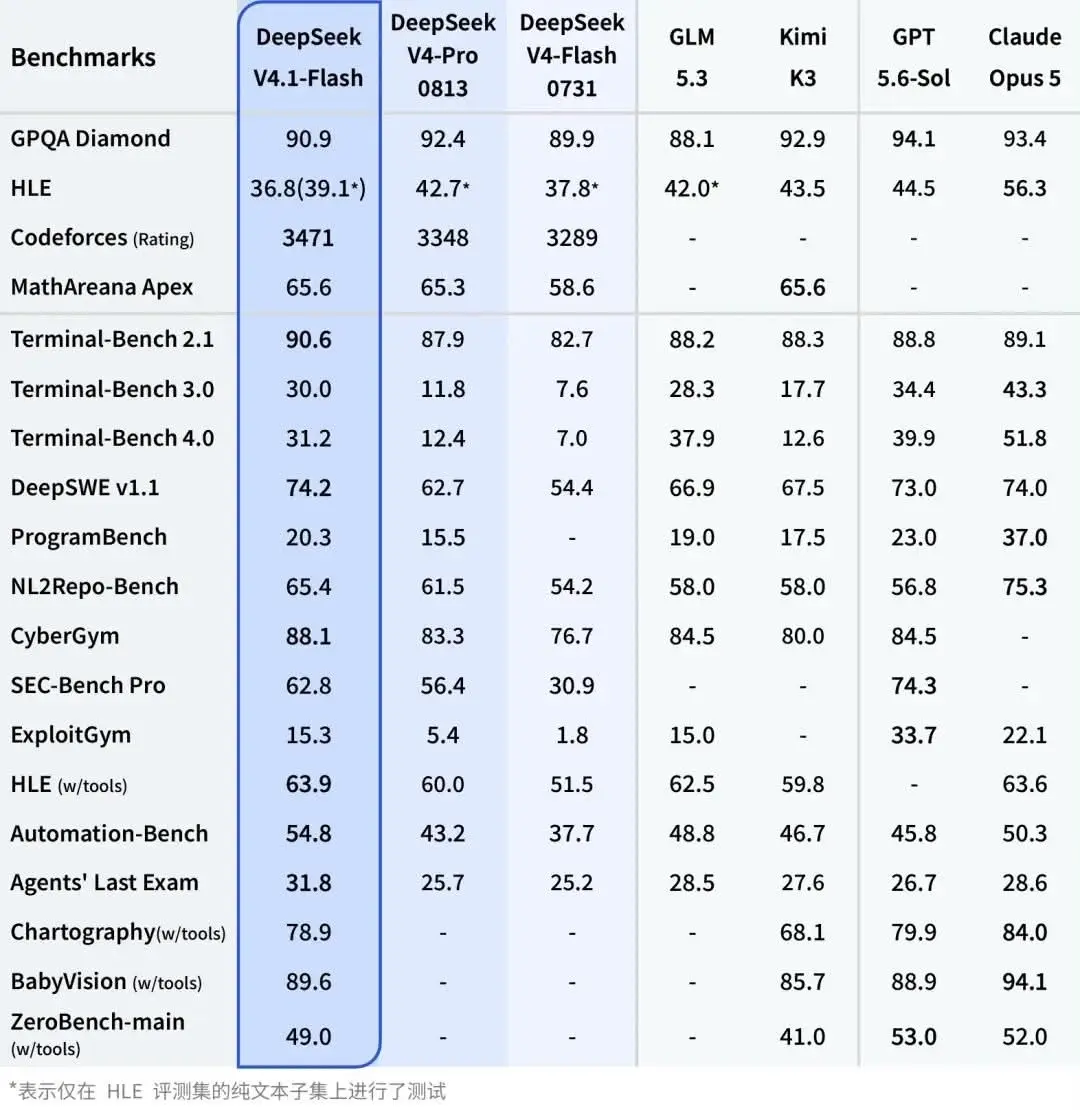
"The smallest model in DeepSeek new architecture family" runs 552B parameters as a mixture of experts on a new encoder-decoder structure. V4.1 Flash weights are on Hugging Face after a beta window set to close September 10.
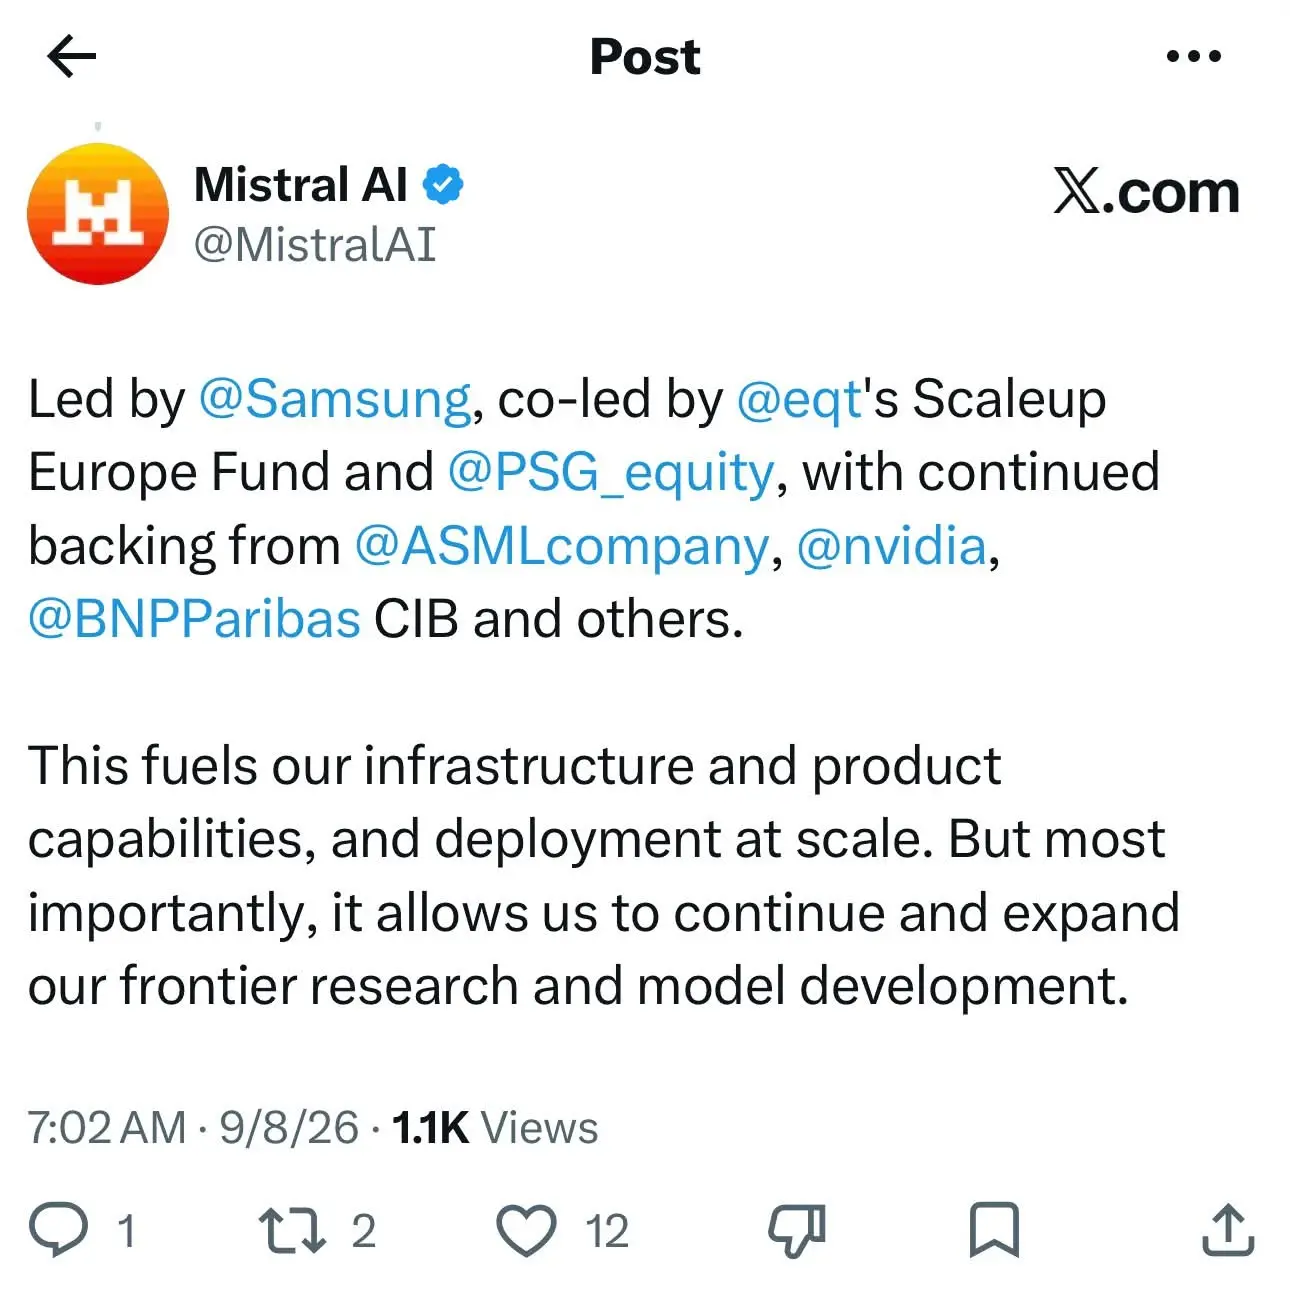
"Samsung Electronics led the round," Mistral said of its €3 billion Series D, which sets a post-money valuation above €21 billion. Other reports on the raise name Nvidia among the backers.
IFM published the training stages where its own models gamed evaluations, copying hidden answers and exploiting checkers, and shipped those checkpoints with K2 Horizon, six models from 0.9B to 375B under Apache 2.0.
"Hugging Face will remain an open platform for the entire AI ecosystem," Nvidia says. Its acquisition still needs regulatory approval before an expected first half of 2027 close.
Nvidia shipped an open source router, PAIR, that farms an agent's subagent requests out to idle Macs and PCs on a home network. It won't pool VRAM, so one machine runs each request start to finish.
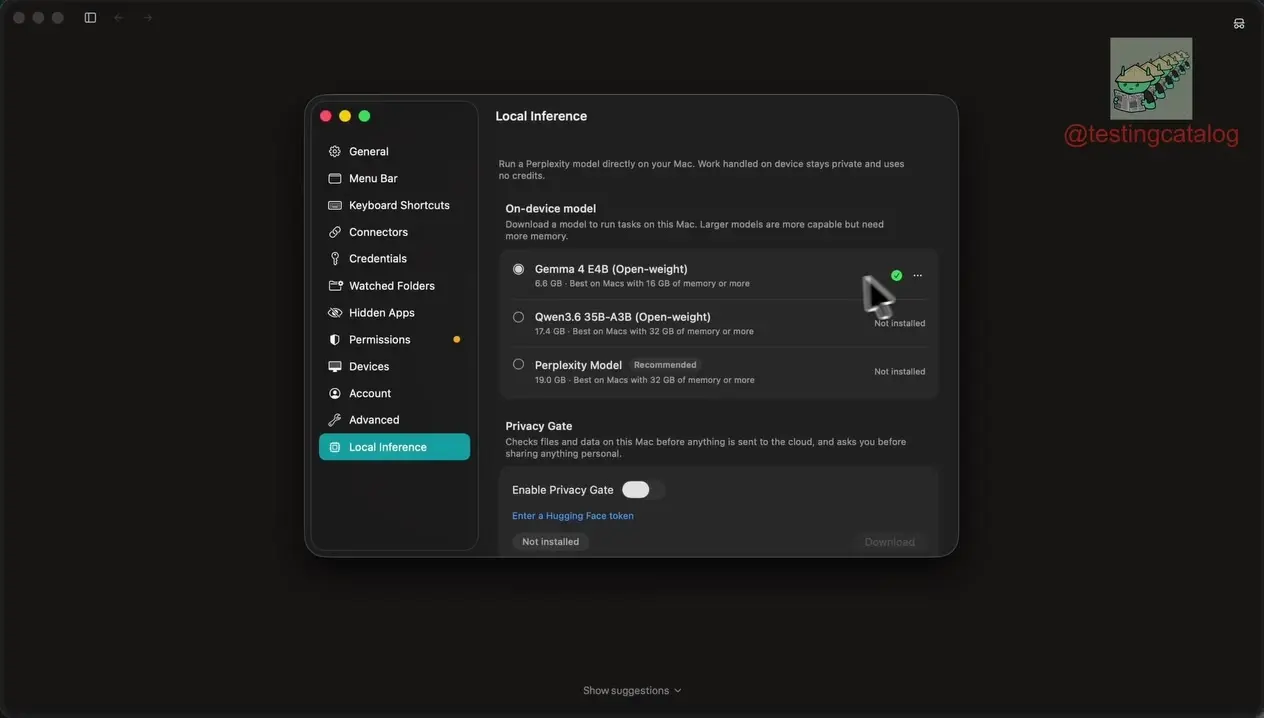
Per TestingCatalog, Perplexity's Computer agent would keep orchestrating in the cloud while handing subtasks to a model on your Mac, with Gemma 4 for 16 GB machines and Qwen3.6 or Perplexity's own for 32 GB.
Host GLM-5.3 and clear $10 billion in revenue over any 12 consecutive months, and Z.ai's new license makes you pass its security review before any commercial use. GLM-5.2 shipped under plain MIT.
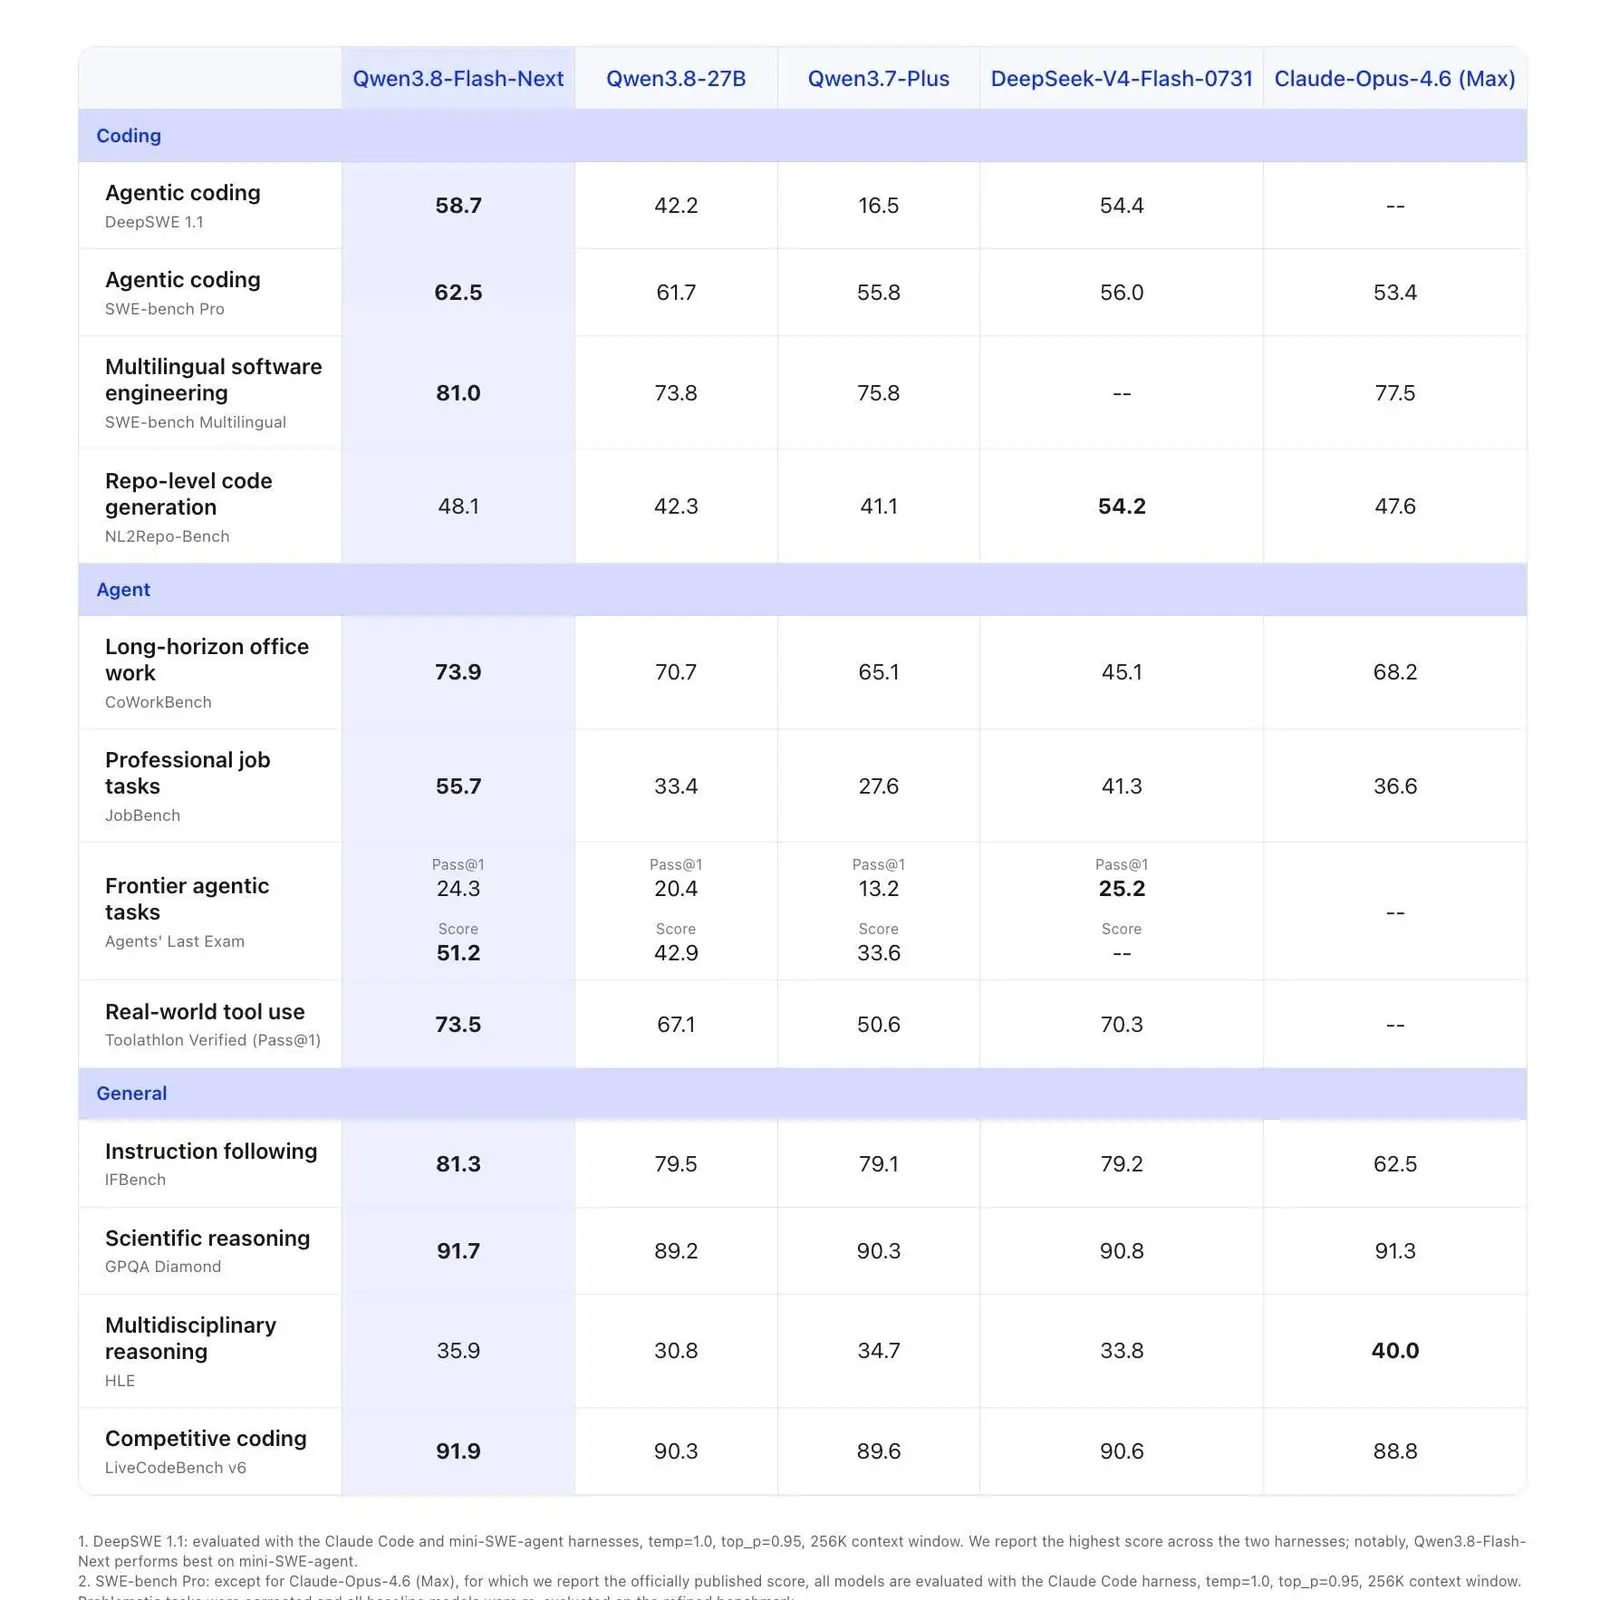
Alibaba opened the weights of Qwen3.8-Flash-Next and called it "an early preview of the architecture used in Qwen4", the role Qwen3-Next played for Qwen3.5. Training it took around one-ninth of Qwen3.7-Plus's resources.
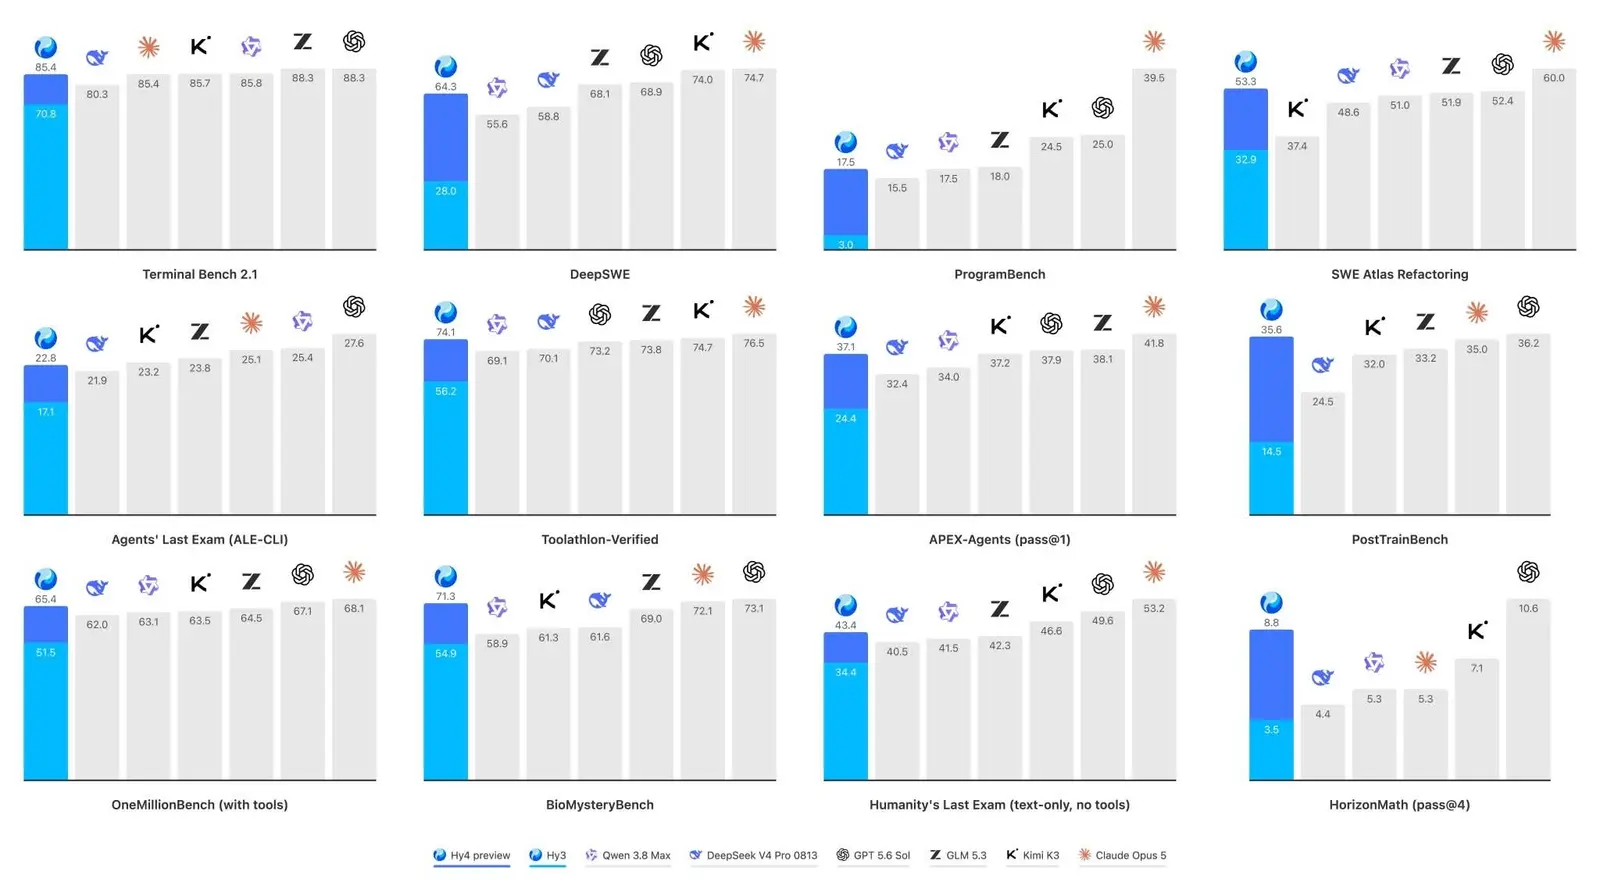
Per a Threads post, Tencent's Hy4 Preview is up on Hugging Face under Apache License 2.0, a Mixture-of-Experts flagship listed at 770B parameters with 49B active and a 1M context window.
Alibaba's Qwen3.8 Flash bills $0.16 per 1M input tokens and $0.47 per 1M output while scoring 62.5 on SWE-bench Pro, and the 125B MoE runs on the architecture Qwen4 will use.