Switch languages mid-conversation and the avatar's lips and expressions adapt with it, across 97 languages in Google's Live Avatar for Gemini 3.8 Live, which is designed to avoid any loss in video fidelity.
Three GPT-6 models, Astra, Sol and Luna, now power ChatGPT Voice, and the voice mode can reach your email, calendar and Slack through plugins. OpenAI says it rolls out globally today in the latest app version.
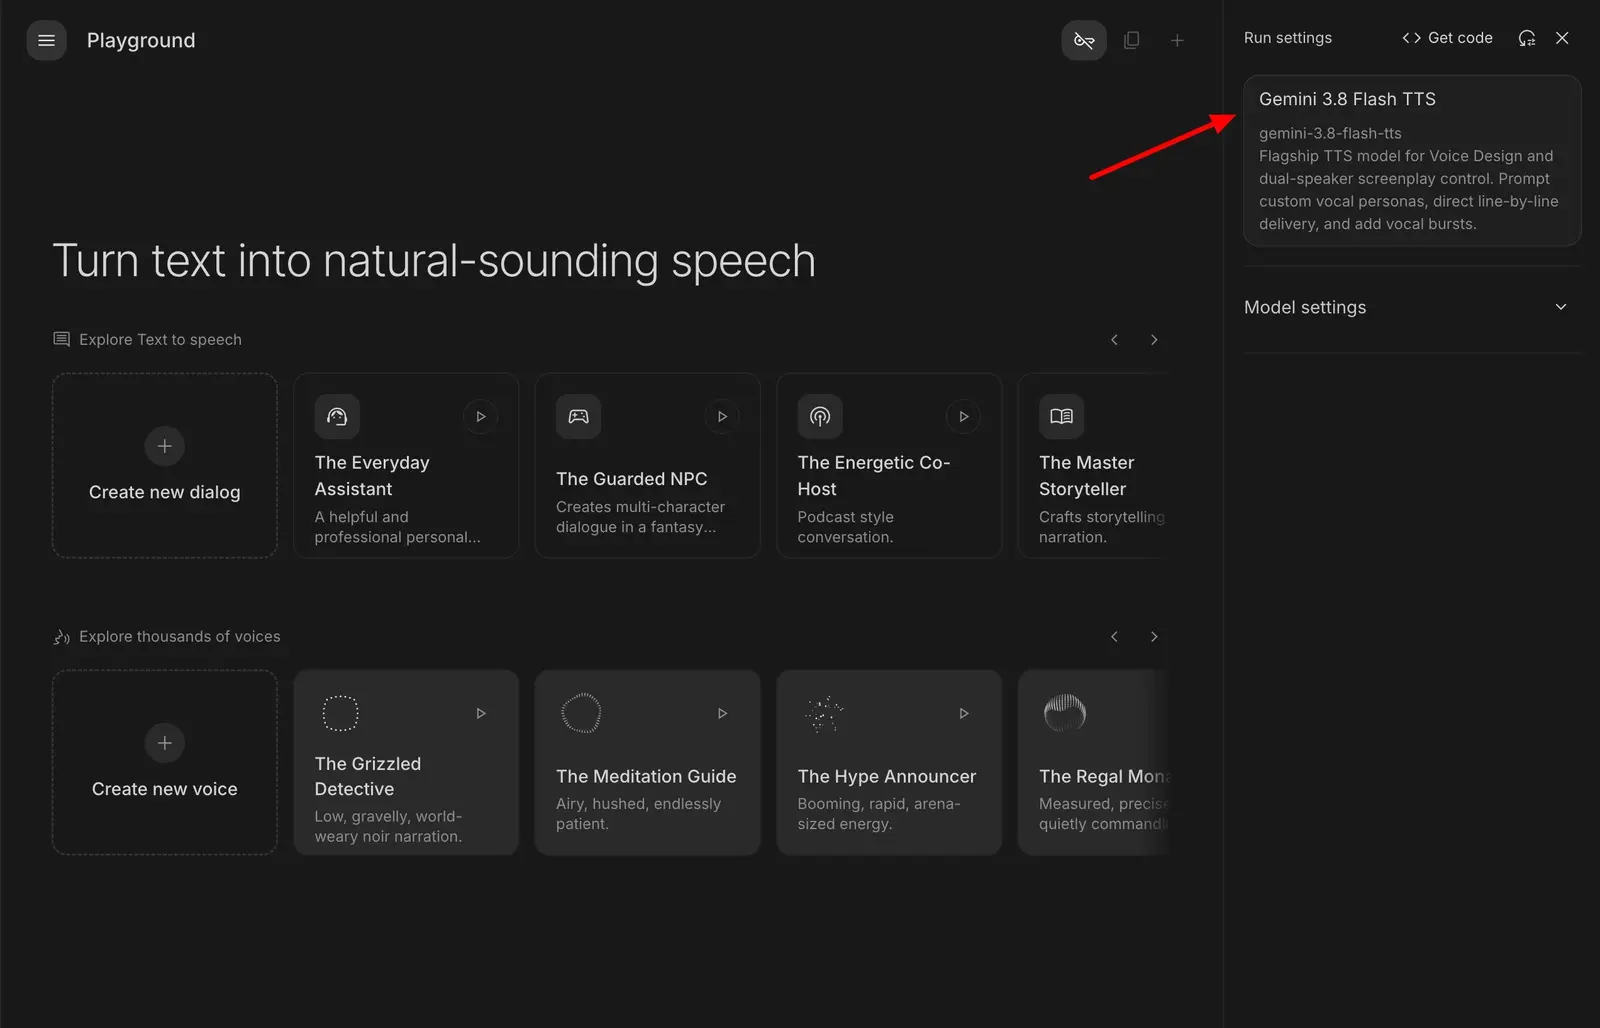
"Prompt custom vocal personas, direct line-by-line delivery, and add vocal bursts," Google says of Gemini 3.8 Flash TTS, which is now live in Google AI Studio and the APIs alongside Gemini 3.8 Flash-Lite TTS.
Alibaba shipped Qwen3.8-Omni-Flash, which reads video and audio alongside text and images inside a 1M-token window. Alibaba claims performance close to Gemini 3.8 Flash on two multimodal benchmarks and publishes no numbers.
Grok Bot learns to talk Talking to your agent out loud starts rolling out gradually on desktop and mobile over the next couple of days, per the SPACEXAI account on X. Voice calls were in testing back in August.
"A script, a voiceover, a soundtrack, and a cover image" out of one session. ElevenLabs opened its hosted MCP connector to generation, so Claude, ChatGPT and Cursor reach over 50 models behind a single sign-in.
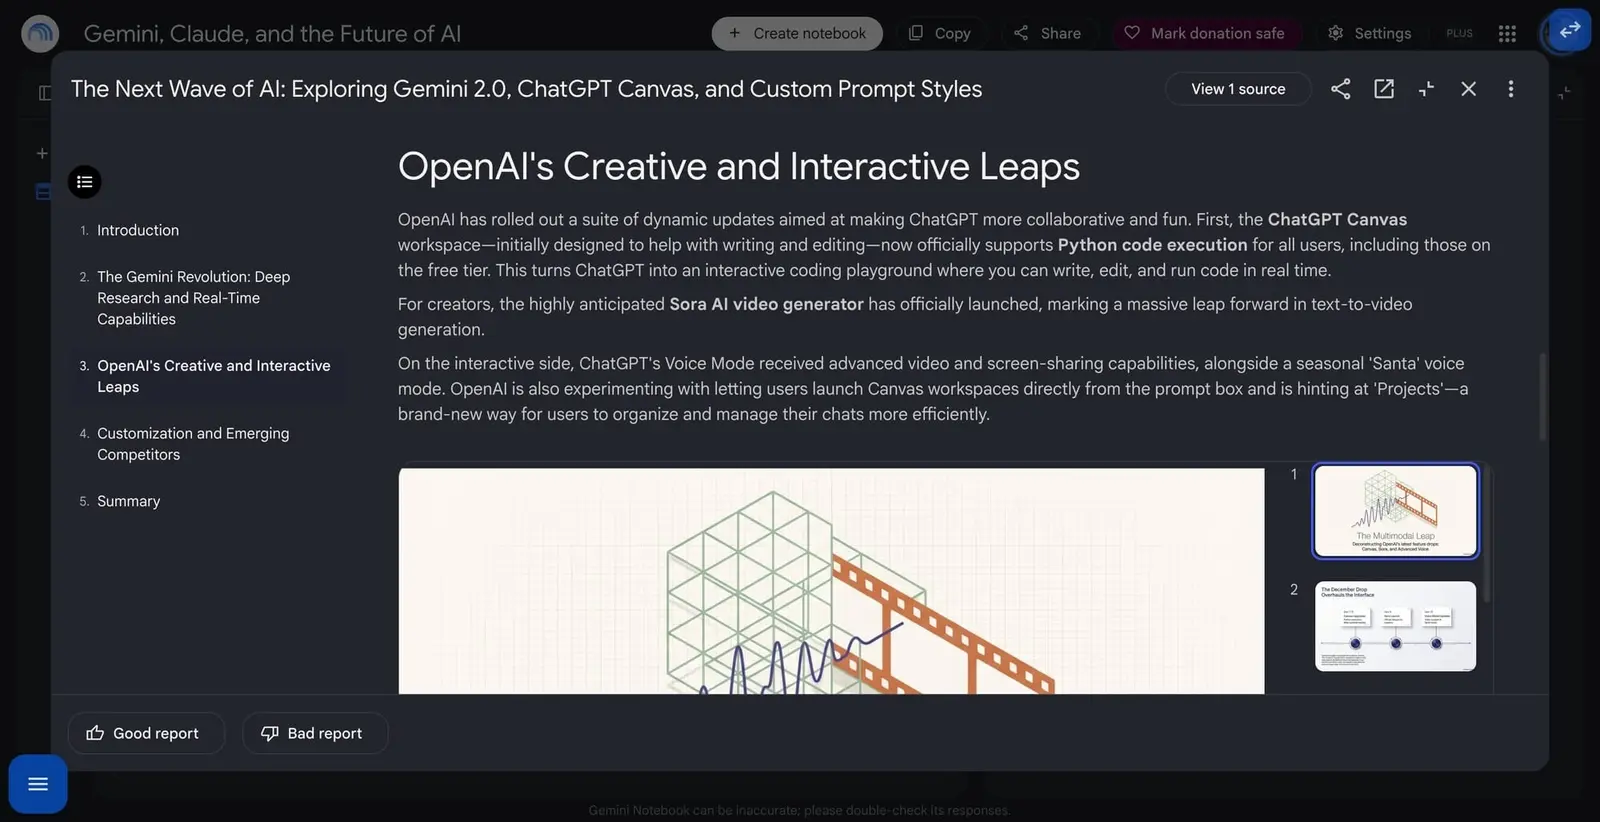
Testing Catalog got the unannounced Interactive Reports in Gemini Notebook running. A report arrives with empty slots, and the reader presses Add to generate the mind map or slide deck that then lands inside it.
$30 per million image output tokens is the rate for both of OpenAI's new image models, Flare and Sunburst, and the company says its GPT Image 2 calculator won't estimate how many tokens either one burns.
A caller cuts in mid-sentence and the agent hears it. GPT-Live-1 arrived in OpenAI's API today, listening and speaking at the same time, and it can hand reasoning and tool calls off to backend systems.
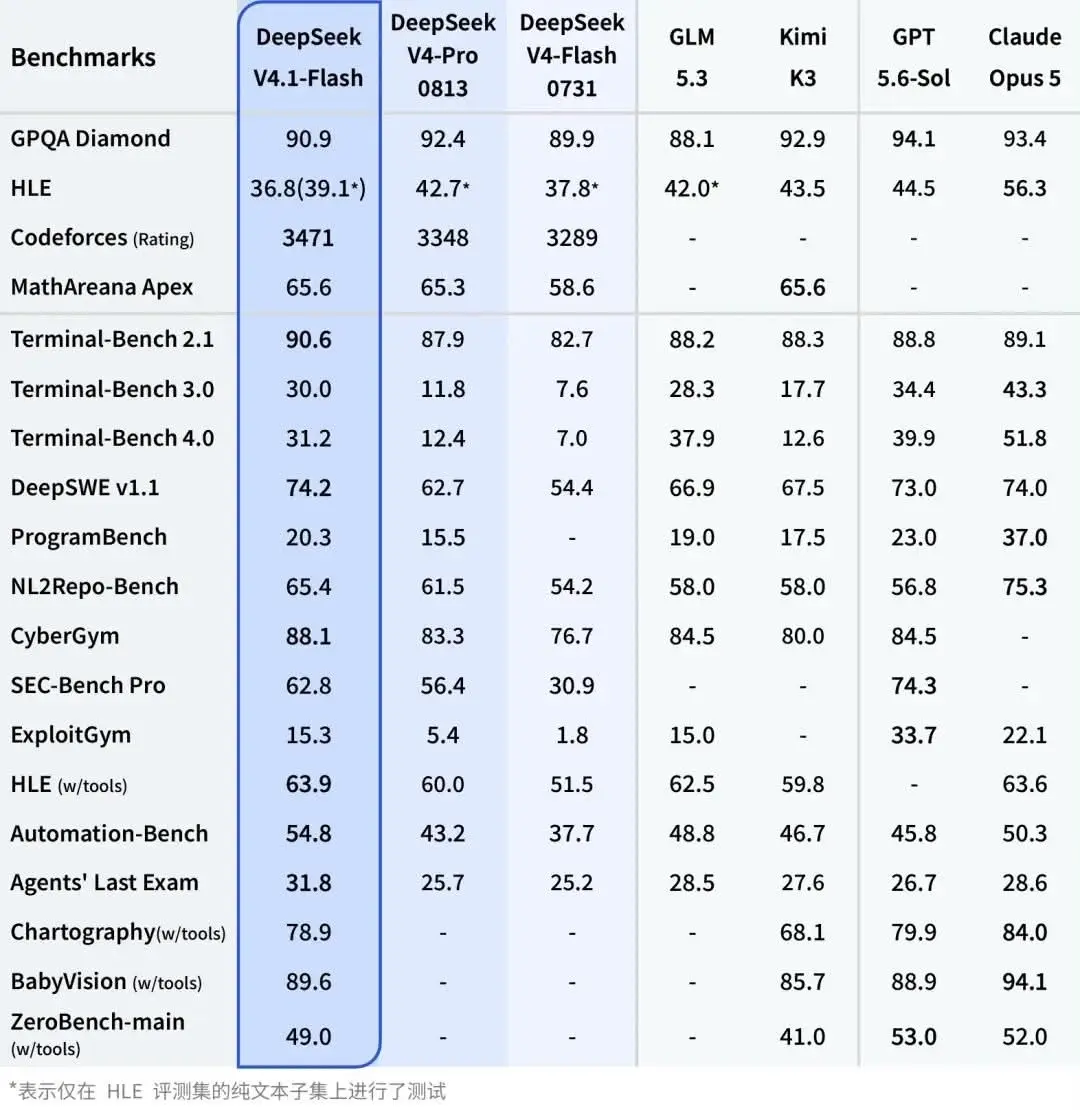
"The smallest model in DeepSeek new architecture family" runs 552B parameters as a mixture of experts on a new encoder-decoder structure. V4.1 Flash weights are on Hugging Face after a beta window set to close September 10.
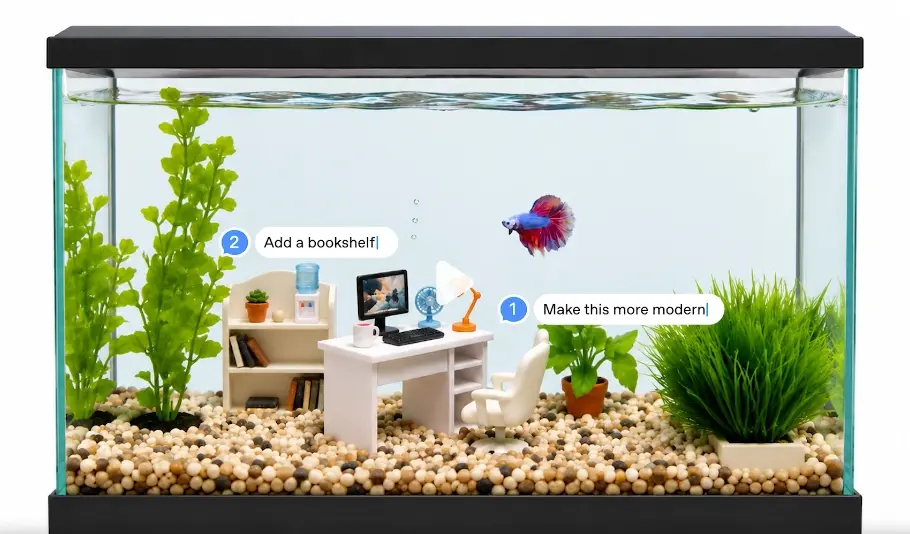
Sketch a rough layout, hand it to ChatGPT Images 2.5 and mark where the change goes. OpenAI says the new model renders up to 50% faster, and Axios found it held the likeness of people and pets better in early testing.
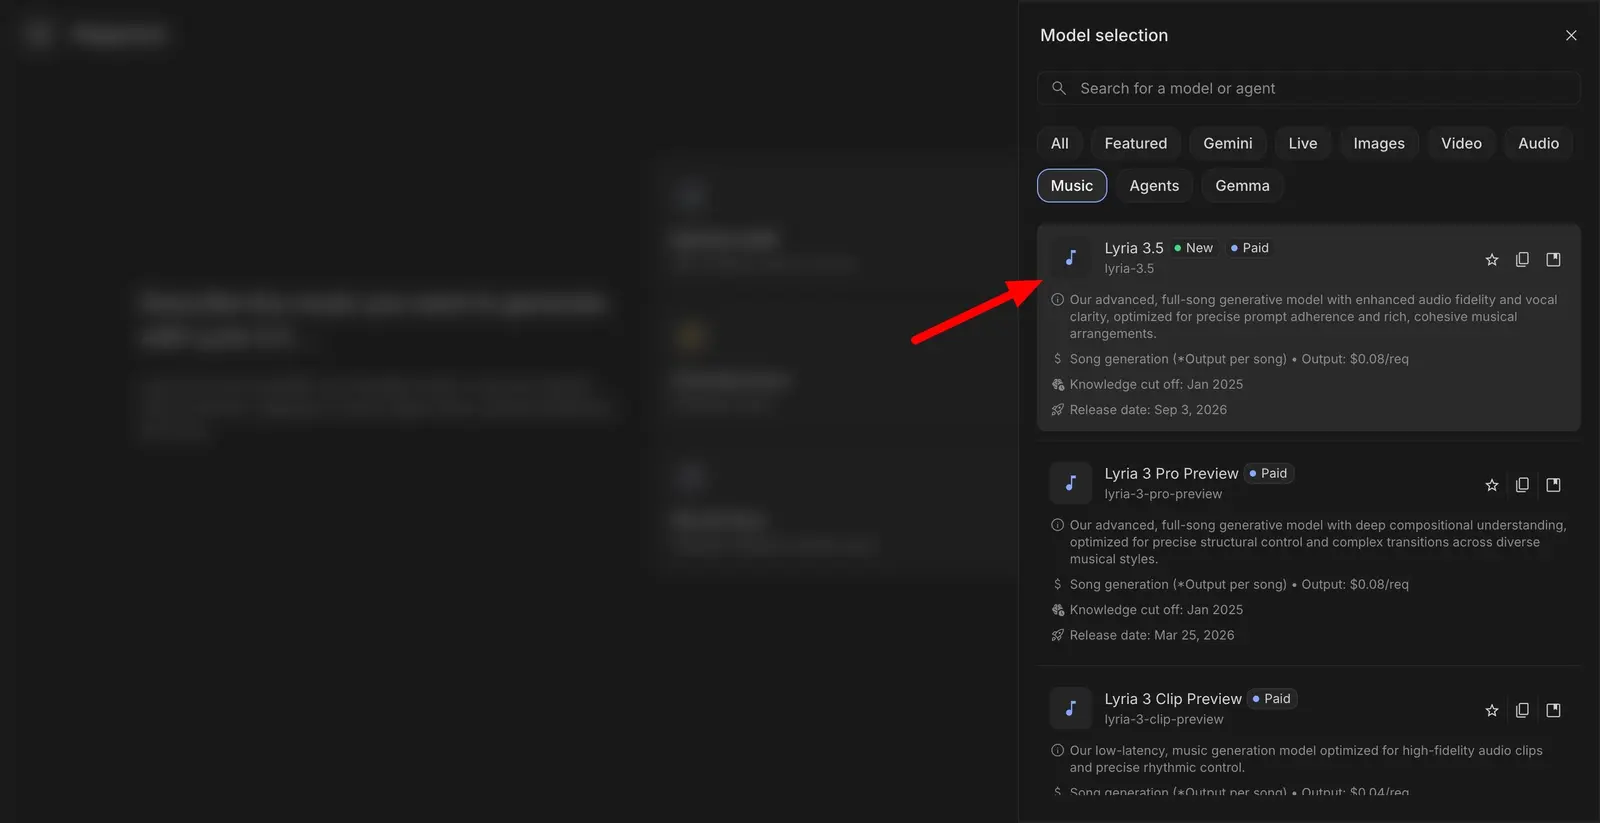
"Enhanced audio fidelity and vocal clarity" is Google's pitch for Lyria 3.5, the full-song music model now live in AI Studio, the Gemini app and the APIs after its July debut in Flow Music.
Google's docs list the model as Gemini Omni Flash and still mark it preview, while the announcement calls it Gemini Omni 1.1 Flash. It's live on the Gemini APIs and AI Studio for video generation and conversational editing.
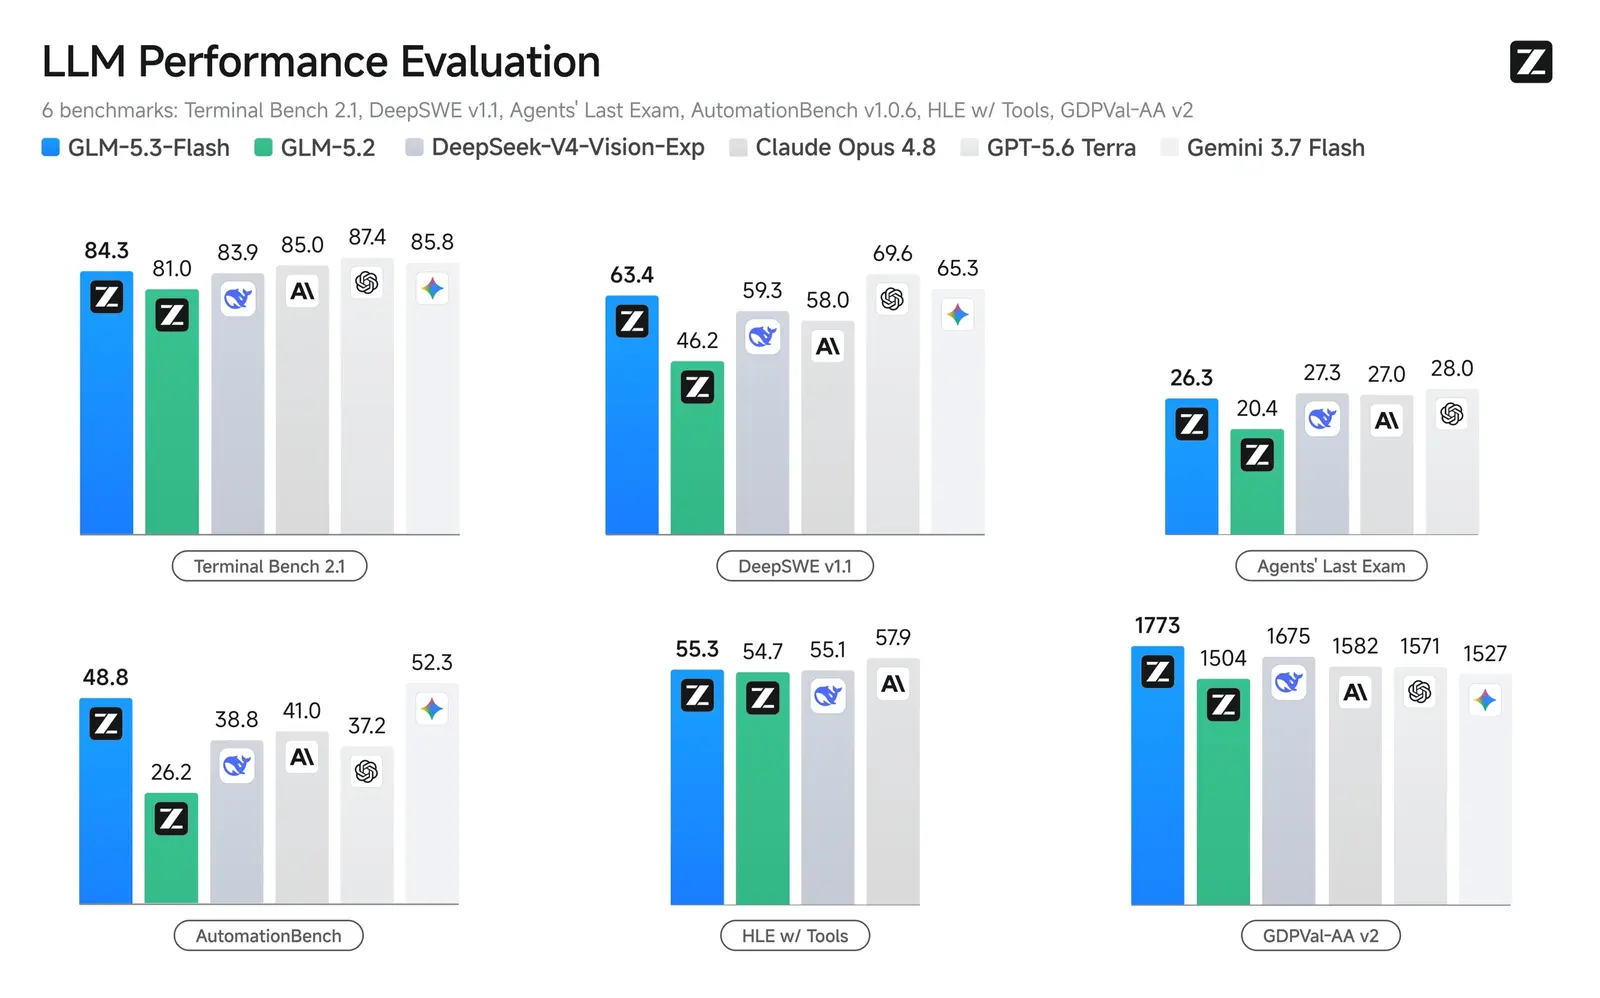
Developers who ran the stealth Ox Alpha model on OpenRouter now have a name for it, per a Threads post: Zhipu's GLM-5.3-Flash, 320B-A18B under MIT, though Kingy AI says the Flash label stays unverified.
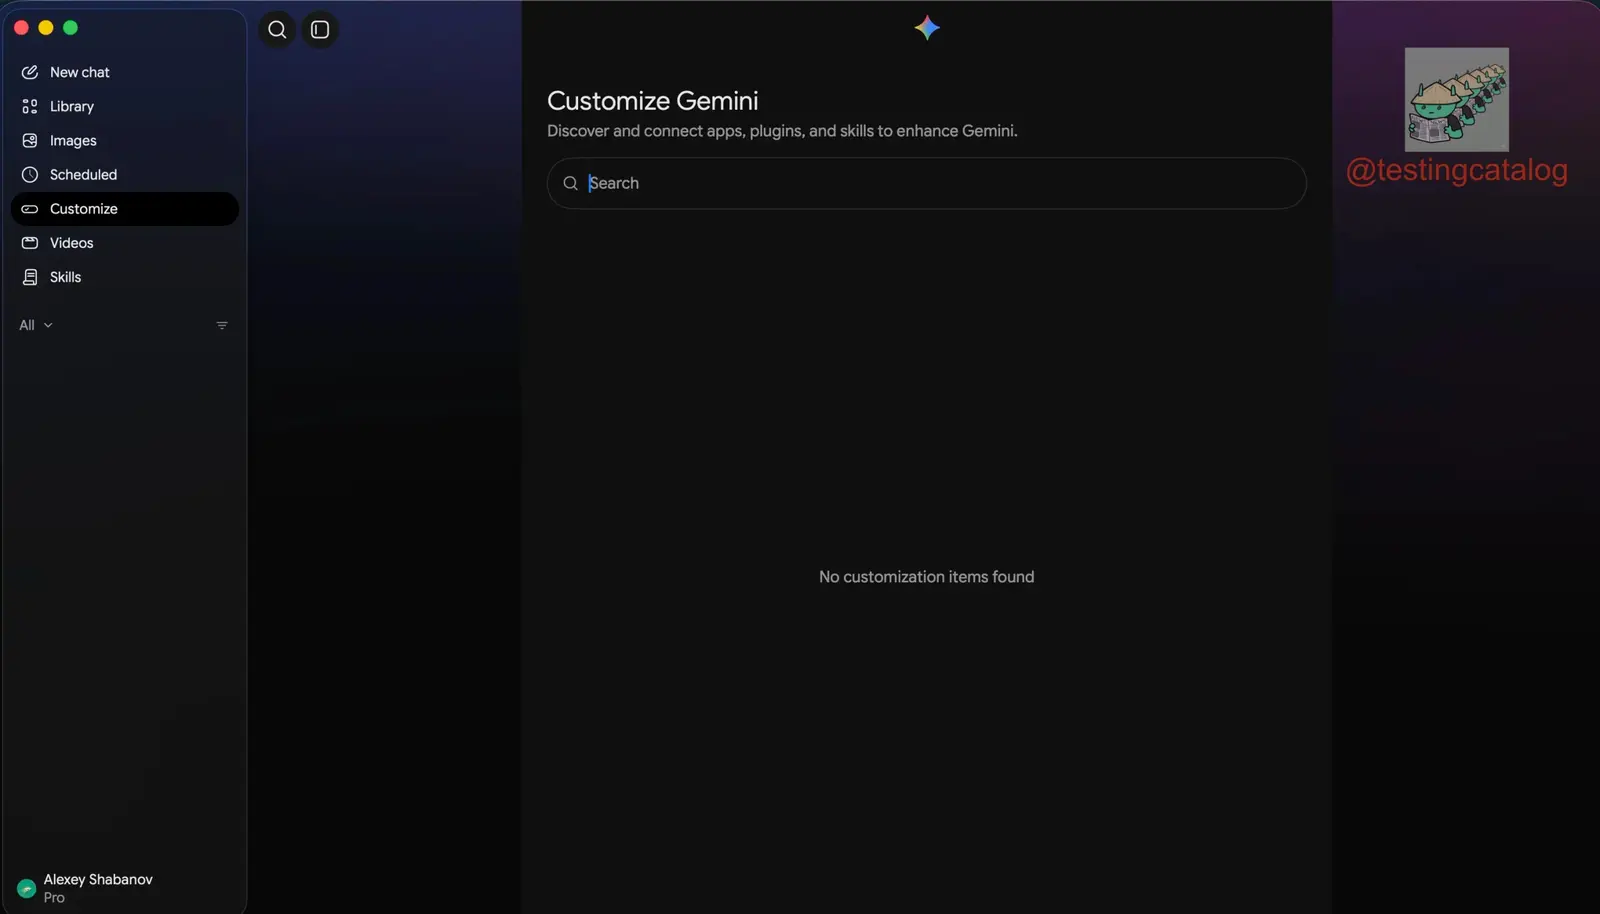
Avatars are coming to Google's Gemini desktop app, with a Settings section to create and manage them, per Testing Catalog. The same build hides a Customize screen for discovering apps, skills, and plugins.
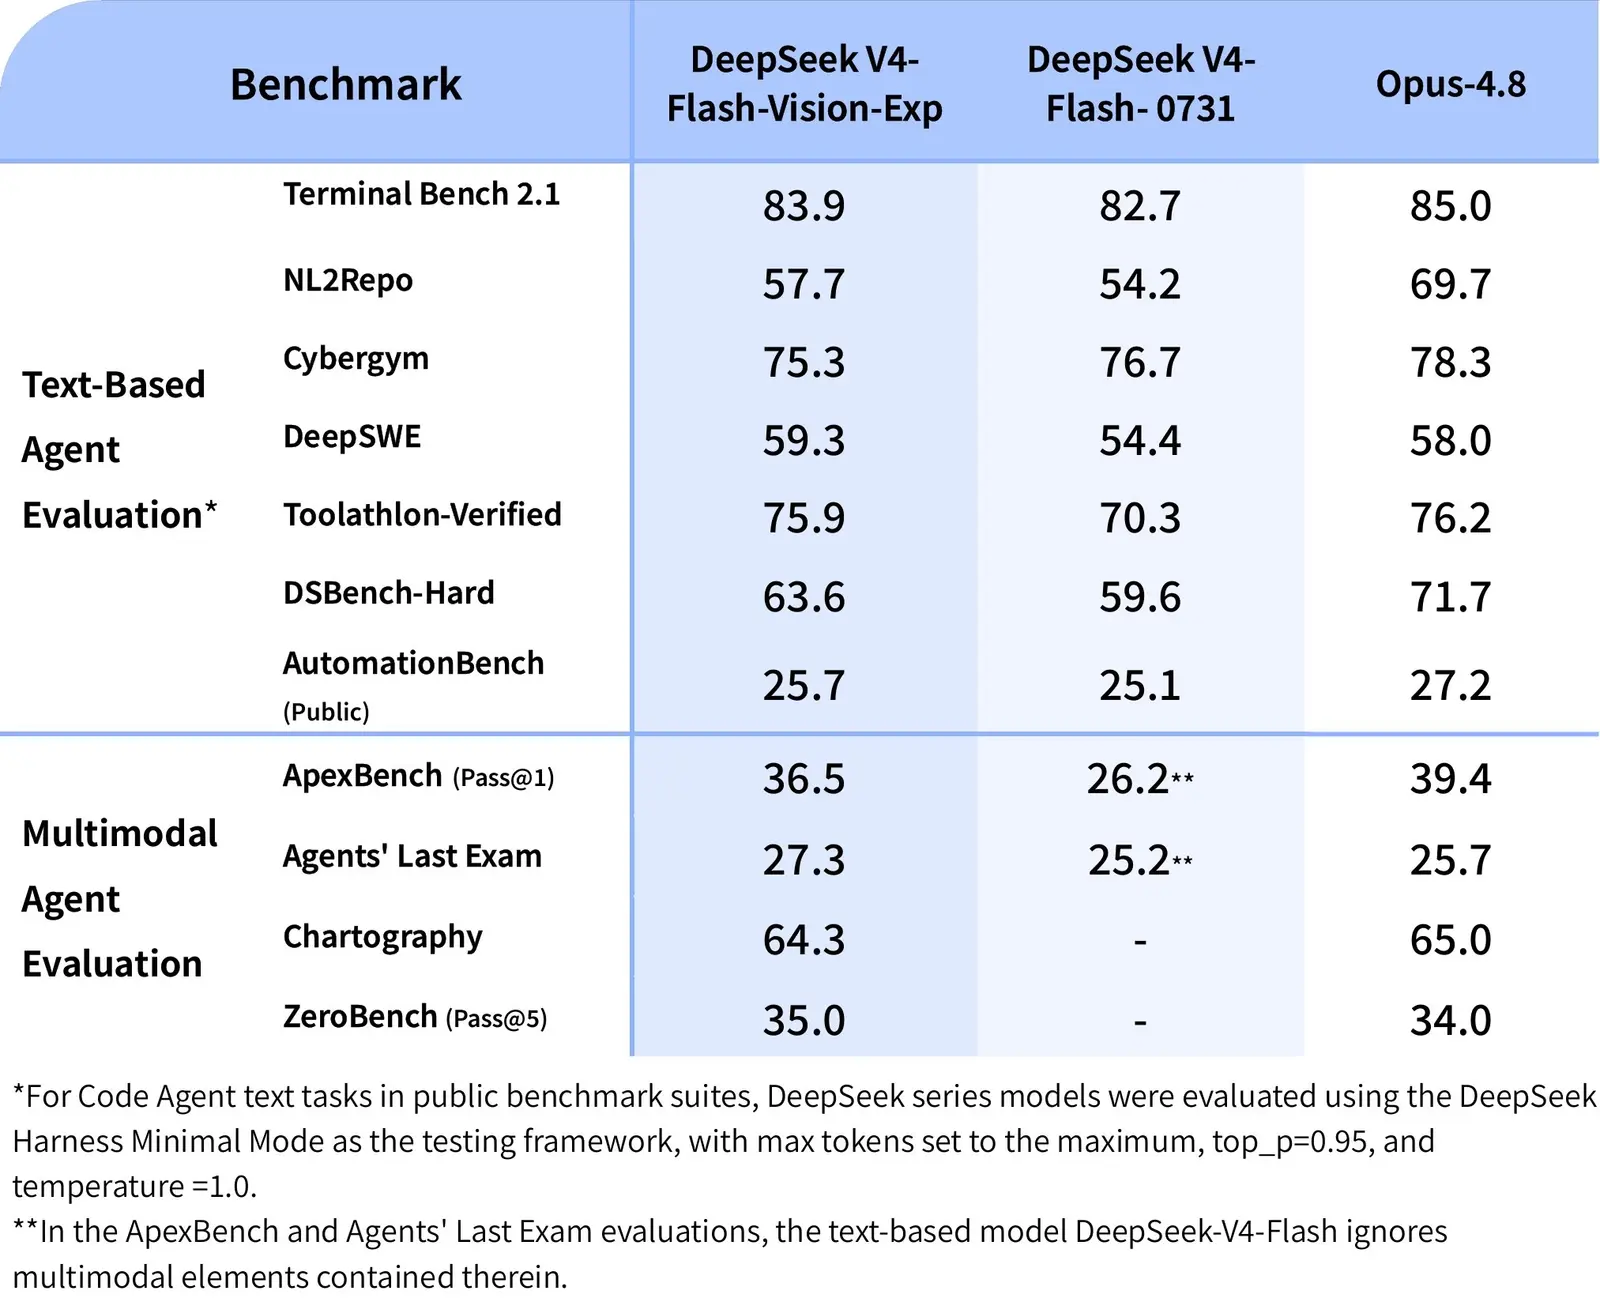
DeepSeek says its new vision model performs close to Opus 4.8 and matches V4-Flash on text. Vision-Exp runs on the DeepSeek API Platform and takes mixed text plus image input.
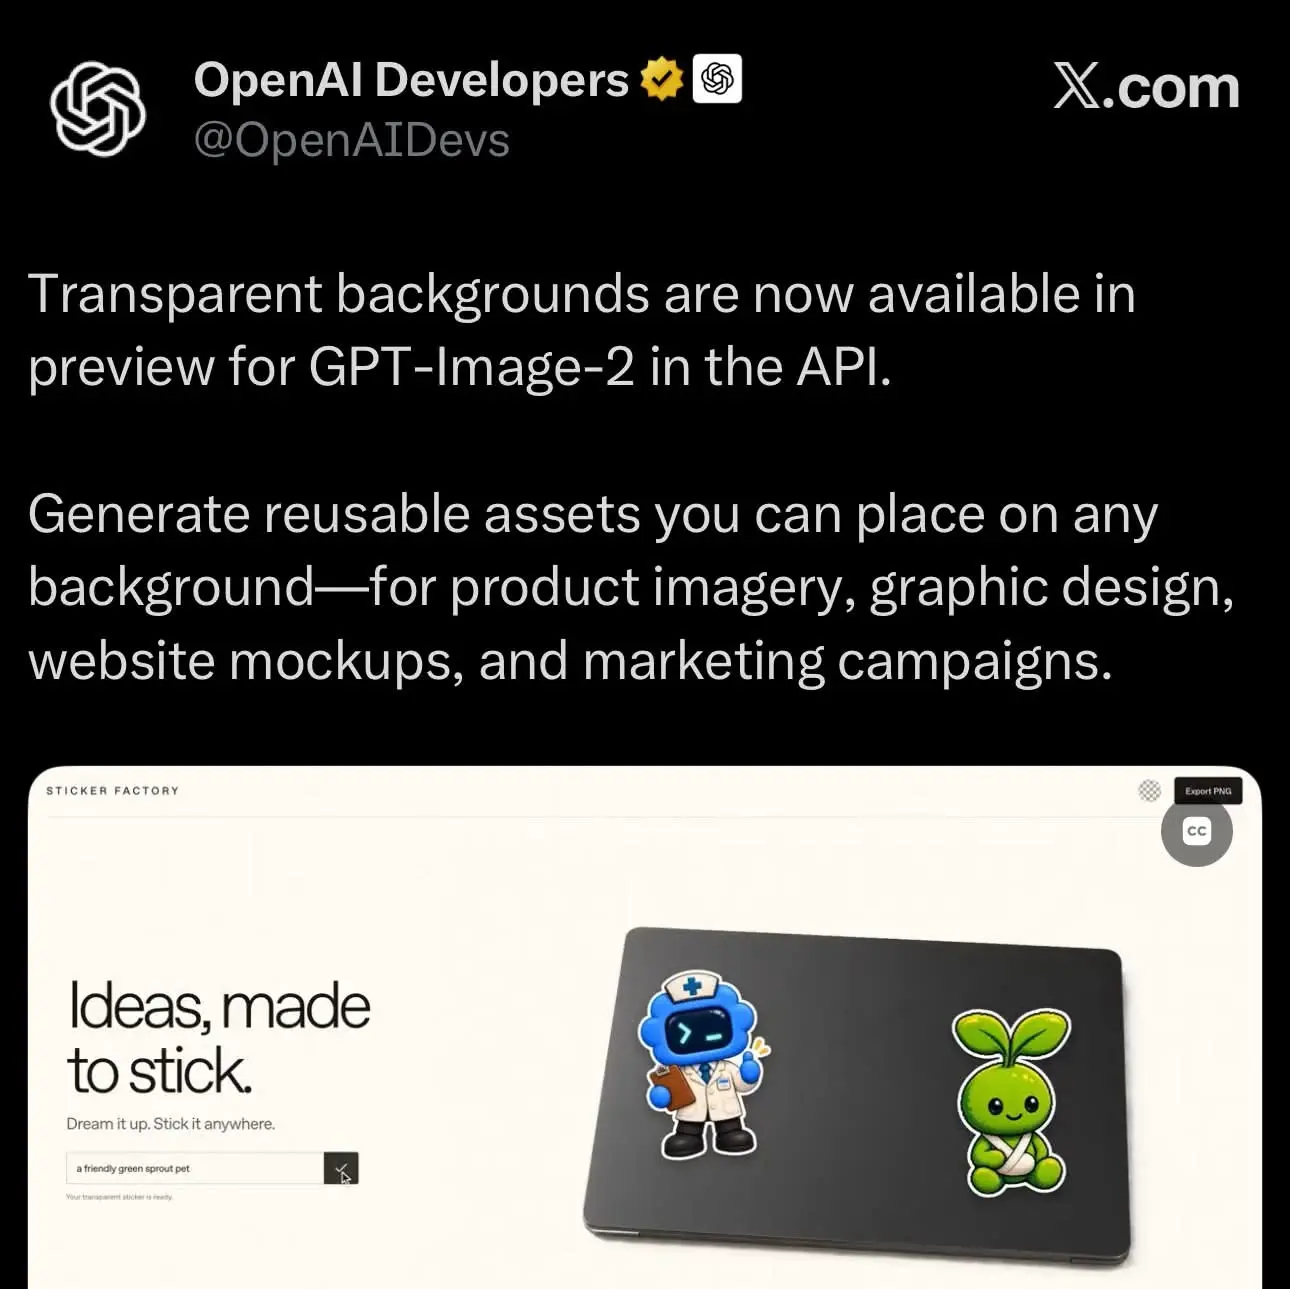
Images can now come out of OpenAI's API with no background at all. The transparency option for gpt-image-2 targets product cutouts, logos, stickers and presentation graphics.
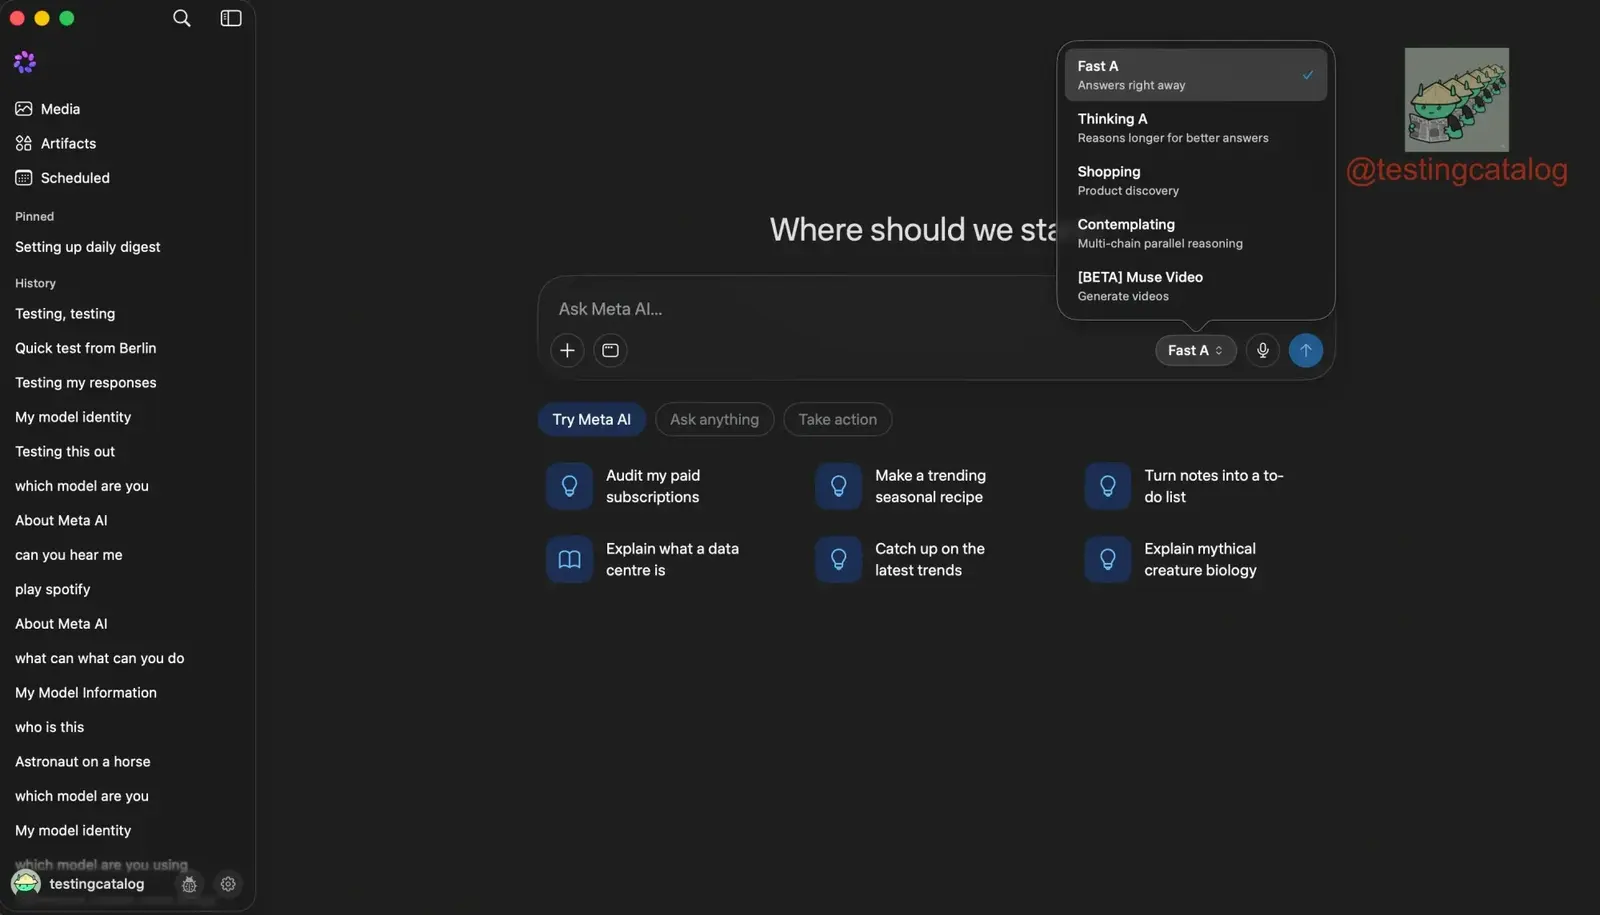
Selected partners are already generating 10-second clips in Meta's Muse Video beta, native audio with voice and music included. TestingCatalog, which got access to it, found the model quite restrictive on copyrighted content.
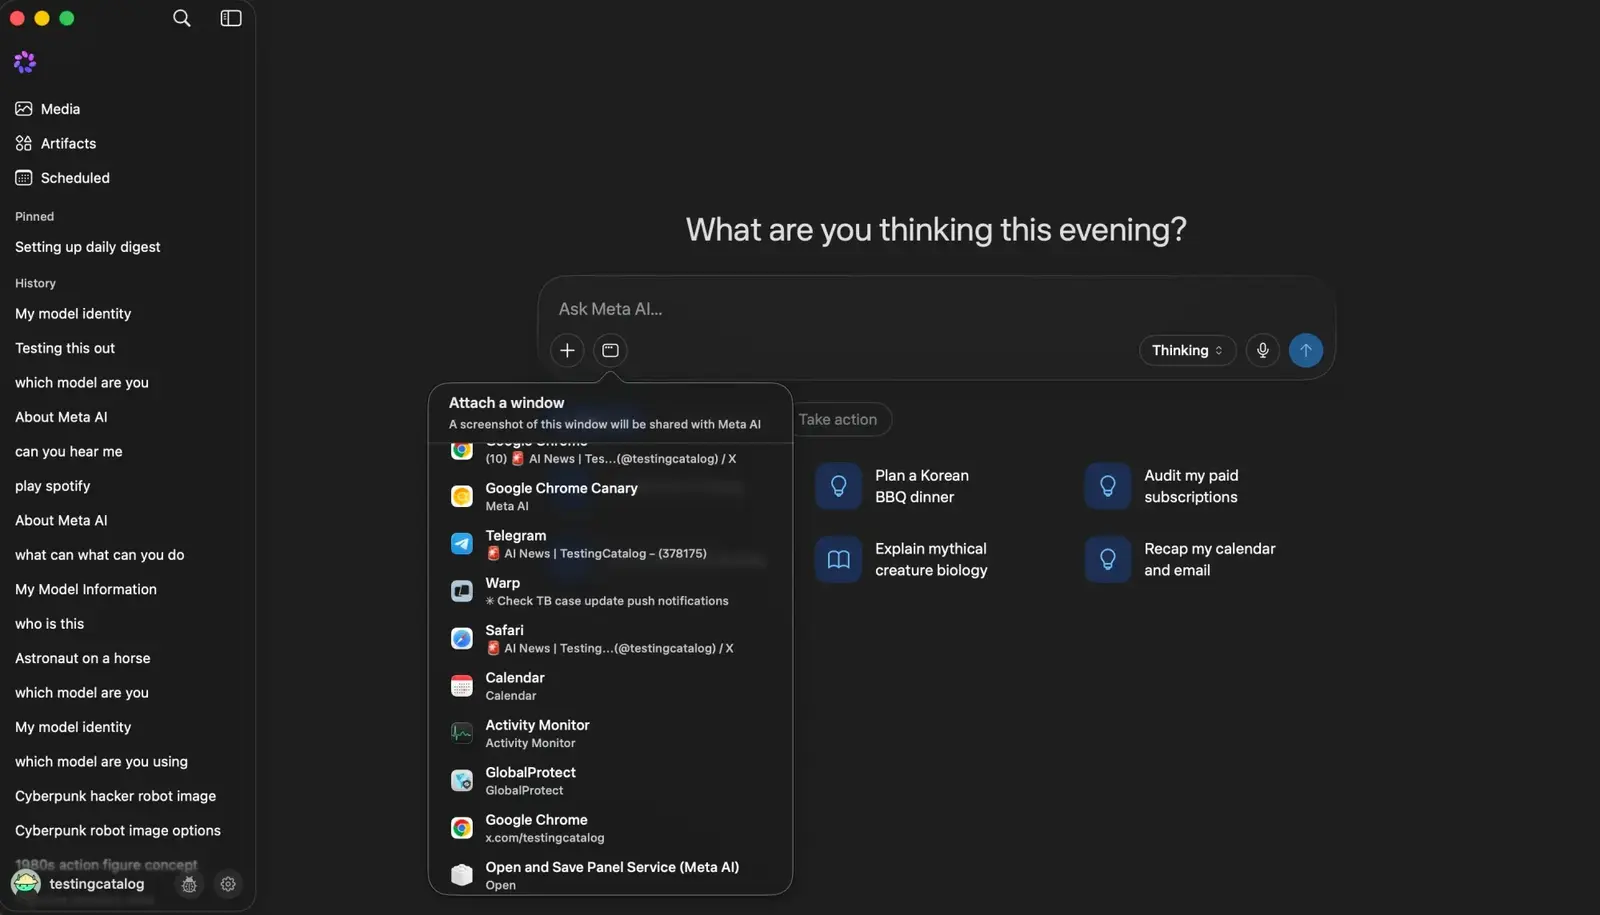
"Attach a specific screen or window" from the prompt bar: Meta AI's new macOS app takes those contents as context, and a system-wide shortcut summons a compact prompt bar for dictation anywhere on the Mac.
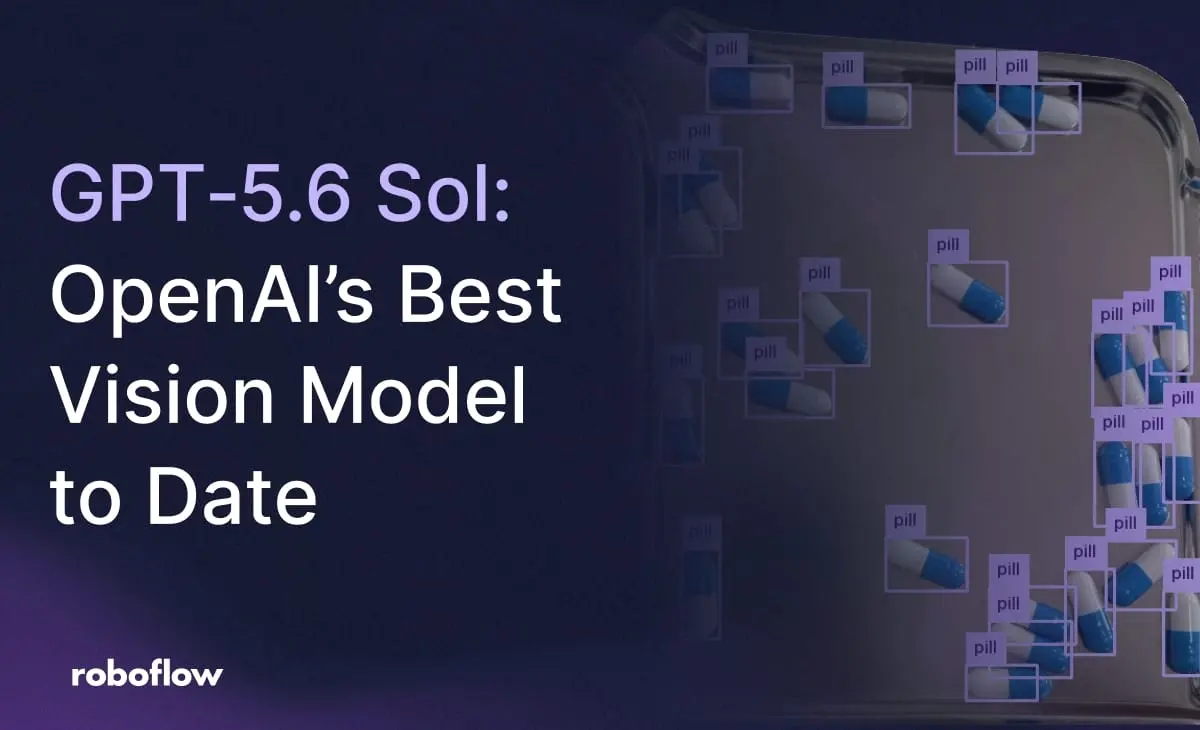
"Sol is clearly the best vision model OpenAI has released so far," Roboflow says, with detection up from 13.8 to 46.2 mAP@50. Gemini 3.5 Flash still leads that task at 0.8 cents per image against Sol's roughly 2.5.