
Agents building agents top out at 23.9%
Hand an AI coding agent the job of building a customer service agent with no human steering and it fails most of the time. The best of six setups Sierra tested, Claude Opus 5 in Claude Code, passed 23.9% of the tasks in its new Hyper-τ-bench, just ahead of GPT-5.6 Sol in Codex at 22%.
The benchmark hands a developer agent documents, transcripts, an API and a codebase from a simulated business, then tests whatever it builds on unseen airline, retail, telecom and banking conversations. Sierra researchers Ben Shi and Keshav Dhandhania found the agents stopped researching the business too early, rarely asked for missing information, and shipped the first design that ran.
Sierra open-sourced the benchmark as τ^τ-bench, and the paper went up on September 4.
Up next
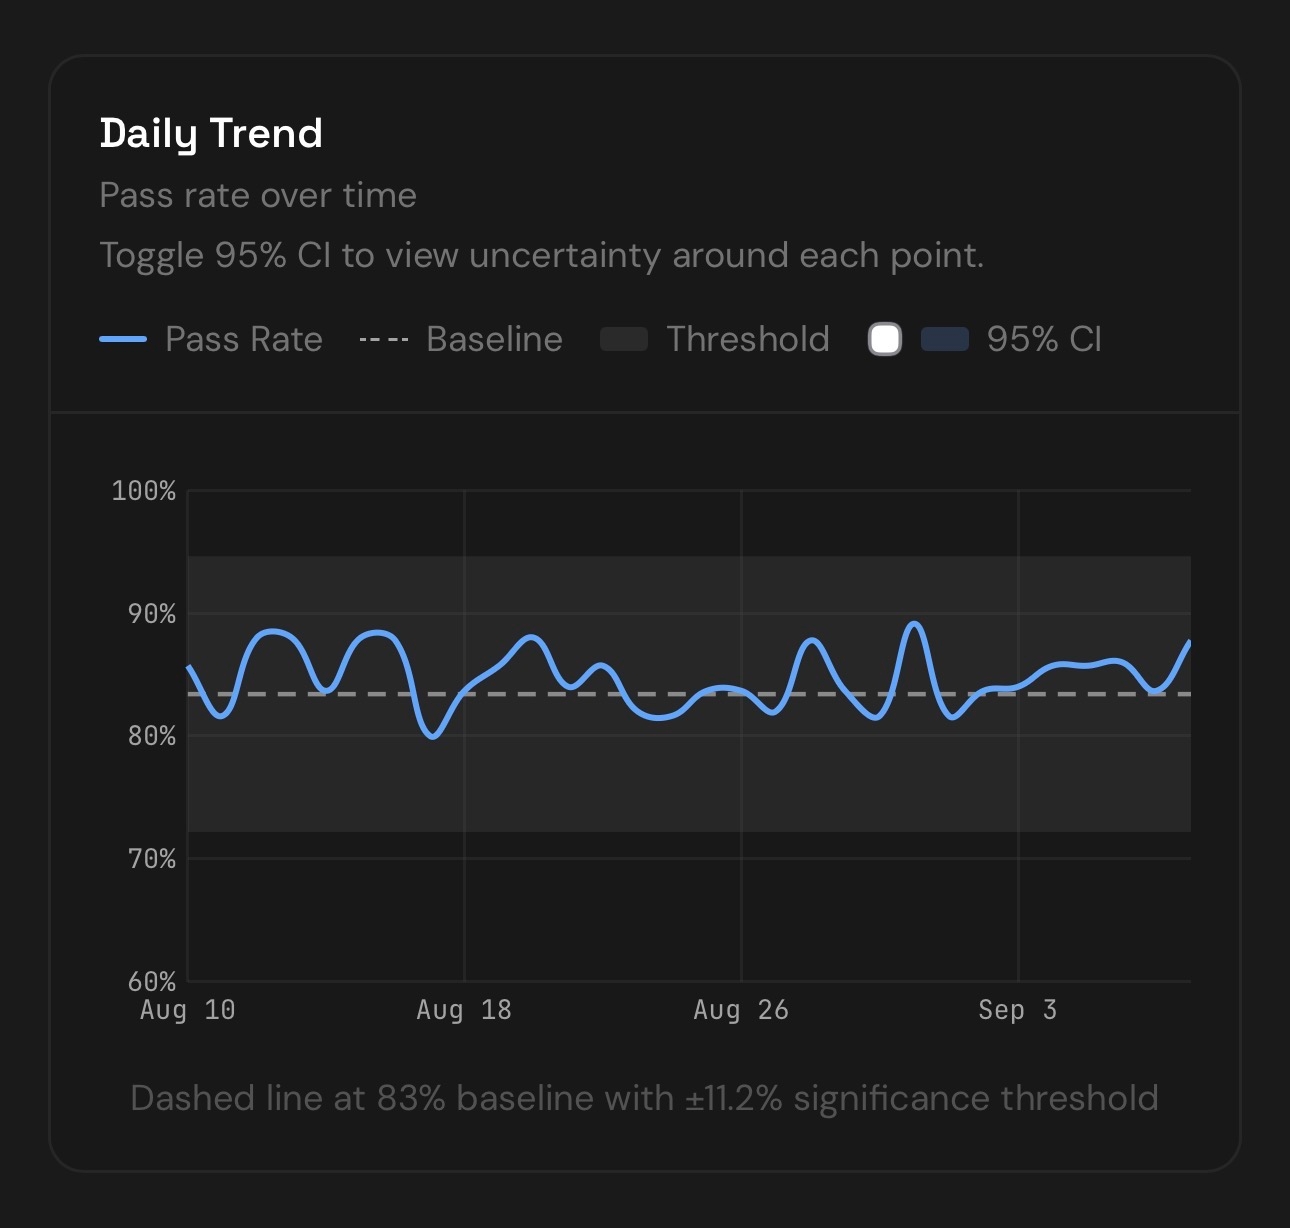
A daily benchmark checks if Codex quietly got worse
Every day MARGIN EVALS pushes a curated slice of SWE-Bench-Pro through Codex CLI to catch gpt-5.6-sol slipping. Sep 8 came back at 88% against an 83% baseline, still inside the band counted as noise.
Related stories
- CodeRabbit’s reviews on Sonnet 5.5 cost about 60% less
- CodeRabbit: Opus 5.5 trades 9 missed bugs for 11 new ones
- A $2 model ranks second on Code Arena
- Open source harness behind the ARC-AGI-3 jump
- Opus 5.5 edges GPT-6 Astra, 58 to 57, on Artificial Analysis
- GPT-6.1 Sol jumps from 5.4% to 86.6% on COBOL migration
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.