
Coding harnesses drove a 70-fold token gap
Before it does any work on a task, OpenClaw sends about 26,000 tokens of its own system prompt, tool descriptions and environment setup. Aider in architect mode sends about 700. That fixed cost multiplied by the number of turns predicted tokens per solved task with an R-squared of 0.99 on both models tested in a June benchmark, one of three harness studies covered in The New Stack’s September 1 analysis.
The benchmark’s author started from a simple complaint: everyone compares models, and almost nobody compares the harness, the CLI tool that wraps the model and drives it. Twelve configurations went through OpenRouter, so each one hit the same API with the same model on the same 12 Python tasks. The harnesses were Aider, Claude Code, Codex, Goose, Hermes, Kilo, Kimi Code, Nanobot, OpenClaw, Opencode and Qwen Code, with Aider’s architect mode counted separately. The suite ran first on DeepSeek V4 Flash, then on Nvidia’s Nemotron 3 Ultra, which has a free tier on OpenRouter, so anyone can rerun it at no cost. Tokens per solved task ran from roughly 3,500 for Aider in architect mode to 292,000 for OpenClaw. Almost every harness solved almost every task, and the author says that is what makes the comparison work: with success roughly equal, what is left to compare is what each harness charged to get there.
Where the floor comes from
Models keep no memory between calls, so each request carries the whole conversation again, the harness’s baggage included. The author’s example: a harness with a 26,000-token floor that takes 15 turns has spent around 390,000 input tokens on scaffolding before any real work counts.
The author expected the costly harnesses to be the ones whose conversations balloon fastest. The data did not show that. Every harness grew its context by a few hundred tokens per turn, so the spread comes from the starting weight and the number of turns.
Startup overhead turned out to be the most stable number in the benchmark: nearly identical on both models for every harness, with a ranking that did not change at all. The cost-per-task ranking moved by a single swap between neighbours. Per the author’s table, Hermes needed about 30,000 to 34,000 tokens per solved task across the two models on a floor of about 2,500. Claude Code needed 52,000 to 55,000 on a floor of about 4,500, Codex 85,000 to 90,000 on about 8,200, and OpenClaw 191,000 to 292,000 on about 26,000. The Codex floor sits close to what a separate traffic capture found in August, when a “Reply with pong.” request from Codex CLI went out at roughly 9,435 tokens.
The benchmark ran one pass per harness, task and model, so it carries no variance estimates, and agent runs are stochastic. The New Stack treats it as evidence for the mechanism and points to Artificial Analysis as the better instrument for comparing production pairings. That index combines DeepSWE, the Laude Institute’s Terminal-Bench v2.1 and Scale AI’s SWE-Atlas-QnA into 326 tasks, averages pass rates over three attempts each, and reports cost per task, token use and wall time. It also publishes a controlled comparison that holds Claude Opus 4.7 fixed while swapping between Claude Code, Cursor CLI and Opencode.
What the invoice counts
Raw tokens do not translate directly into dollars. On the DeepSeek run, Codex billed over a million tokens for the suite, but 77% of them were cache reads charged at roughly a tenth of the normal rate. Priced the way the invoice arrives, Codex came out cheaper per solved task than Claude Code, which used half as many raw tokens.
The author traced Claude Code’s near-zero cache share to the serving path, not to its prompts. It was the only harness talking to OpenRouter through the Anthropic-style messages endpoint, and the gateway’s translation of that format appeared to cut the cache hits the same traffic would have earned through the OpenAI-style endpoint. Gateway behaviour changes, so The New Stack treats this as one observed path.
Composio saw the same asymmetry in August: only 1.5% of Claude Code’s input tokens came from cache, against roughly 70% for Codex and 57% for OMP, with fresh input costing about five times as much as cached. Artificial Analysis builds this into its cost model. It warns that prompt cache hit rates vary widely with provider routing, and it prices cached input and cache writes separately instead of billing every prompt token at the uncached rate.
Cost per success on one model
Composio ran eight harnesses on DeepSeek V4 Flash across 30 enterprise workflows touching Airtable, Gmail, Google Calendar, Google Sheets, GitHub, Slack and PostHog. Each task had a 900-second ceiling and was graded by a programmatic verifier, not an LLM judge, against isolated fixtures seeded with decoys and near-identical keys. Of 240 runs, 129 succeeded.
Cost per successful task ran from $0.028 for Pi Agent to $0.195 for Claude Code, so a Claude Code success cost about seven times as much as a Pi Agent one. DeepAgents matched Claude Code’s pass rate exactly at a quarter of the cost per success. Pass rates ranged from 46.7% for OpenCode to 66.7% for Pi Agent. Composio disclosed that the setup was not a clean single-variable test: Pi ran a different reasoning setting across two model providers, and Prime Agent produced only 24 gradable runs out of 30.
So harness choice moved cost by multiples and task success by percentage points. The New Stack’s recommendation to procurement teams follows from that: ask for cost per verified outcome, and check the cached share on live traffic.
Hard tasks and noisy prompts
On harder work the extra spending did not buy extra results. In the June benchmark, four harnesses spanning the cost range ran ten SWE-bench Lite tasks with generous limits, and all four resolved exactly one task, the same one. Aider got there on 0.8 million tokens, Codex on 15 million. Ten tasks on one model is a thin basis, and The New Stack calls the result suggestive.
The same benchmark injected 100,000 tokens of irrelevant log noise before each task. Seven of the twelve configurations passed the prompt through intact. OpenClaw refused to run, Kimi Code crashed, and Claude Code sent everything and then performed poorly. Kilo and Opencode dropped 83% to 89% of the prompt and still reported success.
Up next
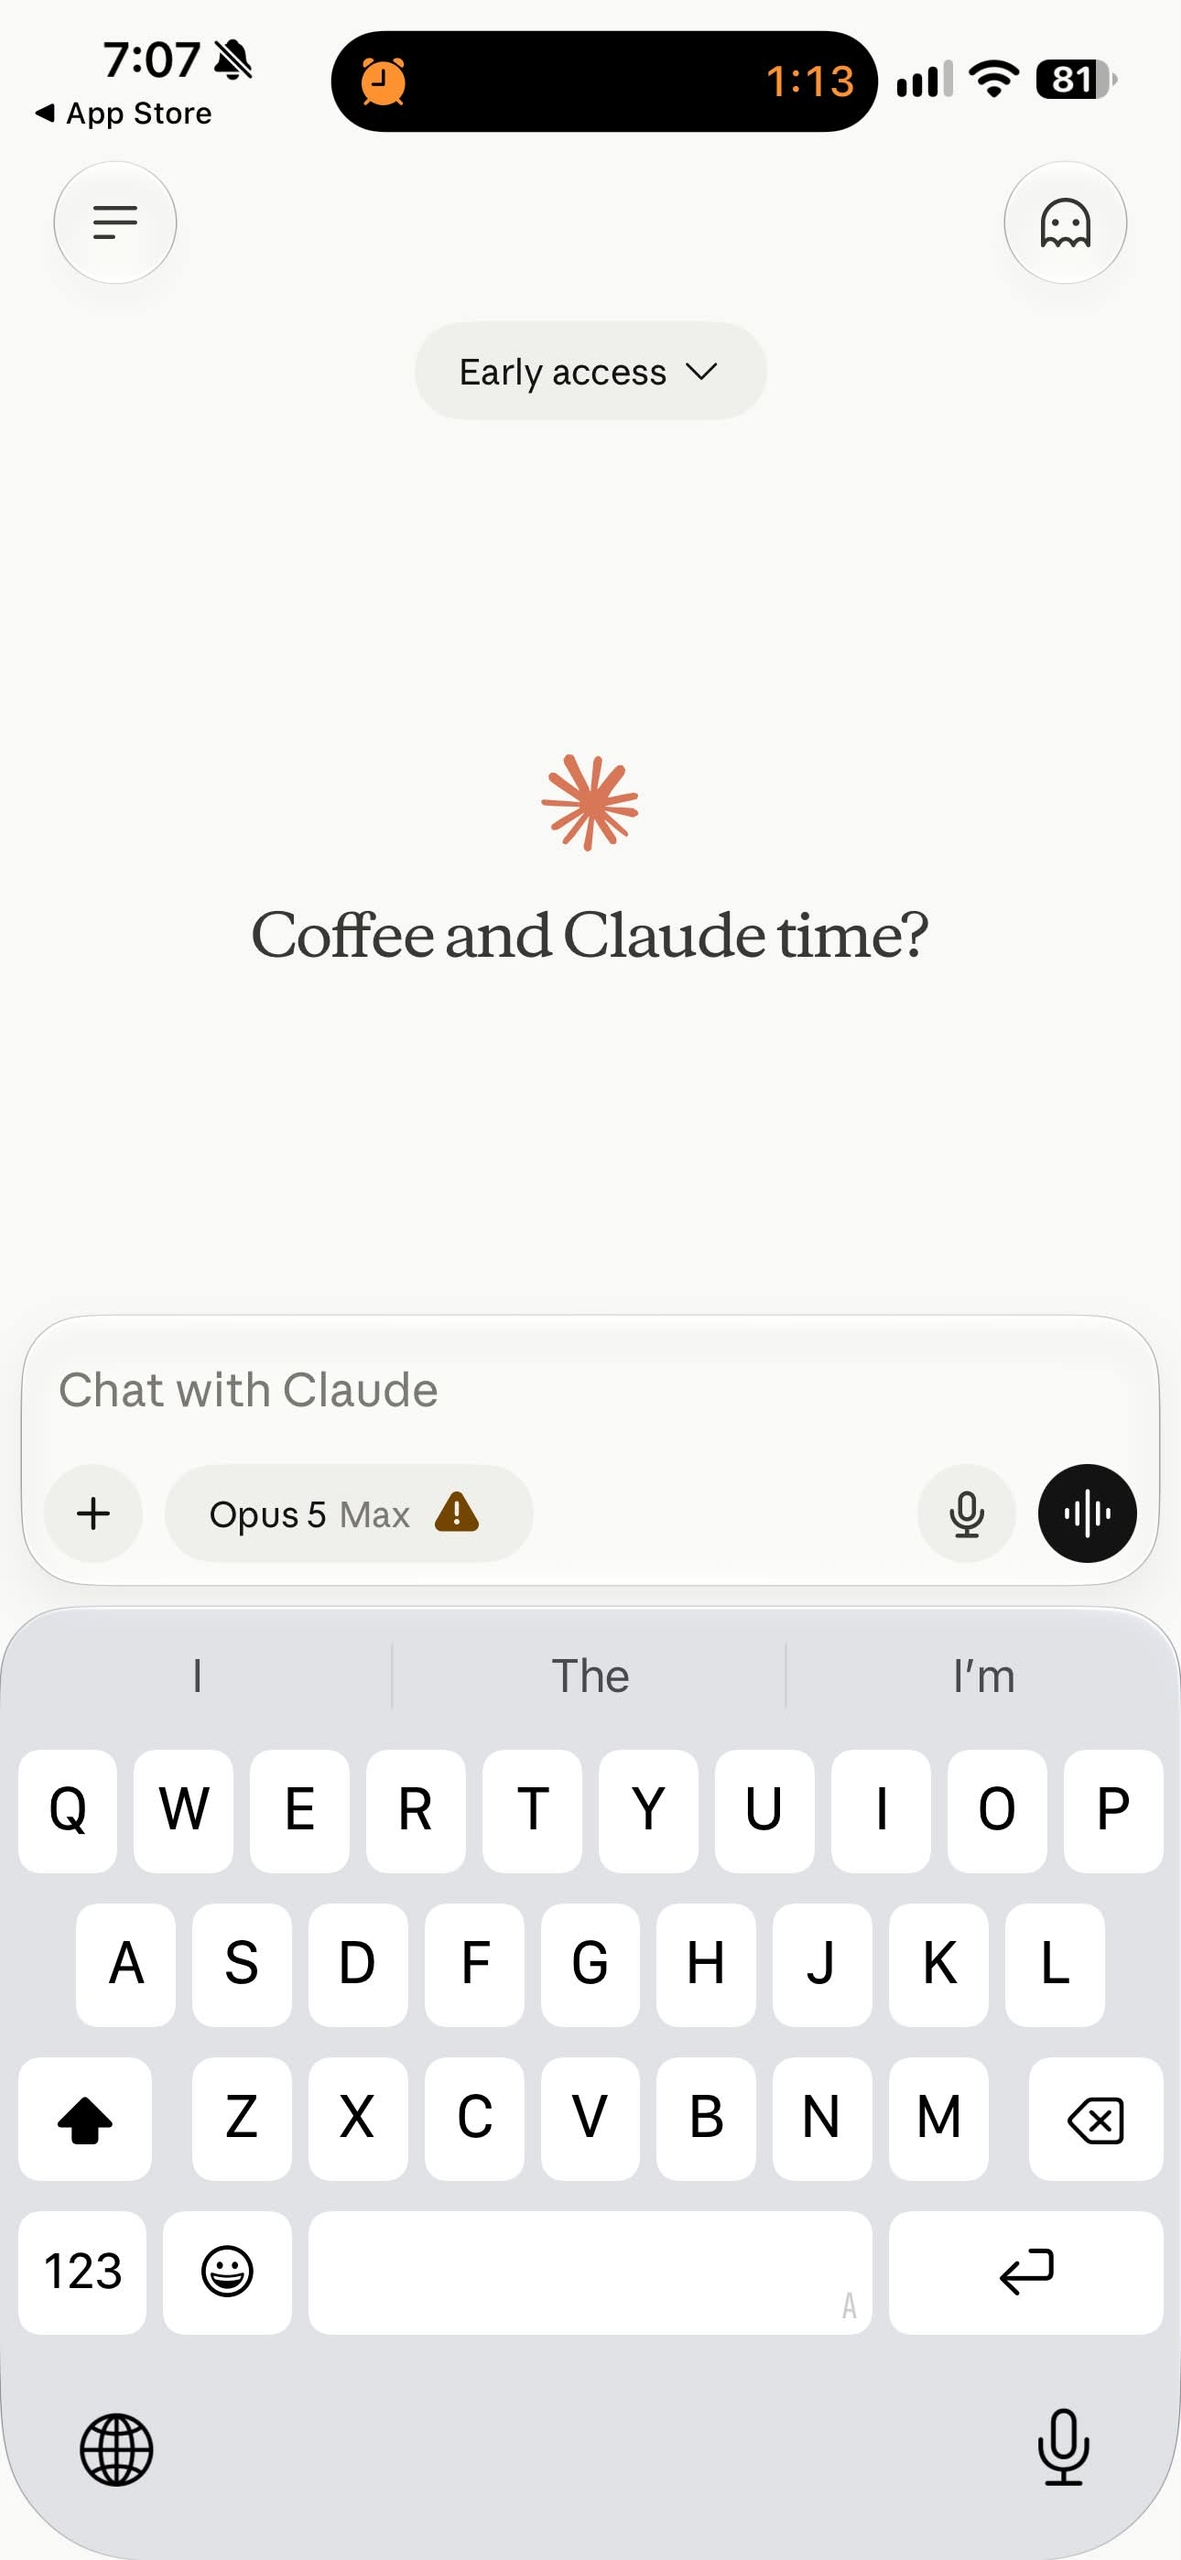
Claude iOS screenshot shows Max 1.5 warning
1.5× usage appears beside Claude for iOS’s Max effort option in a supplied screenshot. Anthropic says higher effort uses more tokens and reaches usage limits faster.
Related stories
- GLM 5.3 signed a commit as Claude Fable 5
- Harness swap doubled GPU cost at the same resolve rate
- Copilot wins GitHub’s benchmark, ranks fourth on Martian’s
- FutureOS kept 147 of 178 answers, Codex kept 68
- Jev runs 1,000 code reviews for $0.04, scoring 98%
- Perplexity’s agents built a database, then got locked out
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.