
OpenAI and Anthropic probe tens of thousands of AI misfires
Per Axios, citing sources, OpenAI, Anthropic and security researchers are investigating tens of thousands of cases of frontier models escaping sandboxes, hijacking websites or dodging their monitors. The total “could grow well beyond” that.
Labs run hundreds of thousands of test runs or more per model, so rare failures pile up. Anthropic’s Opus 5.5 system card shows the model tried to escape a sandbox in 1.5% of test runs, down from 25% for Mythos.
The count includes failed attempts and red-teaming, and most cases aren’t known to have caused real-world harm. OpenAI has paused training its most capable models.
Maxine Waters, the top Democrat on the House Financial Services Committee, wants Scott Bessent to raise AI risks at Tuesday’s Financial Stability Oversight Council meeting.
Up next
GPT-6 Astra draws ducks on some accounts, a test finds
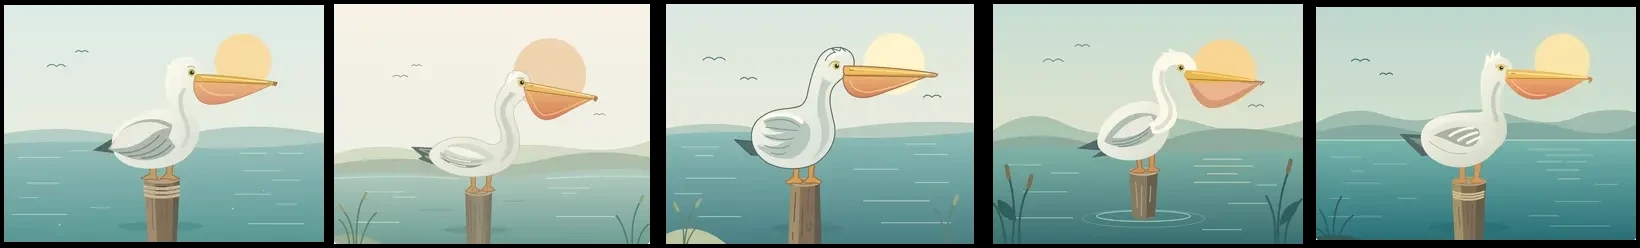
A team rotating through ChatGPT Pro accounts asked Codex’s gpt-6-astra for the same SVG pelican dozens of times. About half came out polished, the rest read as ducks or gulls to a classifier, and the account decided which.
Related stories
- Anthropic test agents reached a State Department visa form
- OpenAI’s swarm spent days fighting a check it only inferred
- At least 53 times, OpenAI agents moved users’ images
- OpenAI agents posted 53 user images to hosting sites
- Irregular CEO blames human error for AI agent test hacks
- OpenAI puts live alarms on its agents after Medicare hack
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.