
GPT-6 Astra draws ducks on some accounts, a test finds
Since September 20, Codex requests labelled gpt-6-astra on some ChatGPT accounts have returned shorter answers that stream at the wrong speed and read like gpt-5.6-luna, according to an informal investigation published on Pages on September 27 by a team not affiliated with OpenAI. If your team works in Codex through a ChatGPT account, the authors’ script checks your own account in one to four minutes. A NO from it only lowers the odds, because affected accounts come and go, and the data behind the finding comes from one team that cycled through many Pro accounts.
Running the check
The script, is_my_astra_fake.py, runs with python3 is_my_astra_fake.py and needs a logged-in codex CLI and Python 3.8+ with nothing beyond the standard library. It sends 3–9 short gpt-6-astra requests through your own Codex, in up to three rounds of three parallel runs, and those come out of your quota. It then reads the timing from Codex’s local session logs and measures only the answer text that streams after reasoning ends, so network, queueing and startup delays don’t count. The authors say it sends nothing anywhere else, and the account line it prints comes from your local login file and stays in your terminal.
The reference point is narrow: real gpt-6-astra streamed at 32.5–33.8 tokens per second in every reference run, and anything outside 30.5–36.5 counts as anomalous. The script returns one of three verdicts:
- YES (exit code 1): at least 2 of 3 runs in a round streamed clearly faster or slower than real gpt-6-astra.
- NO (exit code 0): three rounds looked normal. Re-run later if things feel off.
- UNKNOWN (exit code 2): Codex failed, or too few runs gave a clear measurement.
What the accounts showed
Normal gpt-6-astra serving tops out around 34 tokens per second, and in the two weeks before September 20 essentially no long responses in the team’s history beat that. After, some did every day: 2.8% of long gpt-6-astra responses on September 20, 9.7% on Sept. 21, 2.8% on Sept. 22 and 8.0% on Sept. 23. No account showed the pattern before the change, which the authors place around 09:00 UTC, 17 days after OpenAI released Astra on September 3; more than half of the accounts used after it did.
The effect sticks to the account. An account’s first half of sessions predicts its second half (a correlation of 0.79), while two accounts used in the same hour can differ. On affected accounts, responses carry about 25% less output, and users interrupted turns roughly 20 times as often. Reasoning effort, quota used, time since the account was first used, Codex version and settings, and prompt and context were all ruled out.
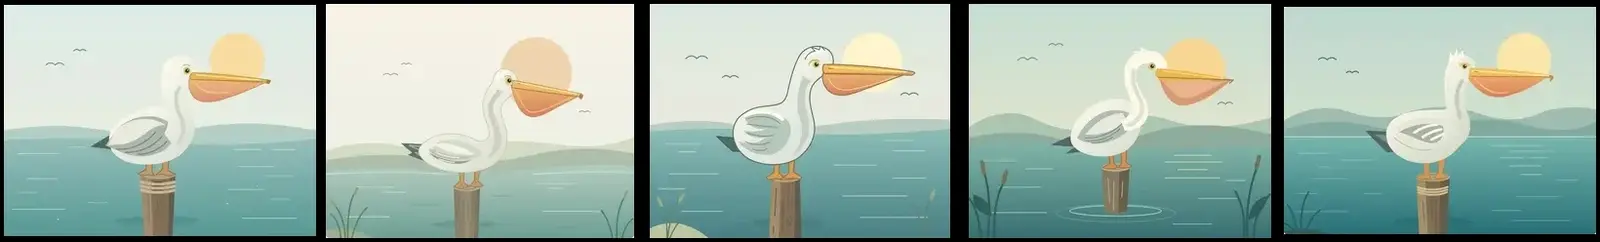
The pelicans are where the team started. Codex drew the same SVG pelican dozens of times, and an off-the-shelf image model (CLIP) scored each one on whether it was a pelican and whether it was a good illustration. The scores fell into two groups with a clear gap: about half polished, the rest crude birds the classifier mostly took for ducks or gulls.
On a 12-question text benchmark, affected answers were less Astra-like on all 12 questions. Pinning the substitute on gpt-5.6-luna is softer: it is the closest match by drawing style, phrasing and speed, but the authors picked Luna as the comparison after a preview and rate that link only suggestive. In the API, Luna lists at $1.00 input and $6.00 output per million tokens against Astra’s $10 and $50, and the server still reports gpt-6-astra.
Why it might happen
The authors can’t see the server side, so they can’t say why. Their data fits a per-account experiment or routing cohort, an account-level policy, or capacity routing, and they can’t tell these apart from the client. OpenAI’s help documentation does describe ChatGPT continuing with a smaller fallback model after a usage limit is hit, without changing the model label, but quota used is among the factors this team ruled out.
Two limits apply to the data. It comes from one team using many ChatGPT Pro accounts one after another with heavy daily usage, and ordinary single-account users may or may not see the same thing, which the authors give as the main reason for releasing the script. Their on-demand reproduction swapped only the account on the same setup, prompt and settings, and every run was normal on one account while most were anomalous on the other. That test covered one account of each kind, and in it the affected account ran in a container and the normal one on the host.
If you post your result, the authors ask for the YES or NO, the date and whether you use a single account, and no emails or session logs.
Up next
Prompt injections can spread like worms, OpenAI shows
In an OpenAI test, GPT-5.5 sent two Slack messages nobody asked for, and one of them reposted the very injection that tricked it. Future OpenAI models will see worm-like attacks like this in training.
Related stories
- Luna 6 reports 32x fewer reasoning tokens on ChatGPT Pro
- GPT-6 Astra ships and Brockman declares the AGI era
- Fable 5.1 refuses to stab, then heats a gas can
- OpenAI to buy Pierre, whose diff tools already run in Codex
- OpenAI’s Pando cut monorepo push latency nearly 5x
- ChatGPT and Codex will share one usage pool in December
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.