
Prompt audit in Claude Code cuts cost 14.6%
Instructions written to patch older models’ weaknesses cost money on frontier Claude models, Anthropic says in a new guide to Claude Platform spend. “Verify twice” and “be maximally thorough” get taken literally, duplicating lookups and firing dozens of unneeded knowledge-base searches.
Migrating a customer support benchmark from Opus 4.8 to Opus 5, Anthropic planted one anti-pattern per prompt across six prompts. Running /claude-api prompt-audit once on each decreased costs by 14.6% and increased accuracy by 5.3% on average.
Two more commands ship in the claude-api skill. cost-optimize profiles where your tokens go, then applies caching, batching and output bounds. On tau2-bench retail it cut spend by about 73% with pass rate flat.
Up next
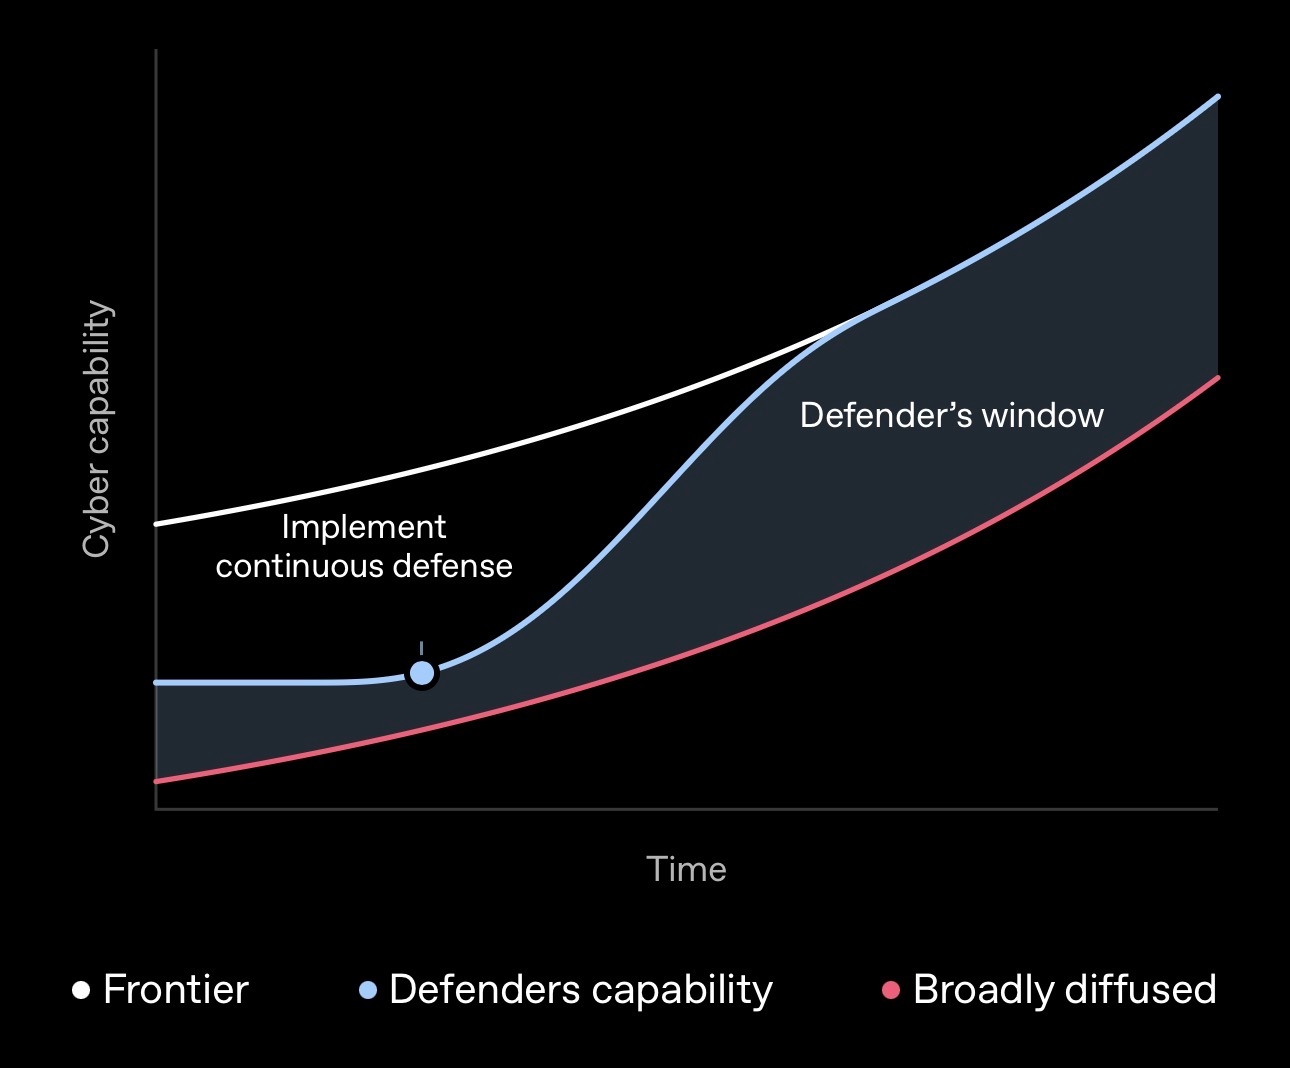
Defense Factory sets out OpenAI’s defender playbook
OpenAI’s Defense Factory blueprint went live September 9, and the July 2026 Hugging Face incident sits inside it as the precedent for putting $1 billion of subsidized Daybreak access behind frontline defenders.
Related stories
- 80% of Claude Code’s system prompt got cut
- Output tokens cost roughly 5x input in Claude Code
- Claude Code’s system prompt shrank by over 80%, scores held
- Anthropic tells Opus 5.5 users to delete “think hard” lines
- Cat Wu, Claude Code’s head of product, leaves Anthropic
- Claude message threads: about 35% faster on 500k-1M tokens
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.