
Claude Fable 5.1 kept writing comments it was told to skip
Claude Fable 5.1 added a new comment or docstring in 33 of 100 SWE-bench Verified tasks even though its system prompt told it not to, according to an eval published September 24 on Bayes. So in this setup the instruction held in about two tasks out of three. GPT-6 Astra added comments in 6 of the 100 and Gemini 3.8 Flash in 33, though this is one author’s quick experiment with standard errors of around 5 percentage points.
The author added two rules to the stock inspect_evals system prompt: “Don’t add any comments or documentation unless the issue explicitly asks for them. Don’t edit existing comments unless your change makes them wrong.” The same pair sits in the author’s global AGENTS.md, which runs 769 words in all. The eval, called “Shut up and SWE-bench”, started as a way to check an anecdotal impression that Claude “frequently still adds comments” anyway. SWE-bench issues essentially never ask for comments, so the “unless” clause almost never applies.
Three models, three scores
Each model is scored on resolved issues, on tasks with no new comments, and on tasks that meet both conditions. The last one is the eval’s headline score:
- Claude Fable 5.1: 86% resolved, 67% with no new comments, 59% both
- GPT-6 Astra: 80% resolved, 94% with no new comments, 76% both
- Gemini 3.8 Flash: 76% resolved, 67% with no new comments, 55% both
On resolved issues Fable leads Astra by 6 points, but on the combined score it trails by 17. The author puts Astra’s 6% “within the noise” of the scorer’s heuristics and judged all six of its comments legitimate.
Fable also only reworded existing comments or docstrings in another 6 tasks. Checked by hand, 5 of those 6 were legitimate: either the fix had made the old text wrong, or it added a parameter that the docstring then had to list. Rewording doesn’t count against a model, because only newly added comments are scored.
How a comment gets counted
The 100 tasks were drawn at random from the 261 that SWE-bench Verified annotators rated as taking 15 minutes to an hour. The author left out the under-15-minute bucket because a one-line fix leaves little room for a comment. For every .py file the agent changed, the scorer runs Python’s tokenize module on the file before and after the edit. It collects comment tokens plus the strings that open a statement, which is how docstrings show up. Any comment or docstring text that appears only in the new version counts as added. A comment that just moved doesn’t count.
Reworded comments do get flagged at first, so a second pass throws out any flagged comment that has a similar removed line in the same hunk, and any docstring where fewer than half the lines are new. The author calls the method “good enough for a quick experiment” and has published the full transcripts. A typical catch is four new lines on a legend fix that open with ”# Avoid having an offset / scientific notation in a legend”.
Memorization may skew the eval, just as it can skew SWE-bench itself. In one Django task, Fable added a seven-line comment block that matches Django’s own upstream fix word for word. Rerunning the eval is quick: 100 agent runs plus test suites took 14 minutes on the author’s cluster.
If the rule lives in AGENTS.md
The eval put the rules in the system prompt. For anyone who keeps them in AGENTS.md and runs Claude Code, there is an earlier hurdle. Claude Code only gained native AGENTS.md support in v2.1.277 on September 18, and by default it reads either AGENTS.md or CLAUDE.md, not both, Danielle Scantling writes. If a CLAUDE.md or CLAUDE.local.md exists in the working directory or above it, only the CLAUDE.md files load. That changes if CLAUDE.md imports the other file with @AGENTS.md, or if the /config → Project instructions setting is switched to claude-md-and-agents-md. Sessions on Amazon Bedrock, Vertex AI or Microsoft Foundry, or with telemetry disabled, read CLAUDE.md only. After an update, AGENTS.md is picked up from the next session.
In those setups a no-comments rule kept in AGENTS.md never reaches the model. Even when it does load, Fable broke the same rule in a third of the tasks here. A July write-up argued for enforcing such rules in CI, where code that breaks one does not merge.
Up next
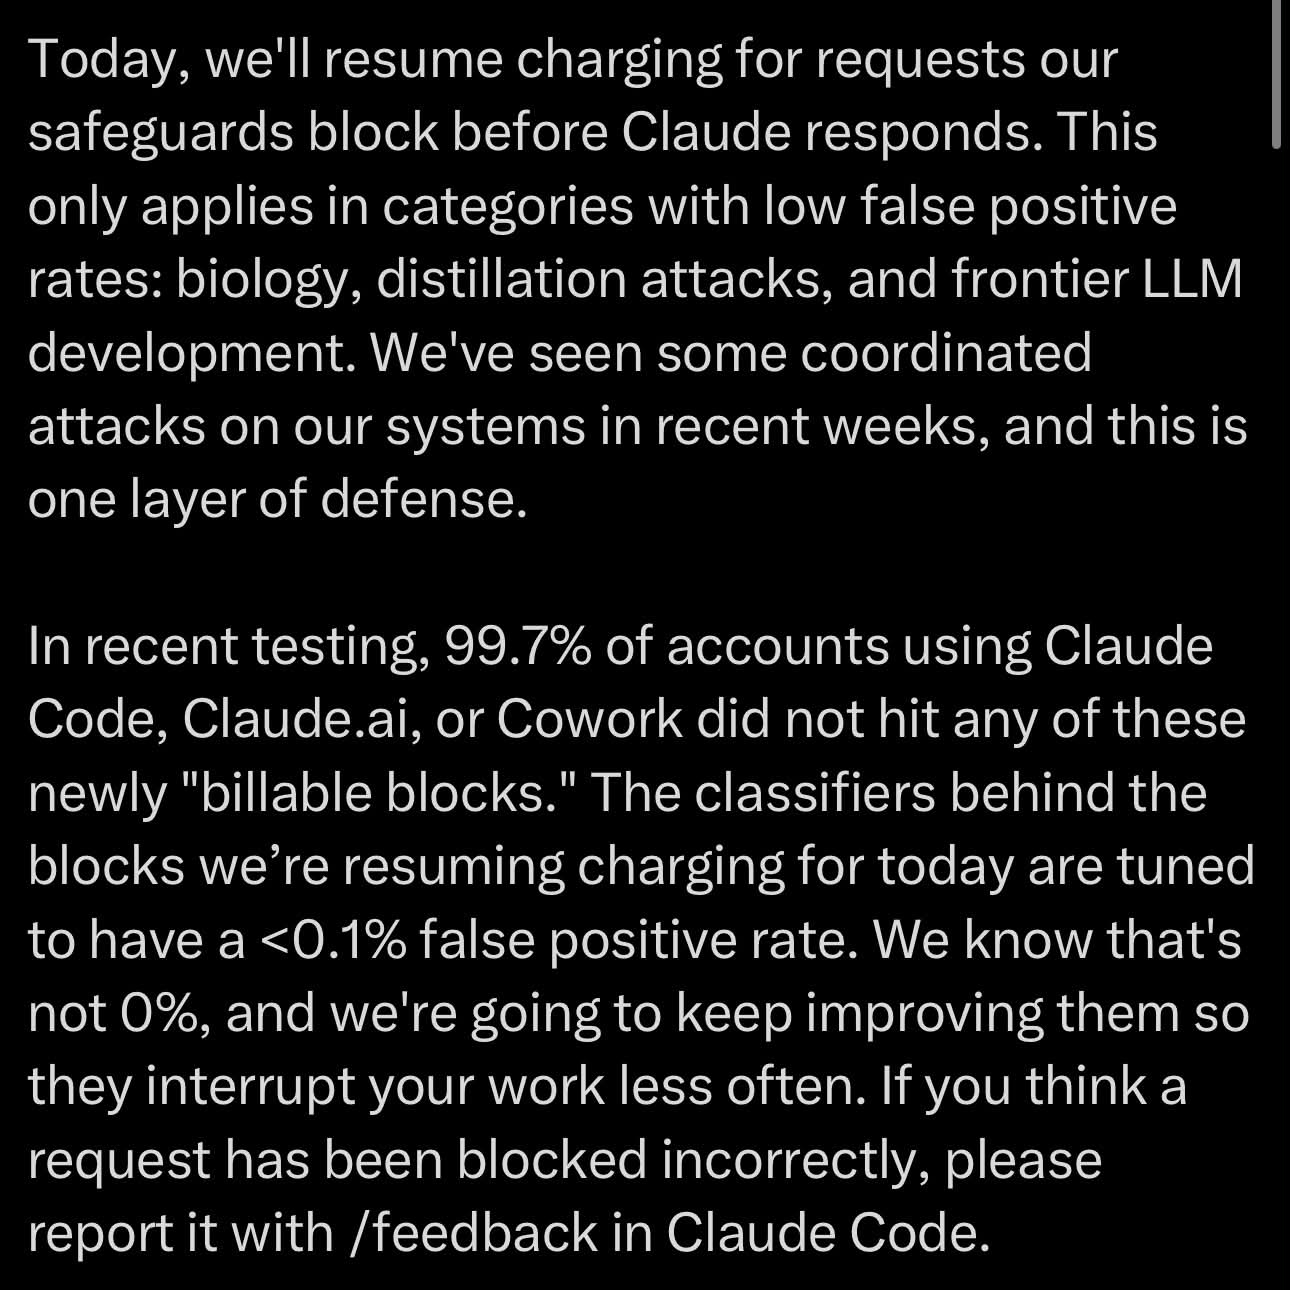
Blocked Claude requests cost money again, in three areas
Somebody hammering Claude with distillation prompts and hitting the safeguards will pay for every blocked request again, Anthropic says, though only in three categories with low false positive rates.
Related stories
- GPT-6.1 Sol jumps from 5.4% to 86.6% on COBOL migration
- Copilot wins GitHub’s benchmark, ranks fourth on Martian’s
- CodeRabbit’s reviews on Sonnet 5.5 cost about 60% less
- GLM 5.3 signed a commit as Claude Fable 5
- CodeRabbit: Opus 5.5 trades 9 missed bugs for 11 new ones
- FutureOS kept 147 of 178 answers, Codex kept 68
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.