
Claude telemetry: 4% of sessions ran up 65% of the bill
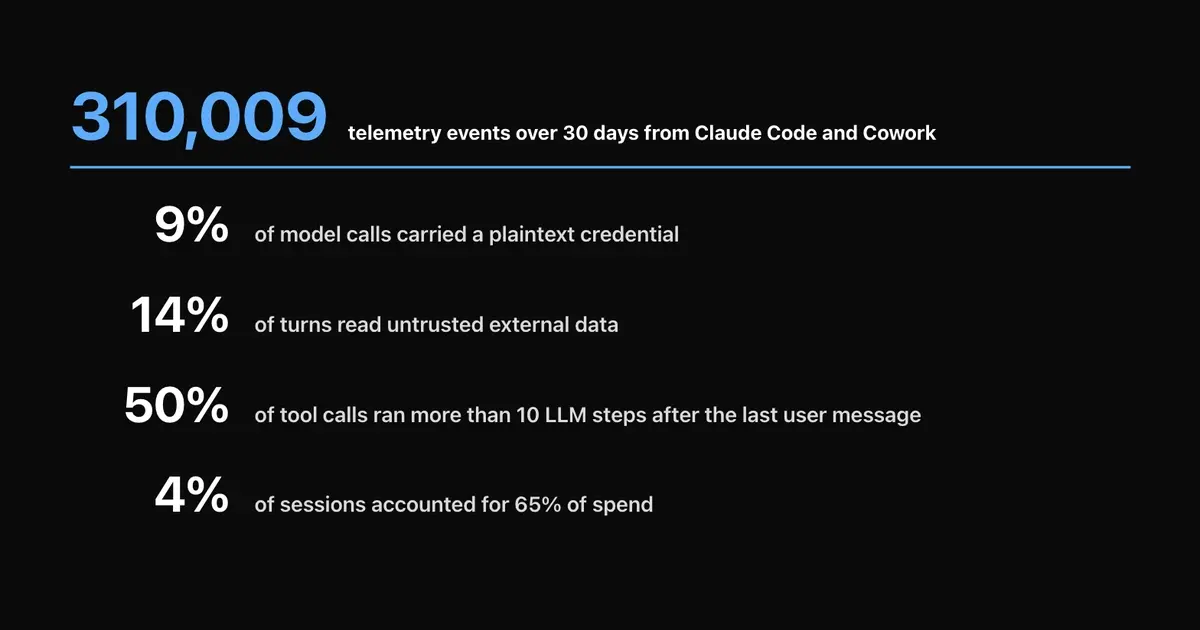
Two sessions ran up 32% of a ten-person team’s spend. The team kept both open and resumed them every day for over a week. The figure comes from 310,009 OpenTelemetry events logged over 30 days in Claude Code and Cowork.
Most of the money paid for memory. Cache reads made up about 68% of spend. That’s the agent re-reading its own conversation, and in those two sessions every call paid for ~500k tokens of cached context.
On security, Claude printed credentials outright 66 times. Each value stayed in context until compaction, so 9% of model calls sent a credential to Anthropic in plaintext. And 14% of turns read untrusted external data, with MCP servers as the biggest source.
The data covers one anonymized enterprise team, and the write-up doesn’t say what those two sessions were working on.
Up next
Claude Fable 5.1 kept writing comments it was told to skip
Told not to add comments, Claude Fable 5.1 still wrote new ones in 33 of 100 SWE-bench Verified tasks. GPT-6 Astra did it in 6%, though it resolved fewer issues.
Related stories
- Claude Code hashes files for Anthropic even on DeepSeek
- MCP OAuth tokens sit in plaintext on Linux
- Claude Code approvals put keys in 1,122 public GitHub files
- Claude Code put users’ emails in User-Agent headers
- METR estimates Anthropic now progresses about 2x faster
- Elastic finds Claude Code and ChatGPT abused in intrusions
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.