
Doc retrieval tool claims 99% fewer input tokens
Context7 ran its own benchmark against Claude Code’s built-in WebSearch and WebFetch, arguing that feeding an agent documentation slices instead of whole pages cuts what it has to read. Across every category tested, fresh input tokens dropped by roughly 99%.
The runs used the Claude Code Agent SDK on Anthropic’s defaults, Claude Opus 4.7 as the main agent and Claude Haiku 4.5 for auxiliary tasks, over five query categories, from niche libraries to questions that name no library at all.
Average cost fell 34.56%, a smaller gap than the token counts because Claude Code’s web search leans on prompt caching and routes auxiliary calls to the cheaper Haiku. Popular libraries showed the least benefit, at 27.89% off cost. The full query set and per-query results sit in Context7’s benchmark repo.
Up next
Hybrid mode would split Computer between Mac and cloud, Video
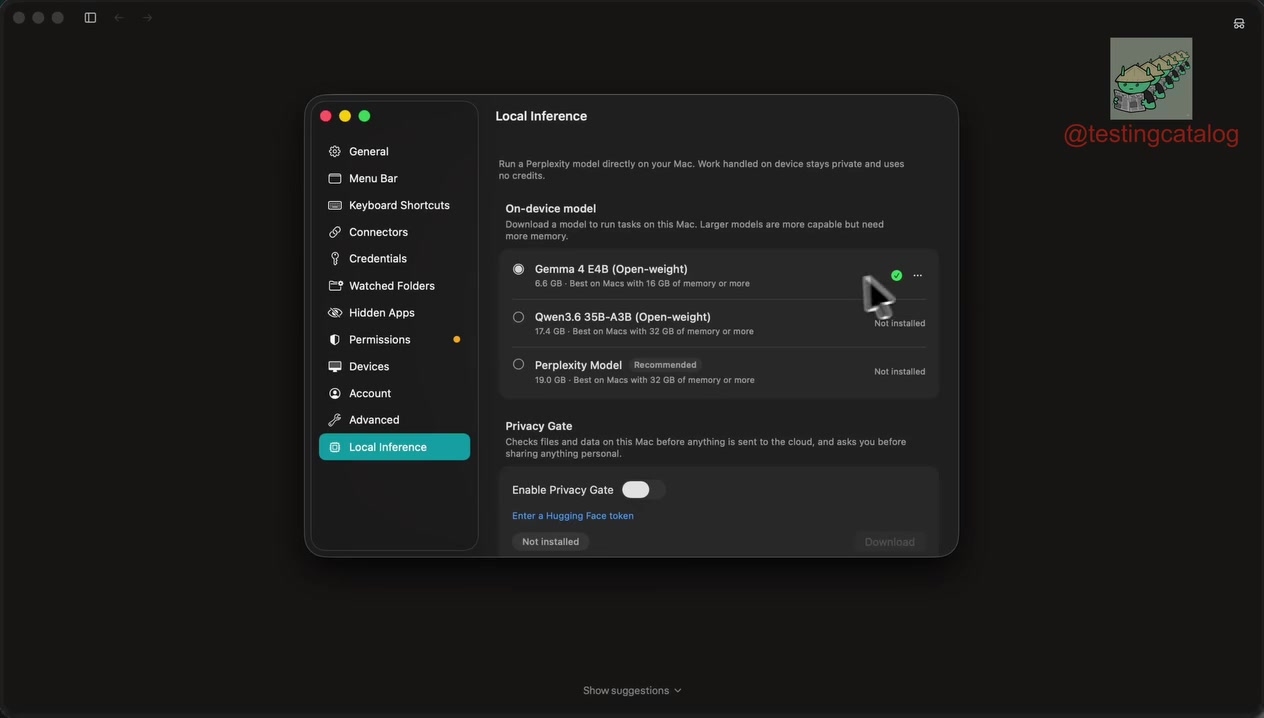
Per TestingCatalog, Perplexity’s Computer agent would keep orchestrating in the cloud while handing subtasks to a model on your Mac, with Gemma 4 for 16 GB machines and Qwen3.6 or Perplexity’s own for 32 GB.
Related stories
- LSP plugin made Claude Code 11% pricier on C++ fixes
- FutureOS kept 147 of 178 answers, Codex kept 68
- SubQ Snap reads 384K tokens before each agent decision
- Harness swap doubled GPU cost at the same resolve rate
- Three computer-use benchmarks fall to GPT-6 Astra
- Claude Code hides a /hub path for sub-agent boards
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.