
Context7 cuts Claude Code input tokens by roughly 99%
Upstash, the company behind Context7, ran 100 documentation questions through Claude Code twice, once with the built-in WebSearch and WebFetch tools and once with Context7. Fresh input tokens dropped by about 99% in every category, and the bill dropped by 34.56% on average. The difference between those two figures comes from how Claude Code bills tokens, and Upstash’s August 31 benchmark post on the Upstash blog publishes enough of the breakdown to show where it goes.
Upstash builds and sells Context7, so this is a vendor’s test of its own tool against the default. It covers tokens, tool calls and dollars. It does not measure answer quality. Upstash says that benchmark, along with one on safety, is still in preparation.
What was measured
Each of five categories held 20 queries, and each category was built to stress retrieval in a different way. “Evolving” libraries change often, so the question is whether a tool can find the current API, for example “How do I use extended thinking with opus 4.7?” “Niche” libraries have little web presence, and many of those queries were about recent YC companies. One sample: “Where can I configure function schedules in Notte?” A third set needed two documentation sources at once, such as comparing how Playwright and Testing Library locate elements by accessible role. “Popular” queries asked about heavily documented tools with a lot of tutorial and blog noise around them, for example how Claude Code memory files work. The last set named no library at all and left the agent to work out from function names alone which project relations(), one() and many() belong to.
The runs used the Claude Code Agent SDK with Anthropic’s defaults: Claude Opus 4.7 as the main agent and Claude Haiku 4.5 for auxiliary tasks. On the web side, every query ended with “Use web search. Use web fetch when needed.” On the Context7 side it ended with “Use Context7.” All questions in a category ran back to back, with a 5-minute pause between the Context7 and web search runs to reduce prompt caching effects. Cost figures were taken from the Claude console as reported at the time of each run. The queries and the per-query results are in Upstash’s benchmark repo.
How Context7 fetches docs
Web search gives the agent a search engine and a page fetcher. Context7 gives it an index of library documentation that is already split into snippets. The project’s GitHub README describes a two-step flow. First, resolve-library-id turns a plain library name into a Context7 ID such as /vercel/next.js or /mongodb/docs. Then query-docs returns the documentation and code examples that match the question. If the prompt already contains the ID, the agent skips the first step. If the prompt names a version, say Next.js 16, Context7 matches docs for that version.
The same README describes two ways to connect it. One is an MCP server, local through npx @upstash/context7-mcp or remote at https://mcp.context7.com/mcp, added with claude mcp add. The other is a skill that has the agent call the ctx7 CLI, with ctx7 library and ctx7 docs as the equivalents of the two MCP tools. A rule in CLAUDE.md can make Claude Code reach for Context7 on library questions without being asked. An API key from the Context7 dashboard raises rate limits but is optional.
The two approaches differ in what lands in the context window. Upstash’s explanation for the gap is that WebSearch and WebFetch “likely return larger page-level artifacts” that go straight into the agent’s context, while Context7 returns a condensed documentation slice. The company frames this as likely. Its tables count tokens and do not inspect what the tools returned.
Where the 99% goes
The 99% applies to one column. Upstash counts as “input tokens” only new, uncached tokens: the user’s query, tool call results and tool definitions. In that column the averages fell from 38,403 tokens per query with web search to 387 with Context7. By category, the reduction ran from 98.70% for popular libraries to 99.12% for niche ones.
Output tokens, which cover the final answer, reasoning and tool call invocations, fell by 52.97% on average, from 3,290 to 1,544. Upstash attributes this to the model having less irrelevant material to filter and reconcile. Per category, the output reduction ranged from 49.80% on multiple-library queries to 61.95% on niche ones.
Most of each run’s volume sits in the cache columns, and those barely changed. Cache reads averaged 84,183 tokens with web search and 71,436 with Context7. Cache writes were essentially the same, 10,686 against 10,912, and Context7 came out slightly higher. Total tokens therefore fell by 36.81%, from 136,562 to 84,278 per query. Cache reads make up about 85% of what is left on the Context7 side.
Cache reads are billed far below fresh input, so the cost line follows the total more closely than the input column. The average query cost $0.22 with web search and $0.14 with Context7. Upstash names two mitigations that narrow the gap: aggressive prompt caching keeps repeated context cheap, and auxiliary tool calls on the web search path run on Haiku 4.5 rather than Opus. In the company’s words, these mechanisms are “why a 99% reduction in input tokens does not translate to a proportional reduction in cost.”
Claude Code add-ons that promise to save tokens have been measured against the bill before. In July, a JetBrains A/B test of rtk, which was pitched at 60-90% token savings, found it 7.6% more expensive per task at the median at low reasoning effort. In Upstash’s run the direction holds in all five categories: Context7 cost less every time, by between 27.89% and 43.12%.
Niche libraries, popular libraries
Niche libraries showed the largest savings: 43.12% off cost, 50.19% off total tokens and 55.88% fewer tool calls. Web search averaged 5.10 tool calls per niche query against 2.25 for Context7, the highest web search figure in the tables. Upstash says web search “had to work harder to locate the correct source in a lower-signal web environment.” The average niche query cost $0.25 on the web path and $0.14 with Context7.
Queries with no named library came second, with costs down 36.94% and 29.31% fewer tool calls. Upstash reports that web search usually identified the same library in the end but needed more exploratory calls to get there. Multiple-library queries came third at 35.60% off cost. Here Context7’s tool count rose to 3.65 per query against 4.00 for web search, a cut of only 8.75%, yet total tokens still fell by 41.51% because each retrieval returned a compact slice.
The evolving-library category saved 29.24% on cost and 27.12% on total tokens. Upstash credits documentation organized by version and source, which matters most when an API changes between releases.
Popular libraries showed the smallest gap: 27.89% off cost, 21.70% off total tokens, and tool calls almost level at 2.45 for web search and 2.30 for Context7. Upstash had expected that result: “This is expected because popular libraries are easier for web search tools to find.”
Up next
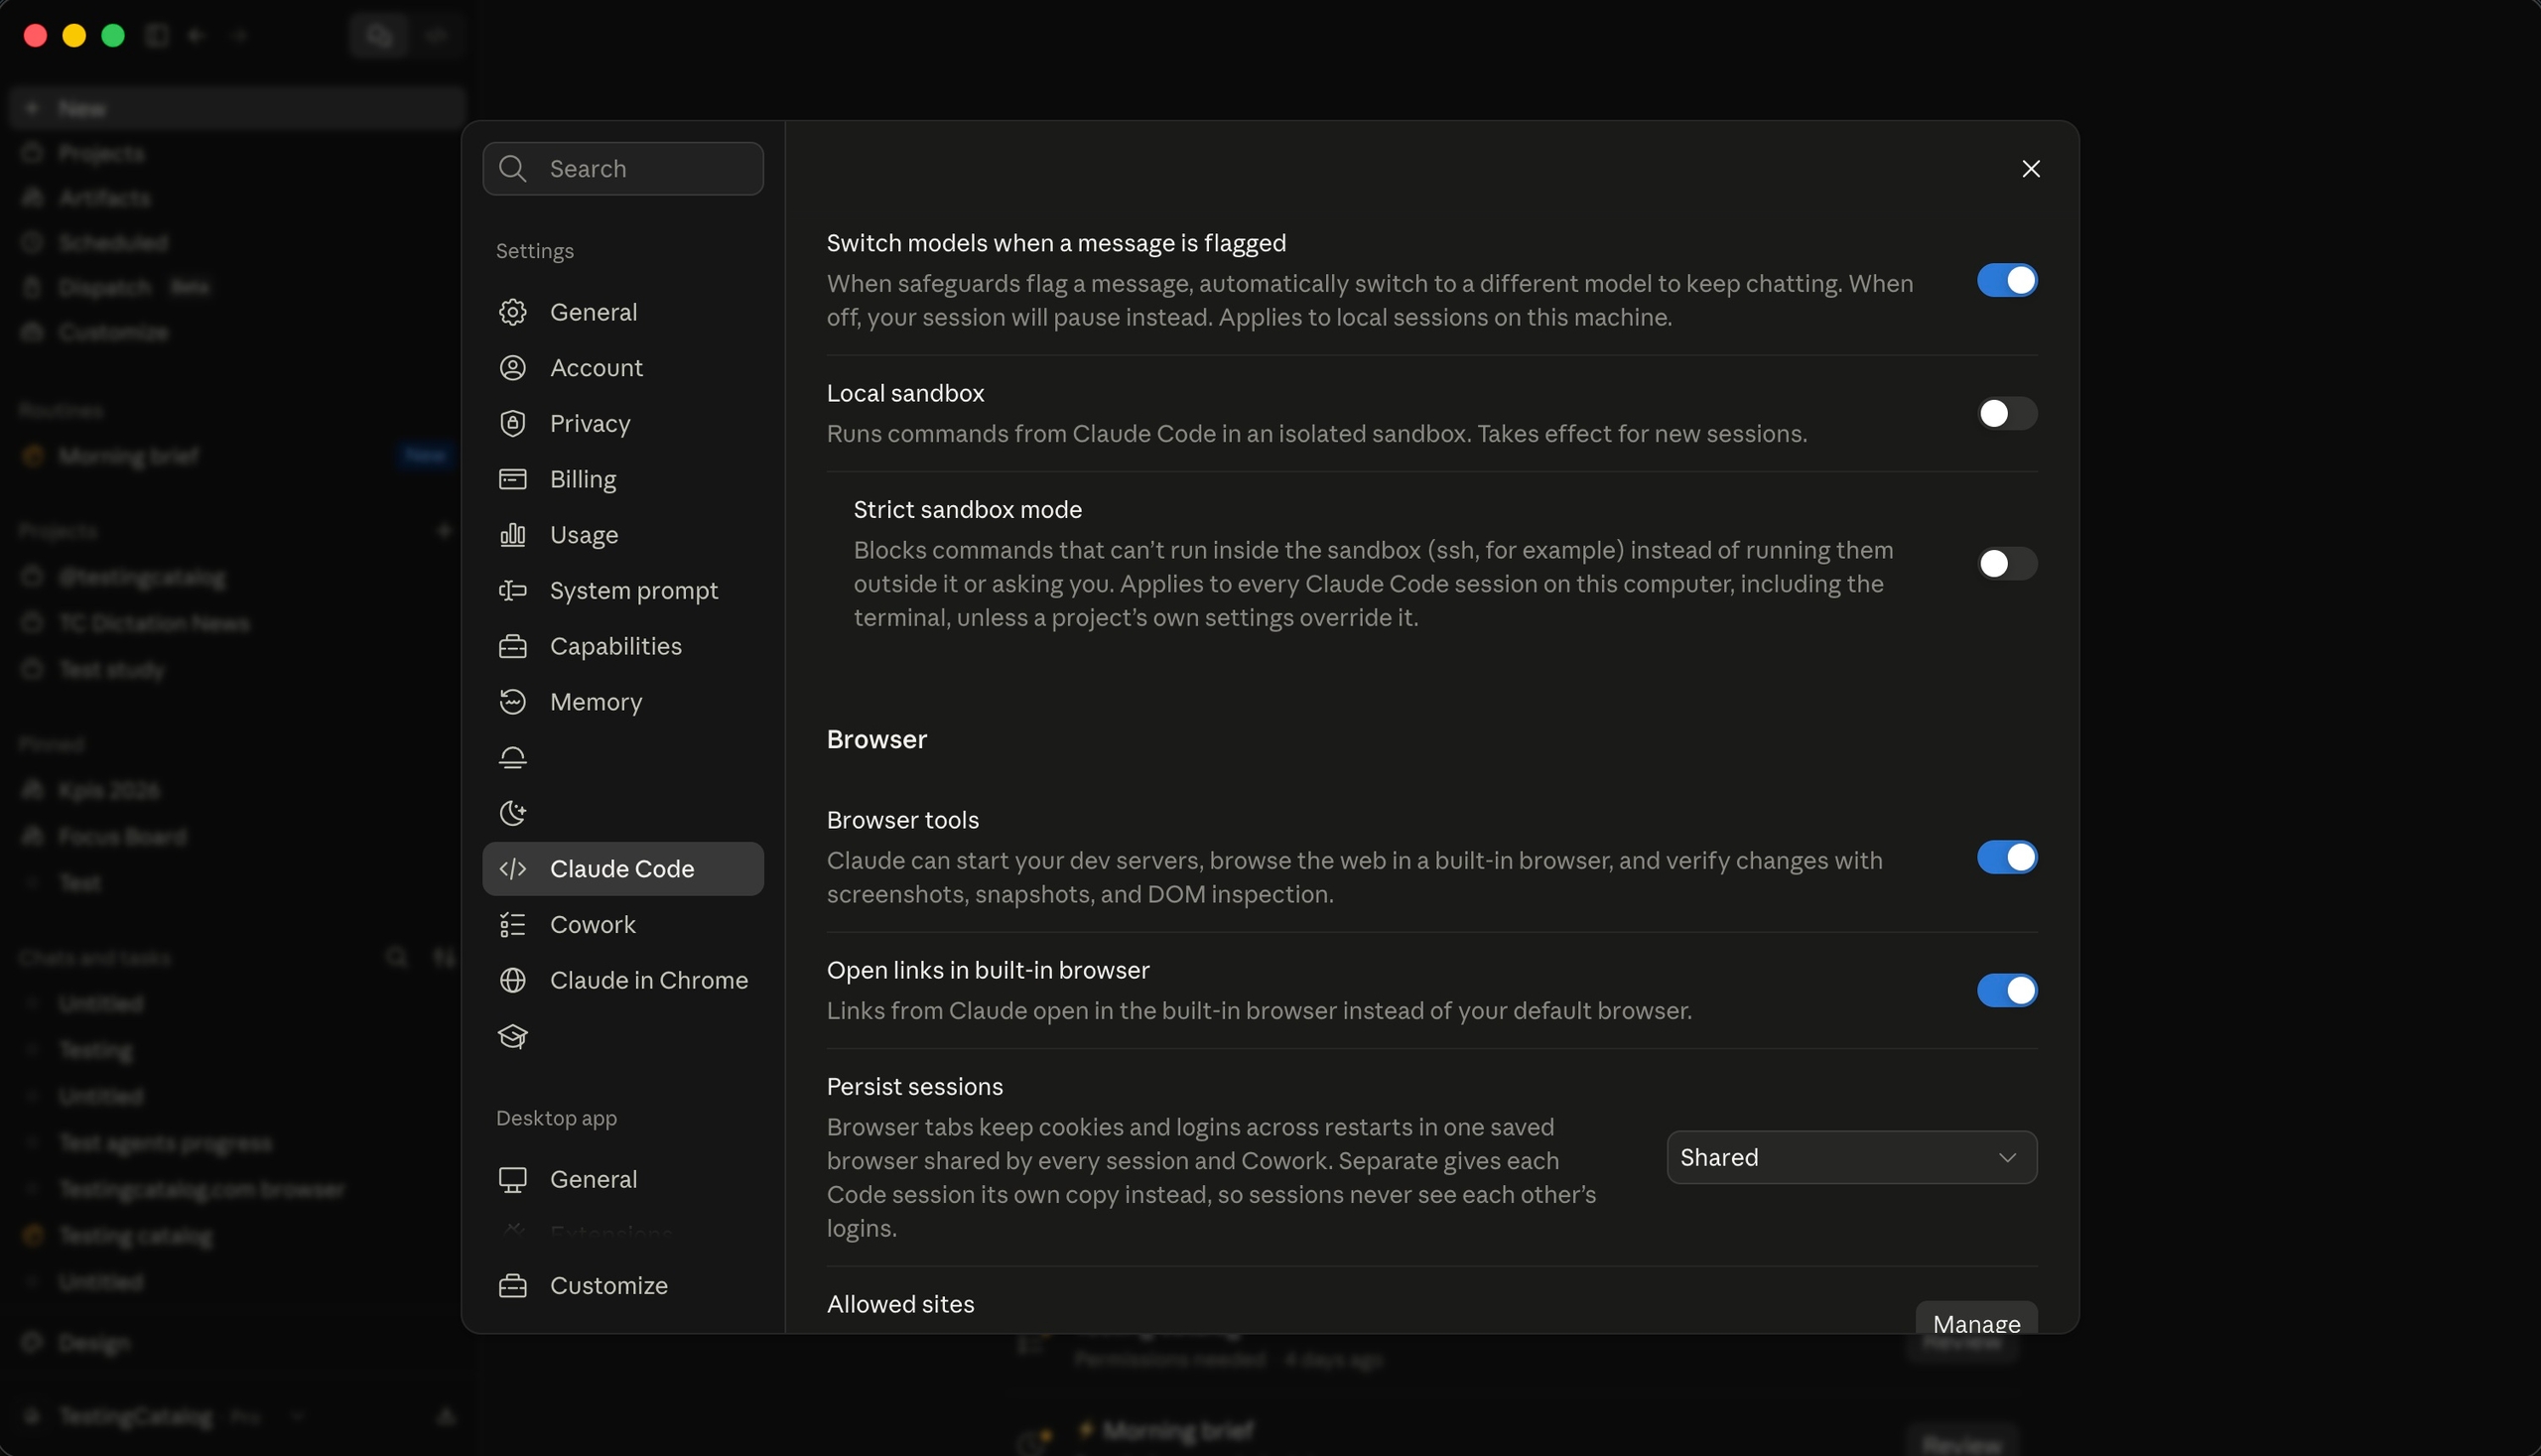
A strict sandbox mode surfaces in Claude Code desktop
Ask Claude Code for a shell command and it may soon run inside an isolated local sandbox, per unannounced text in the desktop app. A strict mode blocks whatever can’t run in there, ssh included.
Related stories
- Claude stamps 2026 onto “best X” search queries
- rtk promised 60-90% fewer tokens. JetBrains measured 7.6% more spend
- Claude Code 2.1.318: login expiry warning, runner log change
- Intent-lens spells out Claude Code calls before they run
- Codedict cuts Claude Code tokens 63%, but cost only 26%
- claude-files-pane shows Claude Code’s file reads live
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.