
Meta’s Muse Spark 1.3 lands on Google Cloud with 1M context
Meta’s Muse Spark 1.3 is in public preview on Google Cloud alongside Muse Wonder and Muse Ember. Google Cloud’s model page, updated November 9, gives it a 1,048,576-token input limit. It also lists batch predictions and Provisioned Throughput as not supported, so Spark 1.3 runs only on standard pay-as-you-go or a fixed quota, and only through the global endpoint.
The page gives two forms of the model ID. The catalog lists it as meta/muse-spark-1.3, but requests to the global Responses endpoint, /locations/global/publishers/meta/v1/responses, pass the bare muse-spark-1.3 in the model field.
Google Cloud describes Spark 1.3 as a reasoning model trained for agentic workflows and competitive coding. It has built-in tool calling with support for MCP, the Model Context Protocol that lets a model reach external tools and data through one interface. It takes text, images and PDFs and returns text. The full million-token window is aimed at multi-step tasks, and the quota for the global endpoint allows the same context length.
The long window is not new for the Muse line, which Meta Superintelligence Labs has built since April as the successor to Llama. Meta’s own Model API opened in public preview with Muse Spark 1.1 on July 9, already with a million-token context, and widened to developers worldwide on August 5 with Spark 1.2.
The page dates this version September 24. Function calling, structured output and reasoning each still carry a Preview tag there.
Up next
Claude Fable 5.2 moves to usage credits after November 16
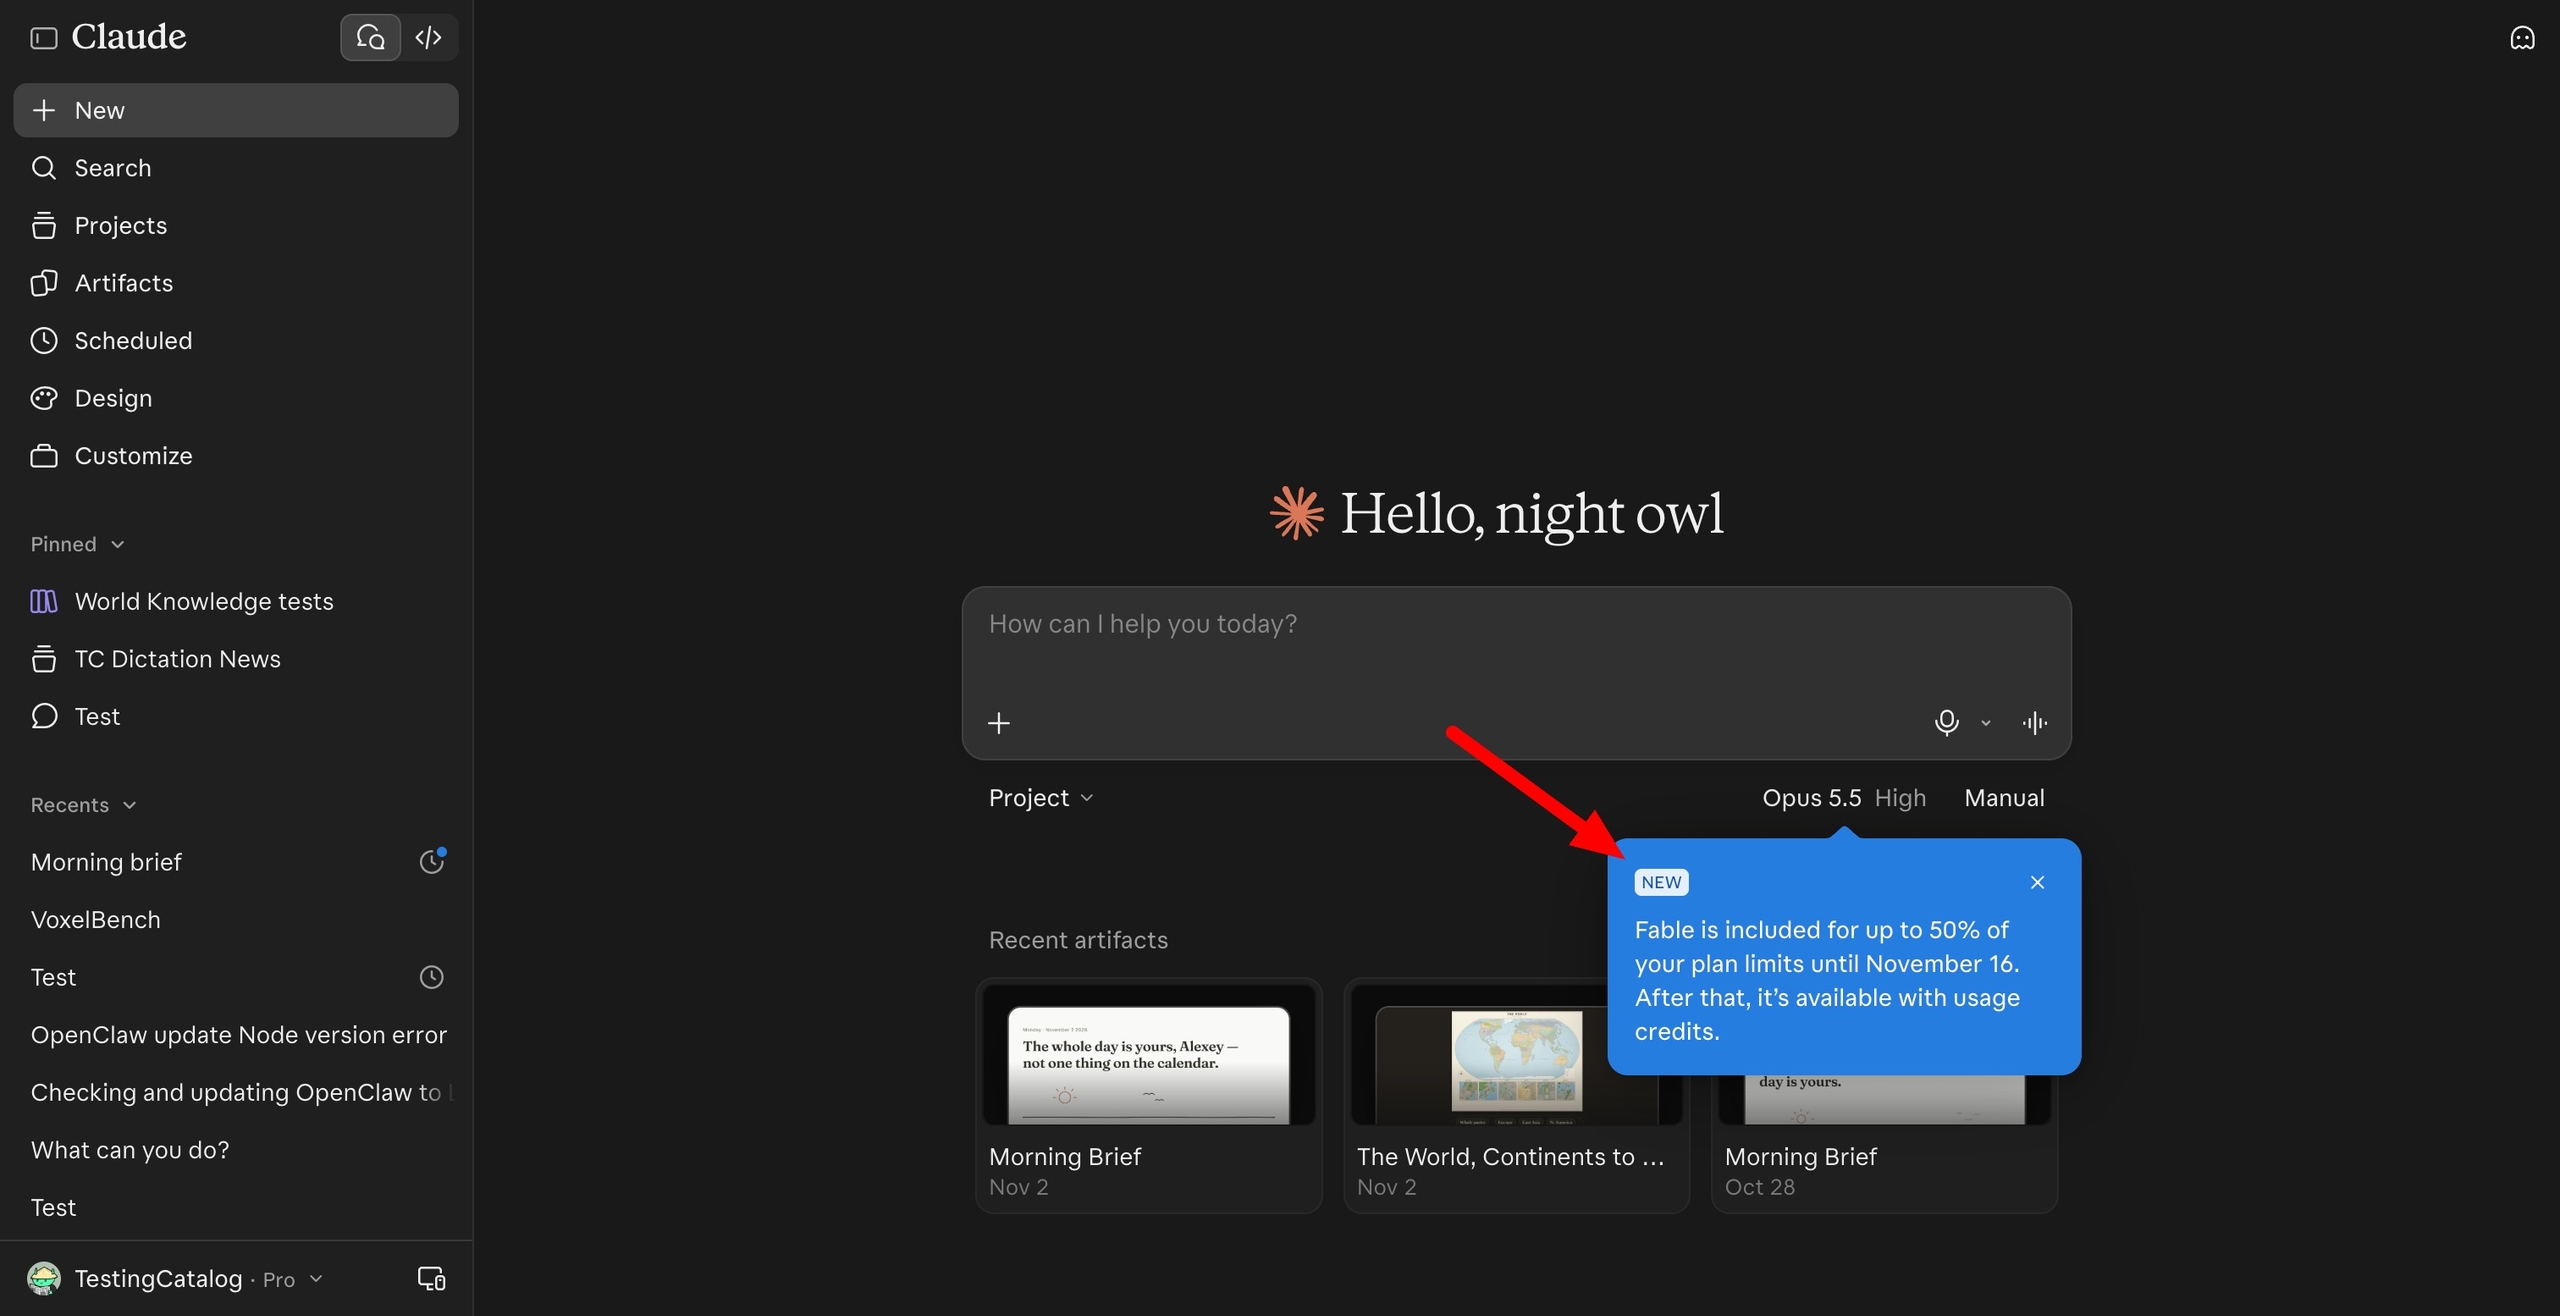
Pro subscribers testing Claude Fable 5.2 this week can spend up to 50% of their plan limits on it until November 16. After that, the model runs on usage credits. Is Fable 5.2 your default model this week, or just a side test?
Related stories
- Meta’s Muse Ember matches Haiku at about a third the cost
- Meta’s Muse models now hit 90% on its own memory eval
- Google Cloud gets OpenAI’s GPT-6 models in private preview
- Gemini Decisions API scores 1,000 questions in one call
- Gemini Robotics 2.5 kits car parts at 96% in Mercedes pilot
- Gemini 4 Carbon reaches Agent Studio with 1M output tokens
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.