
Opus 5.5 hands flagged security chats to Opus 4.8
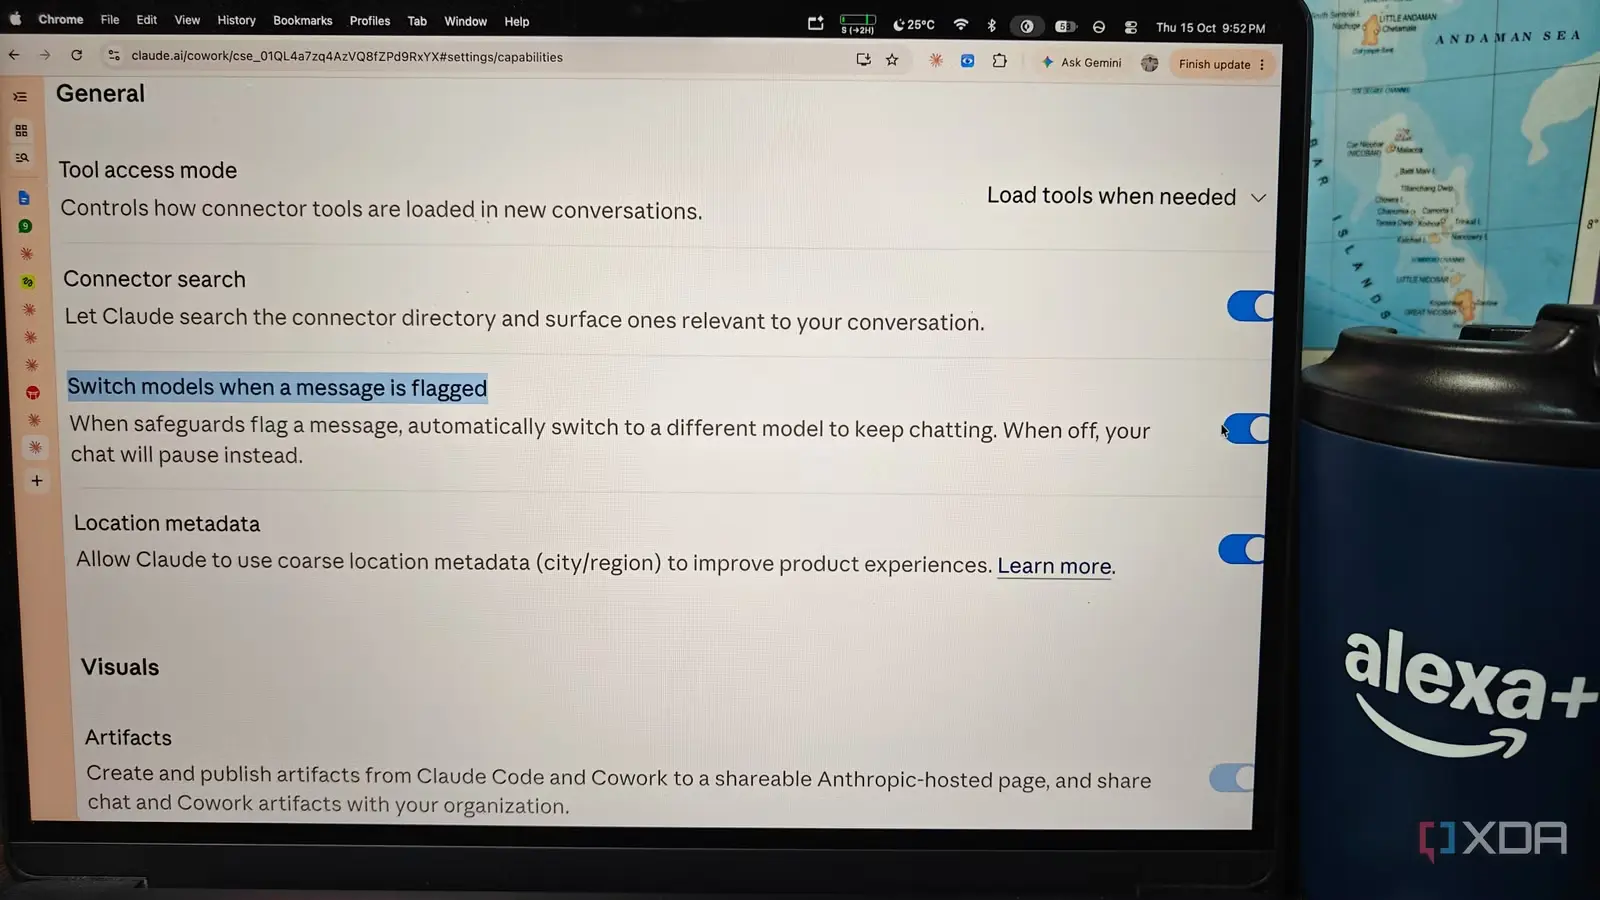
Once Anthropic’s classifiers flag a request as offensive cyber work, Claude Opus 5.5 is blocked. Opus 4.8 answers instead, in claude.ai and Claude Code, for the rest of the chat. The classifiers also read files, connectors and search results, so a hostile line in a repo can trip the switch.
The catch sits in Anthropic’s system cards. In a coding prompt-injection test for Sonnet 5.5, which falls back to Sonnet 5 the same way, 25% of requests were rerouted and 12.01% of those were compromised. Sonnet 5.5 answering itself was compromised in 4 of 5,901.
On the API, fallback is opt-in, and the model name in the response is the tell. In the app and Claude Code, turning off the “Switch models when a message is flagged” toggle makes a flagged request pause instead.
Up next
Anthropic seeks en banc rehearing over Pentagon risk label
Judges saw “no reason to doubt” Anthropic’s “noble intentions” and still upheld its “supply chain risk” label. Anthropic wants the full D.C. Circuit to rehear the case.
Related stories
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.