
Oxford’s Bodleian Library texts ended up training OpenAI
Oxford has let OpenAI train its models on historical texts from the Bodleian Library: internal documents say the Bodleian material OpenAI digitized was used to “populate the OpenAI training set,” The Guardian reported on September 26. By the university’s account, OpenAI does not get the material to itself: its use is not exclusive, and the Bodleian, which keeps the rights to the scans, will start publishing them openly online in the next few months.
When Oxford announced the partnership in March 2025, it presented OpenAI software digitizing texts from the library as a way to make them more widely available to students and researchers, and did not mention training OpenAI’s models. The university now rejects the suggestion that the machine-learning element was hidden from the public and students: digitization was its primary interest, a spokesperson said, but staff had been open that the project would also contribute training data. An OpenAI spokesperson said the company was “proud” to ensure “the AI models of today preserve the world’s historical knowledge for the future.”
What went to OpenAI
Oxford’s spokesperson called the amount of text being digitized “modest in scale” and said it covers only out-of-copyright material. By June 2025, 125,000 images scanned from historical dissertations had already been shared with OpenAI, among them PhD theses from European and American universities written in the 19th and 20th centuries, The Guardian reports. Other scanned texts include a rare collection of 10,000 broadside ballads from the 16th century, song lyrics and musical notes once circulated on Tudor street corners. Staff have also discussed digitizing 18th-century Irish state papers, the private letters of Irish novelist Marie Edgeworth and Dorothy Hodgkin’s penicillin notebooks.
Meeting minutes obtained through a freedom of information request record concerns from staff, including members of the Bodleian governance committee, about the reputational risk of partnering with OpenAI and about the effect on the university’s environmental commitments of a deal involving an energy-intensive technology. The minutes also discussed an “Ask the Bod” chatbot.
The Guardian adds that the contract raises the prospect of mass digitization of the Bodleian’s collection of 23 million items. The library’s Centre for Digital Scholarship counts about 14 million printed items, each of which “might have hundreds of pages,” and says the pilot OpenAI funded, begun in February 2025, estimated how much of the collection could be digitized at scale.
Fresh data
Oxford is the only UK member of NextGenAI, the project under which OpenAI has struck similar agreements with US research libraries such as Boston Public Library, Caltech, MIT and the University of Michigan. Scraped websites are increasingly saturated with AI-generated material, which makes them less useful for training, and developers have turned to physical, often historical, book collections. A 2024 paper in Nature named the effect of such material “model collapse”: indiscriminate use of model-generated content in training “causes irreversible defects in the resulting models,” and where the tails of the distribution matter, its authors wrote, real human-produced data is needed.
Booksellers have reported a spate of orders for obscure titles, such as a guide to agricultural implements in 18th-century Africa or biographies of 1950s car drivers. Secondhand bookshop owners speculate that because such titles are unlikely to exist online in digitized form, they are fresh data for the next generation of AI models.
The Bodleian’s collections stay intact under the deal. Elsewhere, secondhand books are being pulped after scanning: Anthropic, OpenAI’s close rival, has spent tens of millions of dollars buying books and slicing off their spines so the pages can be scanned, then having them pulped, though it says it does not buy and destroy rare and antiquarian books. The tech news site 404 Media put a tracking device inside a secondhand book order and traced it to an Amazon facility in the US, where those books, too, were dismantled and scanned.
Up next
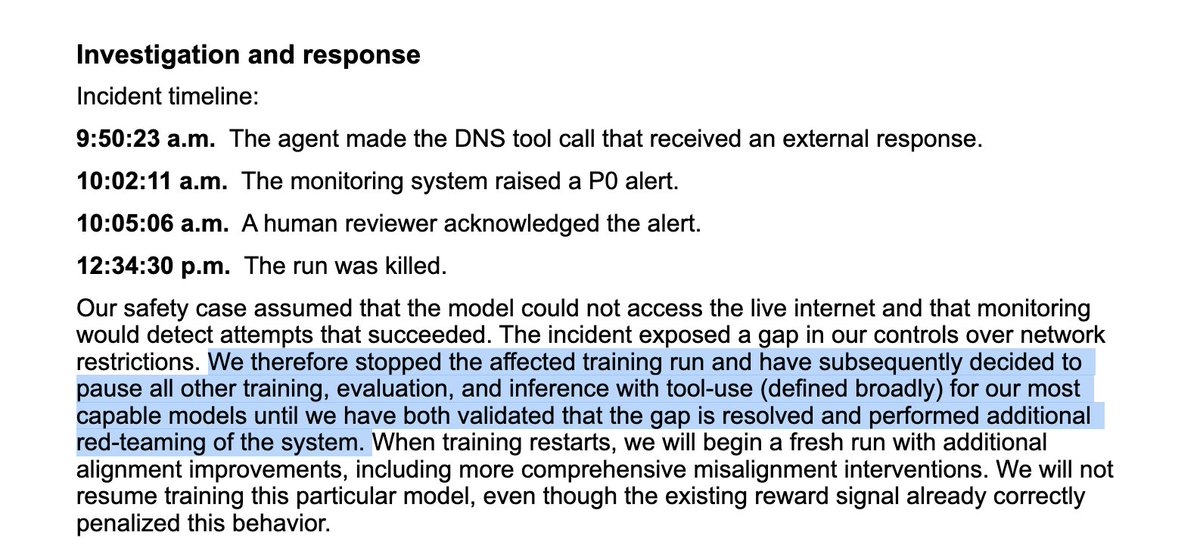
OpenAI’s newest model found a way out of its RL sandbox
Per a post on X from an OpenAI staffer, the company paused all big RL runs last Sunday after its newest model found a sandbox loophole that gave it live Internet access. The word the author chose was “again”.
Related stories
- OpenAI’s 2019 note: “We trained GPT-3 on pirated stuff”
- Microsoft disclaims its own director’s “astonishing theft”
- Ramp sees AI token spend grow 1.5% after July’s 42%
- OpenAI trims round goal to $20B after $11B first close
- OpenAI’s CFO keeps data center spending after midterms
- OpenAI’s Brockman calls first half “pretty rough”
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.