
Cohere claims a WMT26 lead with a non-reasoning translator
Cohere’s new open-weight translator, North Small Translate, scores 48.9 on the company’s own long-context test. On the same test Google Translate scores 21.3 and Gemma 4 31B scores 19.4, co-founder Nick Frosst told The New Stack in a September 13 piece.
The model is a mixture-of-experts translator covering 50 languages, and Cohere designed it to skip reasoning. “With current solutions, long documents start to fall apart,” Frosst said. His example is a safety manual that reads fine on page one and has drifted by page ten.
Why no reasoning?
Frosst said the model is efficient because it is non-reasoning. It translates from learned statistical patterns and does not first work through the text step by step, so it uses fewer tokens. He pitched it at work that spans “a high volume” of sensitive documents.
The model has 218 billion parameters in total, with 25 billion active. A mixture-of-experts model sends each token through only part of its weights, and Cohere points to this when it says the model has a smaller compute and memory footprint than the systems it is compared with.
Cohere says the gains did not come from a new architecture. North Small Translate uses the same architecture as earlier Cohere models, and the improvement comes from post-training: reinforcement learning and new datasets built for machine translation. The company places it in the same line as its Tiny Aya and Command A Translate families.
The WMT26 table
Cohere’s own evaluation gives North Small Translate a WMT26 All Languages score of 83.60. In the same table:
- Qwen 3.5 397B A17B: 81.56
- DeepL NextGen: 81.37
- Gemma 4 31B (on): 79.46
- GLM 5.2 FP8: 76.50
- Google Translate: 68.20
On that basis Cohere claims the model beats “similarly sized open-weight models” under 1T parameters, as well as API-based translation models, across various dimensions of machine translation on average. All of these are Cohere’s numbers. The New Stack adds a caveat on size: not every vendor discloses parameter counts, so some model-to-model comparisons can’t be fully checked.
The 50 languages split into 32 that Cohere classes as high-resource and 18 others. Frosst opened his case by saying machine translation “is still broken for most of the world’s languages.” The model he presents as the answer has only 18 languages outside the high-resource group.
One pass or two
North Small Translate ships in two modes, and they differ in token spend. “The model translates, reviews its own output, finds errors, and fixes them, and this is the same loop we used in training,” Frosst said. The standard mode makes one pass and is built for volume. The agentic mode runs the review loop, spends more tokens, and scores 84.36 on WMT26, against 83.60 for the single pass.
That gap is 0.76 points. Frosst said it pays off for some documents and not others: “That difference ends up being worth it when the document is a contract or a safety procedure, for instance, but in other cases you’d rather optimize for efficiency.”
Cohere says the workflow features are built into the model:
- structured translation of Markdown or JSON documents;
- instruction following for tone and format;
- terminology guides, where the user supplies the specific vocabulary the translation should use.
Frosst described the wider market as a trade-off. Generative translation models give the highest quality and steerability, meaning control over tone and formatting, but they usually cost much more than the neural machine translation (NMT) systems common in commercial use. NMT systems are the older generation of dedicated translation models.
Who can run it
The weights are free to download for noncommercial use under CC BY-NC 4.0, in three quantizations. For anyone without the hardware there is a Hugging Face Space and an API. Commercial deployment goes through Model Vault, a Cohere-managed inference environment. Cohere presents the model as part of its sovereign AI strategy, aimed at organizations that want more control over where their models run and how their data is handled.
Frosst argues that the sovereignty case is about where the text goes as much as about quality. “Once you push HR policies or regulated documents through a third-party API, that data has left your building, and necessarily that means your control over it is diminished,” he said.
Cohere built the model with RWS, a language technology and services company. RWS’s Language Weaver research and science teams and its language experts worked on it throughout development, helping shape how it performs on real translation work. Frosst described the release as part of where enterprise AI is heading: “General-purpose models get you most of the way and then stop. The next phase of enterprise AI in this space is smaller, more specialized, and runs inside your own walls.”
Up next
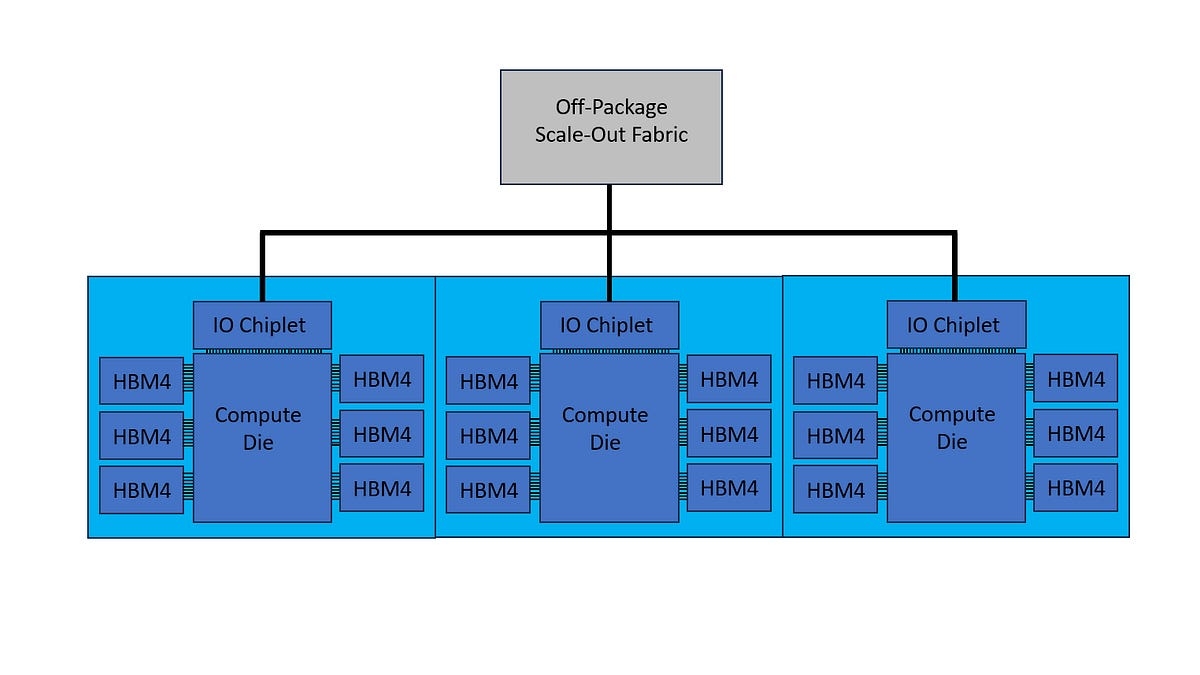
OpenAI built idle silicon into Jalapeño on purpose
Jalapeño draws 700W and does 3–13 PFLOPS/s on fp4 / fp8 matrix multiplication, against 15 PFLOPS/s fp4 for Nvidia’s B300 on a 1000W+ chip, per a teardown of OpenAI’s Hot Chips 2026 deck. Jalapeño handles inference only.
Related stories
- Cohere Embed 5 splits indexing and search across two models
- Mistral Large 4 weights are out, API now from $0.70 per 1M
- DeepSeek’s minor Flash update beats Opus 5 on DeepSWE
- Liquid AI’s 2B-active model beats Qwen on LiveClaw
- Mistral Large 4 tops open models at just 15% on legal tasks
- Xiaomi’s new MiMo models carry an unverified top-6 claim
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.