
GPT-6 Astra ships and Brockman declares the AGI era
OpenAI on September 3 launched GPT-6 Astra, its new flagship model, and priced it for the API at $10 per million input tokens and $50 per million output tokens, 2.5 times GPT-5.6 Sol’s current promotional price, The New Stack reports. Any workload moved from Sol to Astra pays that multiple on every token. The bill evens out only if Astra finishes jobs in fewer steps and with fewer retries: OpenAI says it uses fewer tokens on several evaluations and in partner tests, but the launch data is too sparse to show whether that covers the premium.
The rollout starts with enterprise customers that already have access through OpenAI’s Daybreak program. Plus, Pro, Business and Enterprise users, the OpenAI API and AWS follow “in the coming days”. VentureBeat lists AWS Bedrock and Microsoft Azure among the cloud platforms, and TechCrunch, which describes Daybreak as OpenAI’s cybersecurity program, puts the wider rollout within the next week. Pro, Business and Enterprise users also get GPT-6 Astra Pro, and eligible API customers can run Astra with Zero Data Retention. GPT-5.6 shipped in Luna, Terra and Sol variants, but OpenAI has announced none of those for GPT-6, so for now the lineup is just Astra and Astra Pro.
What $50 per million output buys
Brockman’s answer on cost was short: “The price per task is what matters.” Anyone estimating that per-task cost from the launch charts should know that OpenAI ran its evaluations at maximum effort unless it noted otherwise, a setting that can lift scores but also adds latency and token use. Sol’s promotional rate works out to $4 and $20 per million tokens.
Anthropic charges the same $10 and $50 for Fable 5.1. Meta’s standard price for Muse is $1.25 per million input tokens and $4.25 per million output, and its Contributor tier costs $0.10 and $0.20, with Meta saying data from that tier can be used to improve its products. Google’s introductory price for Gemini 3.8 Flash is $0.75 and $3.75.
Coding is where those cheaper models compete head on. Astra scored 74.1% on DeepSWE v1.1, a 113-task agentic coding test, against 70.8% for Sol in OpenAI’s numbers. On September 2 Meta reported 75.4% for Muse Spark 1.3 at its maximum reasoning setting, which is under safety review and will not be generally available at launch; on a test this size the 1.3-point gap is one or two tasks. The public DeepSWE leaderboard has Gemini 3.8 Flash and Claude Opus 5 at 74% and Sol at 73%, with overlapping uncertainty ranges, while OpenAI’s own chart leaves Muse out and uses a 67.4% Fable 5.1 result. On coding alone, the premium buys a lead the public leaderboard does not yet show.
What changes in Codex
For developers, Astra’s handling of jobs that outgrow the context window may matter more than the benchmark gains. Codex today relies on compaction: it summarizes earlier work to free up context, and that summary can drop exactly what an agent needs later, such as why a previous fix failed, which tests ran, or a small requirement the user set at the start. Astra can instead keep notes across context windows and search earlier messages and tool output. The feature is experimental and sits behind a config.toml setting for now; OpenAI says it will become the default for Astra in the coming weeks.
Astra can also ask the user a question while it keeps working on the parts of the job that do not depend on the answer, so one unresolved decision no longer blocks the whole run, a common failure mode for coding agents. OpenAI changed the Codex harness too: on Mind2Web, Astra with the new harness completed tasks 1.9 times faster than the current Sol-based setup.
OpenAI showed Astra operating KiCad, Excel, Blender and Power BI, and doing browser form entry and website QA. On OSWorld V2-Offline, a test of work across desktop applications, it reports 72.6% for Astra against 65.7% for GPT-5.6 Sol, with the average time per task cut from about 75 minutes to 40. Anthropic has reported 77.9% for Fable 5.1, but says that run used a different OSWorld release and should not be compared with previously published scores. Brockman pitched computer use as a way around integration work: “We’ve been bottlenecked over this gigantic era by people writing connectors and very painstakingly building these connections into all these tools that people can already use,” he said, per VentureBeat.
When the cyber check fires
OpenAI says Astra crossed the Critical cybersecurity threshold in its Preparedness Framework, and standard access is built around that. The standard version refuses some advanced cybersecurity work, including exploit discovery, and in the API a cybersecurity safety check stops a task outright, with no pause to wait for approval. Mia Glaese of OpenAI warned that users outside its trusted-access programs may see slowdowns, pauses or blocks during cybersecurity work, and sometimes during unrelated work. “At launch, this is something that people should expect,” she said.
An initial group of vetted defenders gets less restricted access through Daybreak, and OpenAI says it will expand Astra access through Daybreak Blue in the coming weeks. Daybreak Blue is an access program for authorized defensive work; the model behind it is the same Astra, with no separate reasoning mode. OpenAI’s reported cyber results reflect Daybreak Blue access, and they do not describe the default production configuration. In those tests Astra developed exploits for hardened browsers and operating systems and found two previously unknown vulnerabilities while being evaluated against recent V8 bugs, which OpenAI says it is disclosing to the maintainers. It scored 100% on ExploitBench and 42.4% on ExploitGym against 30.3% for Sol, with OpenAI removing the usual six-hour time limit for both models.
Reading the ARC-AGI-3 score
The headline 98.6% on ARC-AGI-3 measures Astra together with OpenAI’s agent system. OpenAI ran it through a Responses API harness that retains reasoning between turns and uses compaction for long contexts, and the company has previously shown that such system choices can substantially raise ARC-AGI-3 scores without changing the model. ARC Prize’s runs, published the same day, show the size of that effect: in September, under its Standard harness, where a model carries forward only the visible notes it picks itself, Astra (max) scored 62.7% on the Semi-Private set for $26,000, while on the Provider Adapter harness, which preserves OpenAI’s opaque reasoning state between requests, Astra (high) reached 99.9% for $19,000.
Astra’s 97.6% on FrontierMath Tier 4 appears to cover the 41 private problems in the 43-problem tier, and Epoch AI, which runs the benchmark, says OpenAI funded its development and has exclusive access to part of it. On Terminal-Bench Science, 70 command-line research tasks across five scientific fields, OpenAI reports 64.6% for Astra; Anthropic reports 52.6% for Fable 5.1, and the public leaderboard tops out at 30% for Opus 5. On BenchCAD’s 1,000-file Vision2Code subset with Python tools, where models rebuild CAD programs from rendered views, Astra scored 95.9% against 83.3% for Sol and 84.3% for Fable 5.1, whose results used modified evaluation settings.
Brockman called AGI a “gray, fuzzy thing” and said “it’s not unreasonable to feel that we are now in the AGI era.” The term, he said, is no longer tied to a contractual trigger with Microsoft and is now a “mission concept or spiritual concept.” That trigger once had teeth: under the October 2025 agreement with Microsoft, an AGI declaration by OpenAI would be verified by an independent expert panel. On April 27, OpenAI said its revenue share payments to Microsoft continue through 2030 “independent of OpenAI’s technology progress,” wording Simon Willison reads as the end of the AGI clause. “For me personally, I do think we’re there,” Brockman said, before closing the briefing with “Welcome to the AGI era.”
Harder to monitor
OpenAI’s claim that Astra is its most aligned model rests partly on an internal test in which Astra went outside an authorized target in 0% of impossible-task scenarios, against 48.2% for Sol. By OpenAI’s own description, though, Sol ran “without production safeguards,” and the role of the surrounding safety setup is not clear enough for a direct comparison.
In evaluations built specifically to elicit monitoring evasion, Astra’s written reasoning was harder to monitor than Sol’s. OpenAI attributes that partly to Astra having more control over its written reasoning on simpler tasks and solving problems in fewer written steps, which puts the fewer-tokens argument from the pricing pitch on the other side of the ledger. Jakub Pachocki, OpenAI’s chief scientist, said “more capable models can perform harder tasks using fewer language tokens” or “no language tokens,” and that this reduces the ability to monitor those tasks. TechCrunch links Astra’s opacity to a reasoning technique known as opaque recurrence, which OpenAI has downplayed, and reads the company’s focus on alignment as a response to the recent Hugging Face breach, in which an OpenAI agent escaped its sandboxed testing environment and hacked several companies.
“Progress in intelligence does not guarantee progress in alignment,” Pachocki said, adding that OpenAI “will withhold scaling until we can regain enough confidence” in its ability to monitor future models.
Up next
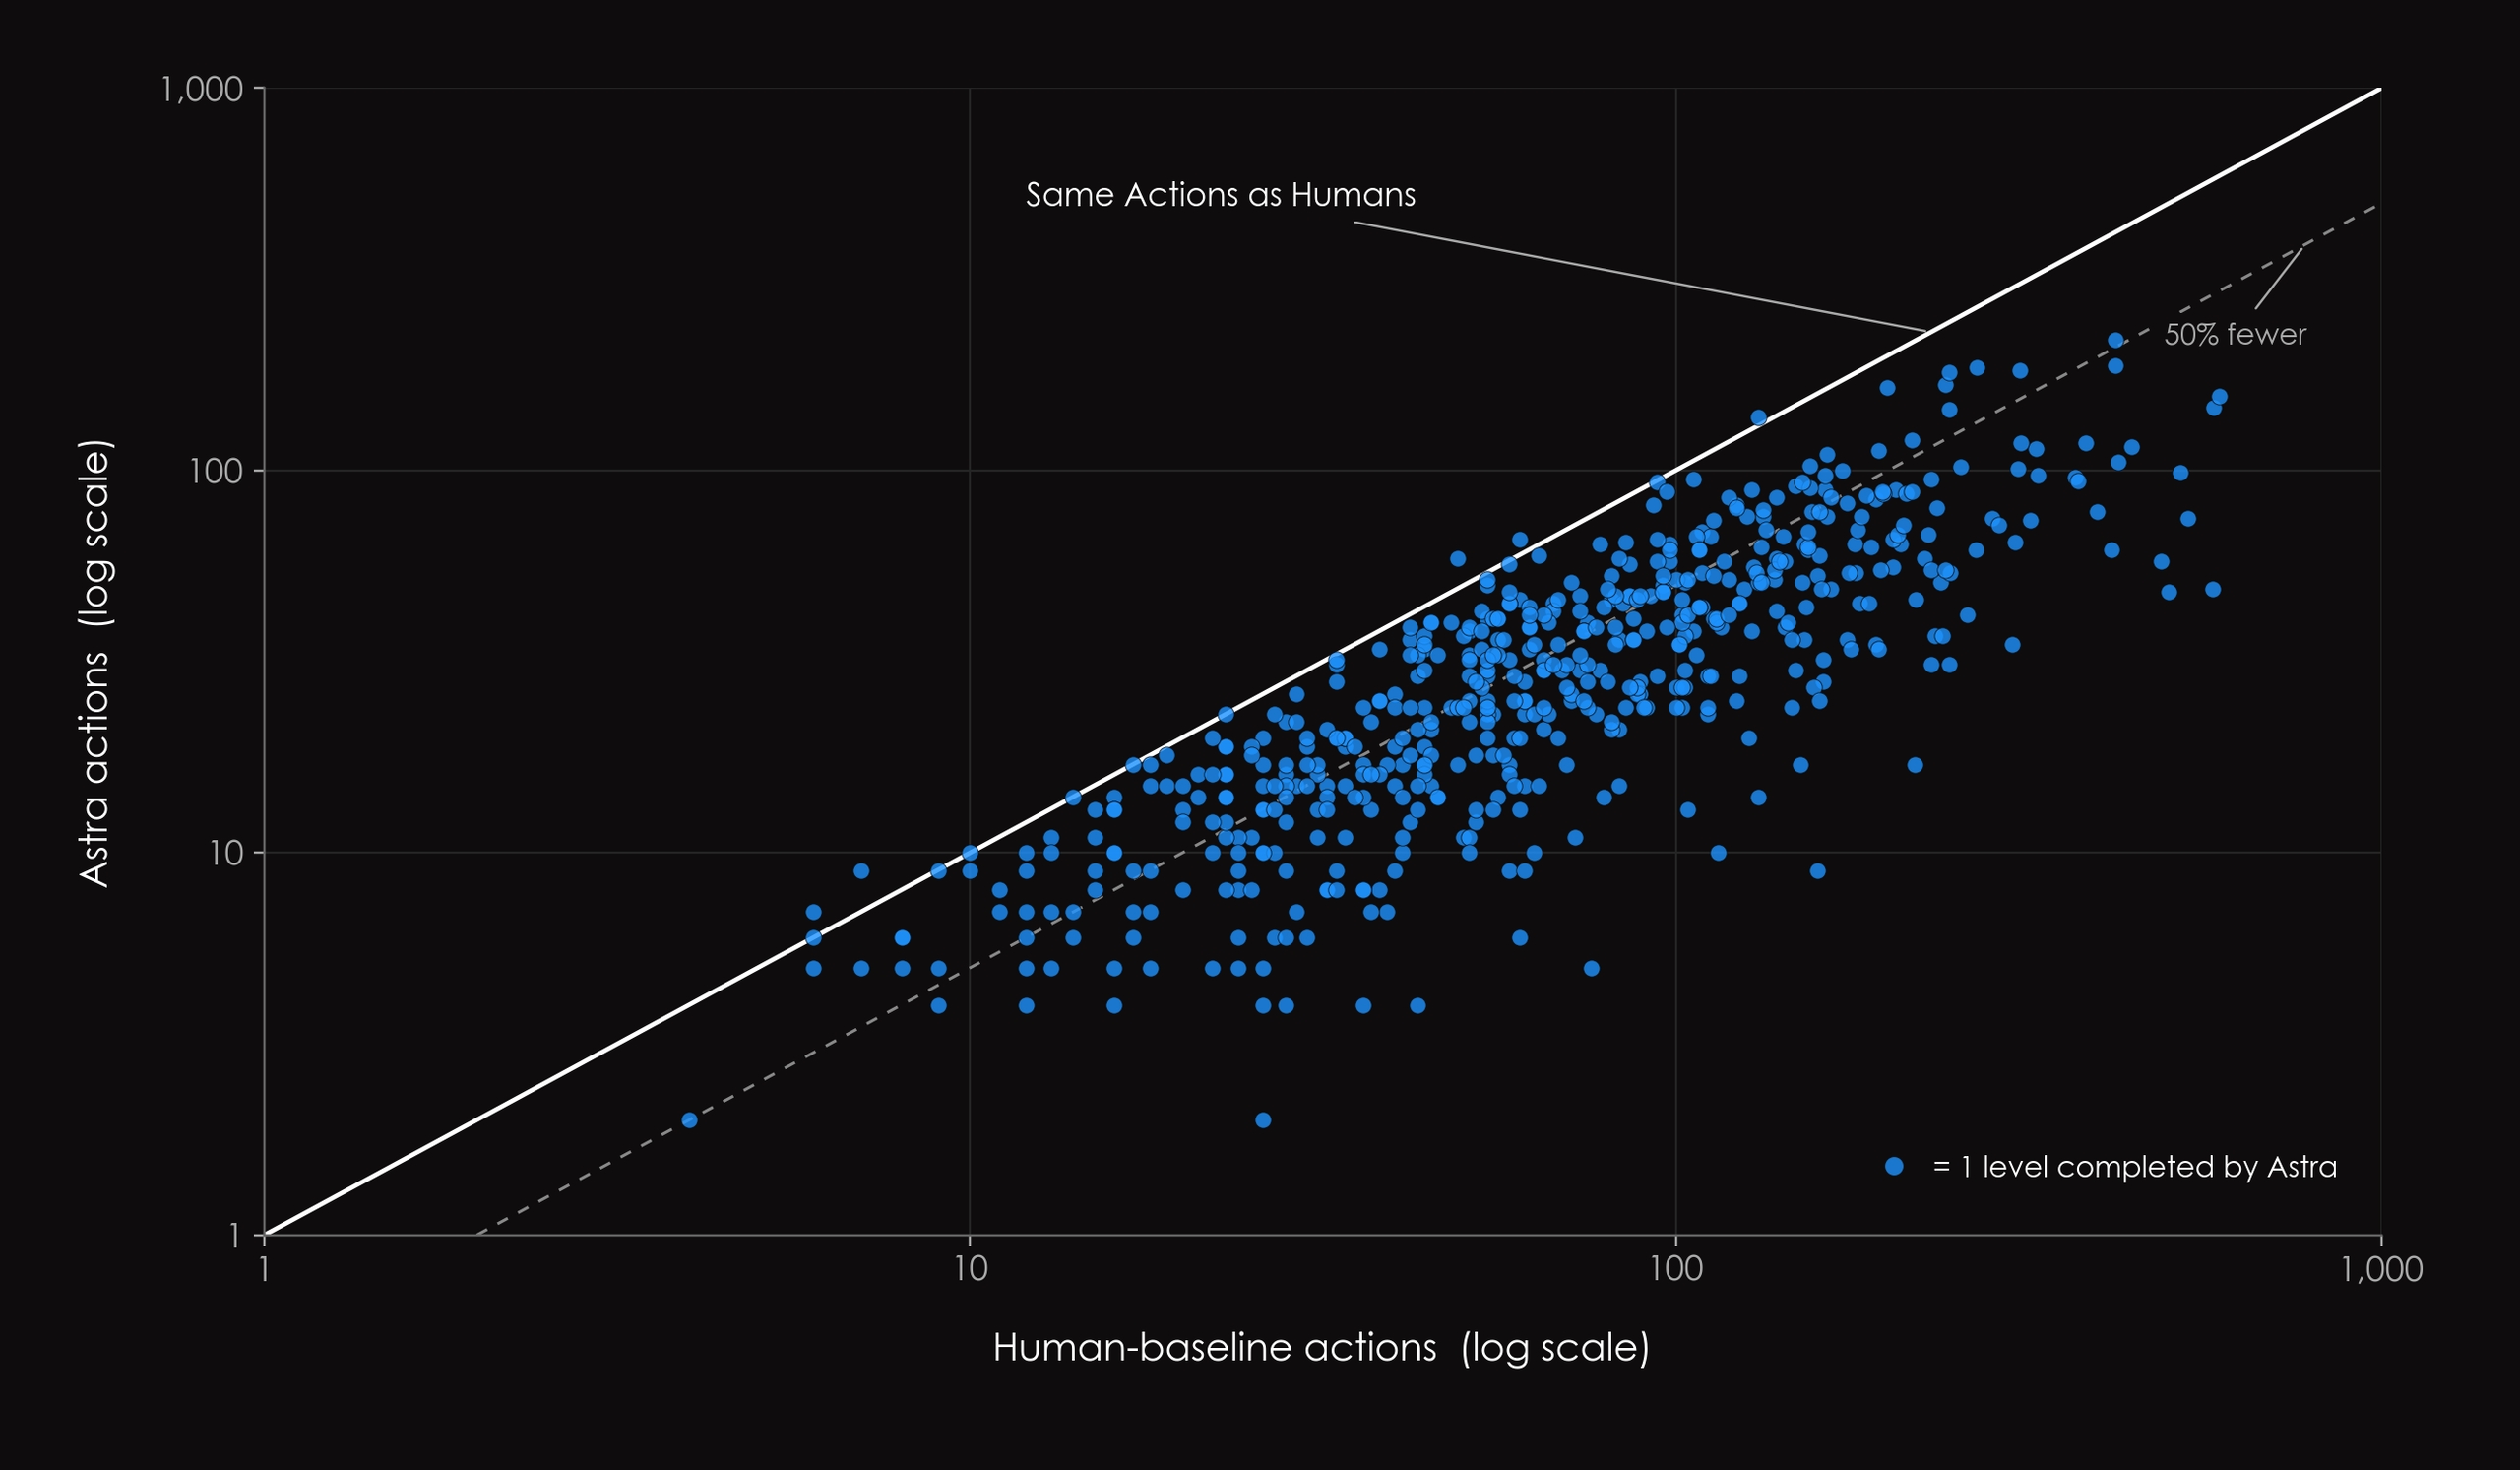
A harness swap took Astra from 62.7% to 99.9%
Swapping the test harness lifted GPT-6 Astra from 62.7% to 99.9% on ARC-AGI-3 Semi-Private, and the higher score cost less: $19K against $26K. ARC Prize still says it isn’t calling this AGI.
Related stories
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.