
anthropic
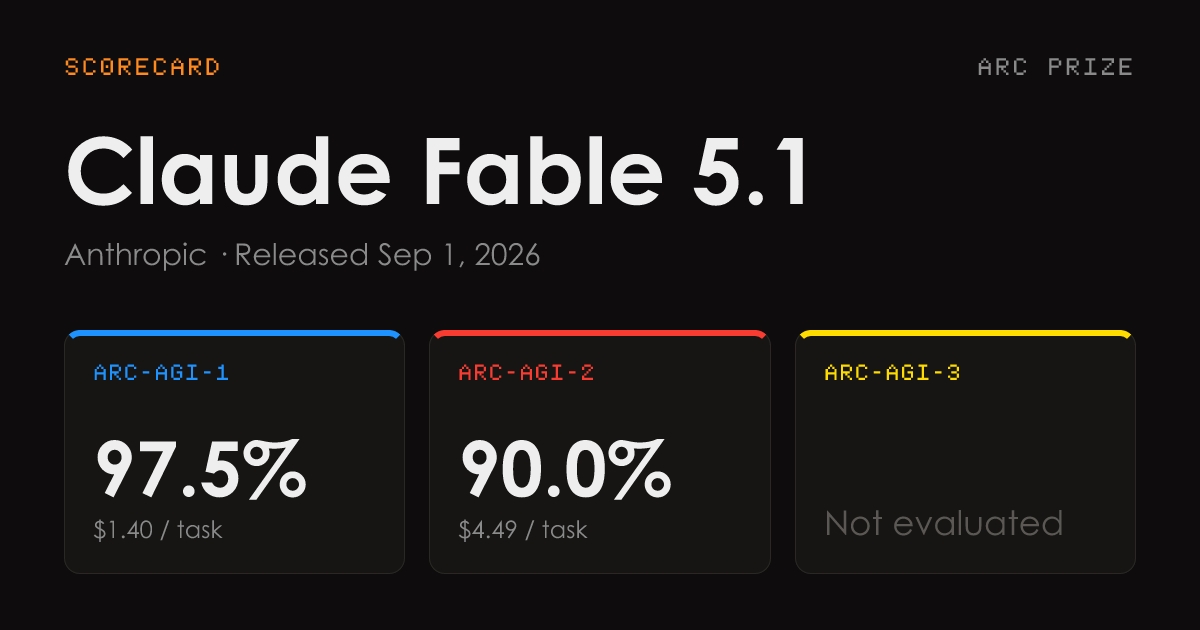
90.0% on ARC-AGI-2 at $4.49 per task
Promtime
 anthropic
ARC Prize has published verified ARC-AGI scores for Anthropic's Claude Fable 5.1, and at maximum reasoning effort the model reaches 97.5% on ARC-AGI-1 Semi-Private at $1.40 per task and 90.0% on ARC-AGI-2 Semi-Private at $4.49 per task.
The results entry published by ARC Prize is dated 1 September 2026 and covers five reasoning variants tested across both benchmarks. Alongside the aggregate figures, the page publishes per-task pass/fail grids for the ARC-AGI-1 and ARC-AGI-2 public eval sets and links to an Anthropic blog post.
At a glance
- The five variants were graded separately from Max down to Low, and the results entry pairs each accuracy figure with the reasoning level that produced it rather than reporting a single model score.
- On ARC-AGI-2 the variants run from 90.0% at both Max and XHigh down through 88.8% at High and 86.3% at Medium to 78.3% at Low, an 11.7-point spread.
- Cost travels with accuracy on the results page: max effort on ARC-AGI-2 Semi-Private runs at $4.49 per task, more than three times the $1.40 per task on ARC-AGI-1 Semi-Private.
The pairing of accuracy with cost per task is what makes this kind of scorecard useful: a leaderboard position that ignores spend tells a team little about which configuration to deploy. Reading the spread across the five variants, the top of the effort range appears to buy very little, which is the sort of finding that pushes practical work down toward the middle settings rather than the headline one.
ARC-AGI-1 scores fall from 97.5% at Max to 90.0% at Low
The verified scores table lists ARC-AGI-1 results of 97.5% at Max, 96.5% at XHigh, 96.0% at High, 94.5% at Medium and 90.0% at Low. On ARC-AGI-2 the same five variants score 90.0%, 90.0%, 88.8%, 86.3% and 78.3% in the same order.
At maximum reasoning effort the ARC-AGI-1 Semi-Private score of 97.5% is priced at $1.40 per task, while the ARC-AGI-2 Semi-Private score of 90.0% at that effort level is priced at $4.49 per task. XHigh matches Max on ARC-AGI-2 at 90.0% and trails it by one point on ARC-AGI-1, at 96.5%.
The largest single step between adjacent levels in the ARC-AGI-2 column sits between Medium and Low, 86.3% down to 78.3%, a drop of eight points. On ARC-AGI-1 the same pair of levels differs by 4.5 points, 94.5% against 90.0%.
One task in each public eval set fails at all five reasoning levels
The results entry publishes pass/fail grids for the 120-task ARC-AGI-2 public eval set and the 400-task ARC-AGI-1 public eval set, marking each task at all five reasoning levels. In the ARC-AGI-2 grid, task 88e364bc is the only one recorded as failed at every level; in the ARC-AGI-1 grid, that applies to 0d87d2a6 alone.
The grids also record tasks that a lower reasoning level solves while a higher one misses. ARC-AGI-2 task 88bcf3b4 passes only at High, and 800d221b fails at Max, Medium and Low while passing at XHigh and High. On ARC-AGI-1, f3b10344 fails at Max and XHigh but passes at High, Medium and Low.
Sixteen other models share the ARC-AGI-2 leaderboard with Claude Fable 5.1
The ARC-AGI-2 leaderboard lists Claude Fable 5.1 next to sixteen other entries, among them Claude Fable 5, Claude Opus 5, DeepSeek V4 Pro 0813, Gemini 3.7 Flash, GPT-5.6 Sol, GPT-5.6 Terra, Grok 4.6, Inkling and Kimi K3. The list also includes DeepSeek V4 Flash 0731, Gemini 3.5 Flash-Lite, Gemini 3.6 Flash, GPT-5.6 Luna, GPT-5.6 Luna 2026-07-30, Grok 4.5 and Inkling Small.
Each of those sixteen entries is recorded with two or three tested versions, marked v1 and v2 or v1 through v3. The Claude Fable 5.1 row carries no version marker, and its five reasoning variants are listed in the verified scores table.
Unpriced levels and ARC-AGI-3 The ARC-AGI-3 column of the verified scores table is blank for all five reasoning variants. Cost per task is published only for the max-effort runs, $1.40 on ARC-AGI-1 Semi-Private and $4.49 on ARC-AGI-2 Semi-Private, so the price of the XHigh, High, Medium and Low configurations remains unstated. The pass/fail grids for those levels record outcomes only.
Comments
No comments yet. Be the first.
Join the conversation
Sign in with Google to leave a comment. Your name and avatar come from your Google profile, and the comment appears after moderation.
We only use your name and avatar from Google. We never store your email address.