
Max effort adds nothing to Fable 5.1’s ARC-AGI-2 score
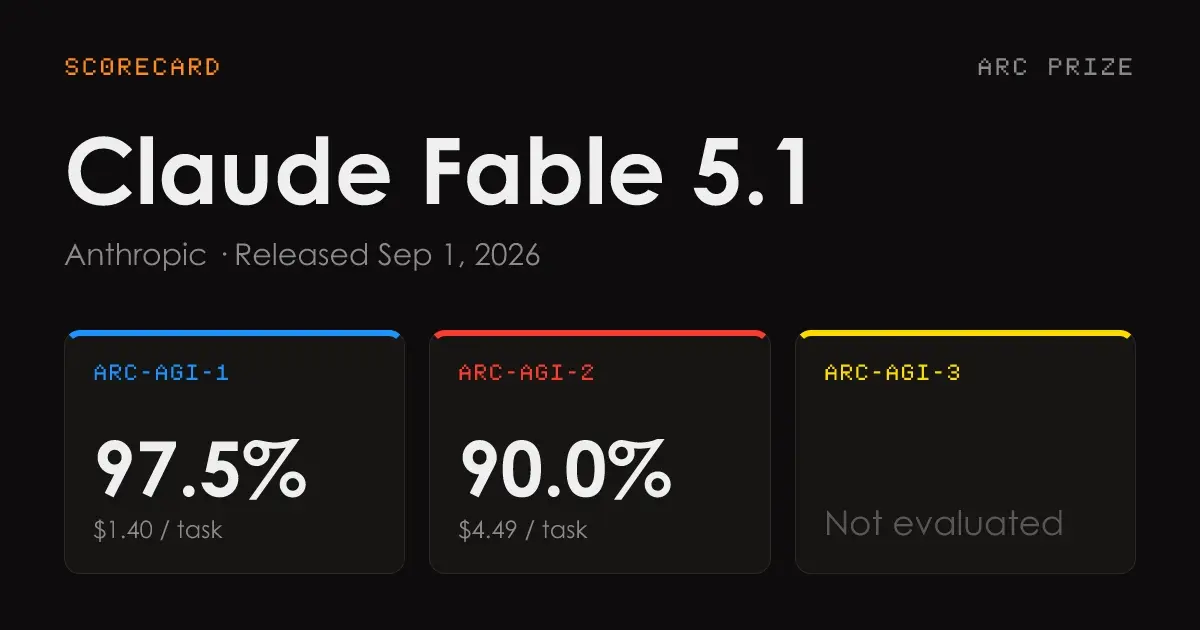
Claude Fable 5.1 scores 90.0% on ARC-AGI-2 at max reasoning effort, at $4.49 per task, in verified results ARC Prize published on September 1. Fable 5 scored 89.2% at the same setting for $5.45 per task, so the new model edges ahead on the harder benchmark and costs about 96 cents less per task to do it.
ARC-AGI-2 shows a model a few pairs of colored grids and asks it to work out the transformation rule from those examples, then apply it to a new grid. The tasks are built to be easy for people and hard for models. All verified scores come from the Semi-Private set, a pool of tasks kept out of public release. The baseline here is ARC Prize’s own results page for Fable 5, which launched on June 9 with the same five reasoning levels. On ARC-AGI-2, every level moved up:
- Max: 89.2% → 90.0%
- XHigh: 88.3% → 90.0%
- High: 87.5% → 88.8%
- Medium: 82.5% → 86.3%
- Low: 76.8% → 78.3%
Medium moves the most. XHigh now lands on exactly the same 90.0% as Max, so on ARC-AGI-2 the top setting buys no extra accuracy. Fable 5.1 at High, 88.8%, comes in just under Fable 5 at Max.
ARC-AGI-1, the older benchmark in the same format, moves the other way at the top. Fable 5.1 scores 97.5% at Max and 96.5% at XHigh, against 98.5% at both settings for Fable 5. In the middle the new model is ahead: 96.0% against 95.5% at High, 94.5% against 92.5% at Medium. Low slips slightly, from 90.5% to 90.0%. On ARC-AGI-1, Fable 5.1’s Max run costs $1.40 per task. As of August 3, ARC Prize had Fable 5 leading ARC-AGI-1 with 98.5%, at $1.02 per task on xhigh or $2.11 on max. So Fable 5.1 loses a point at Max, and its Max run lands between those two prices.
The page also has pass/fail tables for each reasoning level, covering 120 public ARC-AGI-2 tasks and 400 public ARC-AGI-1 tasks. These are separate from the Semi-Private sets behind the headline scores. More reasoning effort does not always mean more tasks solved. On the ARC-AGI-2 public tasks, Max misses three and XHigh misses two. Task 88e364bc fails at all five levels. 88bcf3b4 passes only at High. 800d221b passes at XHigh and High but fails at Max, Medium and Low. Four tasks, dbff022c, dd6b8c4b, e12f9a14 and faa9f03d, pass only at Max and XHigh. ARC-AGI-1 shows the same pattern. f3b10344 fails at Max and XHigh but passes at the three lower levels, and 0d87d2a6 fails at every level.
The ARC-AGI-3 column is still empty for all five Fable 5.1 variants. ARC-AGI-3 is the interactive benchmark, where agents play turn-based games with hidden rules. For Fable 5, ARC Prize said in August that ARC-AGI-3 testing was still underway.
ARC-AGI-2 standings have changed since then. The board was rebuilt on September 24, when Gemini 3.8 Flash entered at 89.2, and again on September 28. After those rebuilds, GPT-6 Astra led ARC-AGI-2 at 95.0, with Fable 5.1 second at 90.0.
Up next
Fable 5.1 becomes the default model in Claude Code 2.1.257
Fable 5.1 takes the default Fable slot in Claude Code, 1M context at $10/$50 per Mtok. Claude apps gateway sessions keep resolving fable and best to Fable 5 for now, because unconfigured gateways reject it.
Related stories
- Andon Labs puts GPT-6 Astra ahead of Claude Fable 5.1
- Fable 5.1 tops Artificial Analysis at 66, costs 20% more
- Cache reads get 75% cheaper on Claude Fable 5.1
- Haiku 5.5 ranks #2 of 182 and burns 440M tokens doing it
- Sonnet 5.5 hits third place by writing 410M tokens
- Sonnet 5.5 edges past Opus 5.5 on Terminal-Bench 4.0
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.