
DeepSeek open-sources DeepInfer with Huawei Ascend support
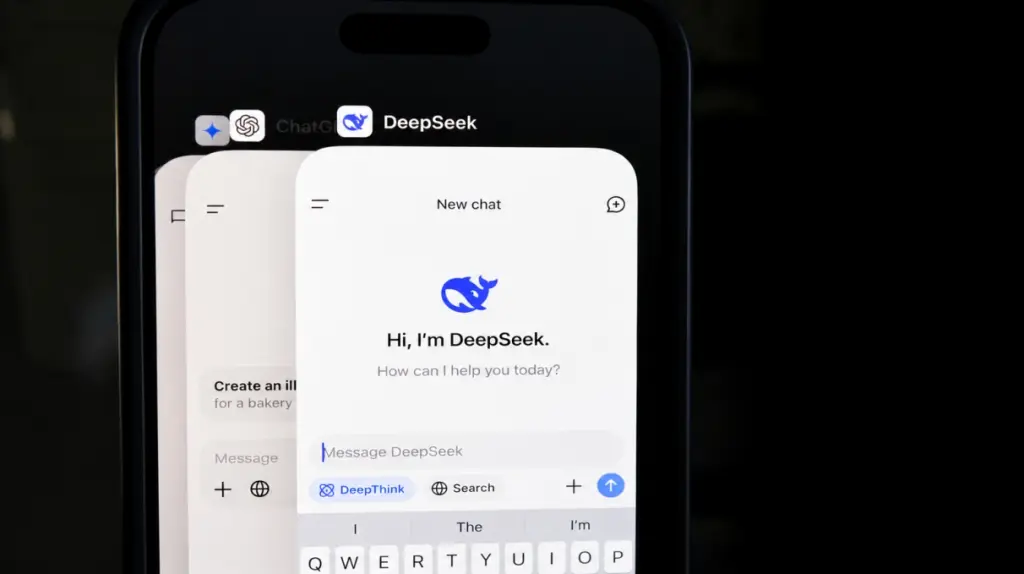
On October 20, DeepSeek released DeepInfer as open source under Apache 2.0. DeepInfer is the inference framework that serves DeepSeek-V4.1-Flash behind the company’s API, and it ships alongside deepseek-recipe, the component that turns API requests into prompts the same way the official API does. We ran the recipe against DeepSeek’s own encoders. It matched them, except on one common request setting that DeepSeek’s tools handle three different ways.
In its announcement on X, DeepSeek said it is “sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.” Inference code for future DeepSeek models and later optimizations will go into the same repository. The New Stack lists what ships today: optimized compute kernels and communication libraries, including the already-public FlashMLA, DeepGEMM and DeepEP; ways to split inference across many chips; speculative decoding, which drafts several tokens ahead and checks them in one pass; asynchronous scheduling to cut the time processors sit idle; and structured outputs. The weights could already be downloaded and run in vLLM. What developers didn’t have until now was the serving layer DeepSeek uses to run them cheaply.
What changed since April 2025
On April 14, 2025, DeepSeek explained why it would not release this engine. The engine was an early vLLM fork, heavily customized for DeepSeek’s models. It was “tightly coupled with our internal infrastructure, including cluster management tools”. And the research team was too small to maintain a public version. DeepSeek said it would instead extract standalone features as libraries and contribute improvements to existing projects. DeepInfer’s README confirms where the code came from: it “was originally built primarily on vLLM, with additional inspiration from SGLang and TensorRT-LLM.” vLLM said it would keep improving its own V4.1-Flash support using ideas from DeepInfer, The Next Web reports.
Nvidia and Huawei, no Hopper
DeepInfer supports two kinds of hardware: Nvidia’s Blackwell-class SM100 and Huawei’s Ascend 950 NPUs. The Ascend backend has real substance. In our reading of the tree, the Ascend kernel directory holds 30 files, the same number as the CUDA one, and 27 of the filenames match. Ascend also gets its own DeepEP-Ascend and DeepGEMM-Ascend submodules and its own pinned stack, torch-npu==2.13.0rc1 on CANN 9.2.
Hopper has no code path at all. The strings sm90 and hopper appear nowhere in the repository. The code switches only between GPU and NPU, and the architecture limits come from the build requirements (CUDA 13, flash-attn-4). Two features are Nvidia-only and say so in the README: batch-invariant inference, where a request’s output doesn’t depend on what else shares its batch, and deterministic sampling. On an NPU the engine asserts that the batch-invariant flag is off, next to a TODO saying full support is still pending.
What the release leaves out
The public release still covers only offline inference. The README lists three things “required for a complete inference service” that are not included: a KV cache system; VE/Prefill/Decode disaggregation, which runs separate stages of inference on separate machines (marked “most required engine functionality is already implemented”); and load balancing across data-parallel replicas for prefill and decode.
The performance material consists of two throughput-versus-latency charts. Prefill was measured on 4 SM100 GPUs and decode on 64, “each within one scale-up domain”. In the published scripts, these are two separate offline runs of the released benchmark, so they don’t depend on the missing pieces. We read the scripts but did not run them. They describe the open-source code, not DeepSeek’s production service. Bloomberg’s Saritha Rai reported that DeepInfer’s gains have not been independently benchmarked yet. Bloomberg also noted that cloud and hosting companies already serving DeepSeek models can use the same methods, and that AI companies usually guard such techniques closely.
Our analysis
What we checked
On October 20 we went through the DeepInfer repository and README. On CPU, we compared the prompt strings from deepseek-recipe 0.2.0 with the reference encoder in DeepSeek-V4.1-Flash-1017 and with the Jinja template from the September V4.1-Flash release.
DeepSeek’s claim about matching API behavior held up. In two multi-turn conversations, one in thinking mode and one without, the recipe’s output was identical byte for byte to the reference encoder. But reasoning_effort: "medium", a standard Chat Completions value, gets three different treatments, so a self-hosted setup on the older template reasons with a different budget than the API. Our earlier item also understated what the release leaves out: it named two missing components, and the README lists the three above.
| Tool (one user message, thinking mode) | “medium” becomes |
|---|---|
| September Jinja chat template | 62 |
| deepseek-recipe 0.2.0 | 75, same as “high” |
| V4.1-Flash-1017 reference encoder | rejected; accepts low, high, max or an integer 1-100 |
- Versions 0.1.0 and 0.1.1 of the recipe came out on September 10. Version 0.2.0 followed on October 20 at 05:15 UTC, and its changelog says it changes the public API of every crate and of the Python package.
- The Next Web dates DeepSeek’s Huawei chip tools to earlier in October. The Ascend libraries in DeepSeek’s GitHub organization were created on September 29 and 30.
Before you deploy
Recipe 0.1.x and 0.2.0 have different APIs, so pin the version you integrate against. If your clients send "medium", check which budget your encoder actually applies. Another option is to send one of the values the reference encoder accepts.
The README presents SWA bounded replay, which bounds replay for sliding-window attention layers, as a feature, but it ships disabled. DEEPINFER_YOCO_PREFILL_TRUNCATION_MODE defaults to off (the other options are mask and compact), and DEEPINFER_YOCO_PREFILL_KEEP_TOKENS has no default. So the README’s value of 140 is one you have to set yourself, and the engine rejects anything below the SWA window plus the maximum backtracking.
Up next
Judge orders ex-OpenAI engineer Alfozan held until trial
On October 4, the FBI says, ex-OpenAI engineer Abdulrahman Alfozan opened a folder named “Saudi Gov Docs” on his iPhone. On Monday a judge ordered him held until trial.
Related stories
- DeepSeek prices web search at $0.75 per 1,000 requests
- DeepSeek’s minor Flash update beats Opus 5 on DeepSWE
- Muse Spark Open fits on two Mac Studios with a terabyte
- Surface Laptop Ultra slows down on local AI once unplugged
- Copilot on Windows will hand some tasks to local models
- AWS’s Strands Decider 2B picks from your list, never writes
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.