
UK AI Security Institute: agents went after real code in testing
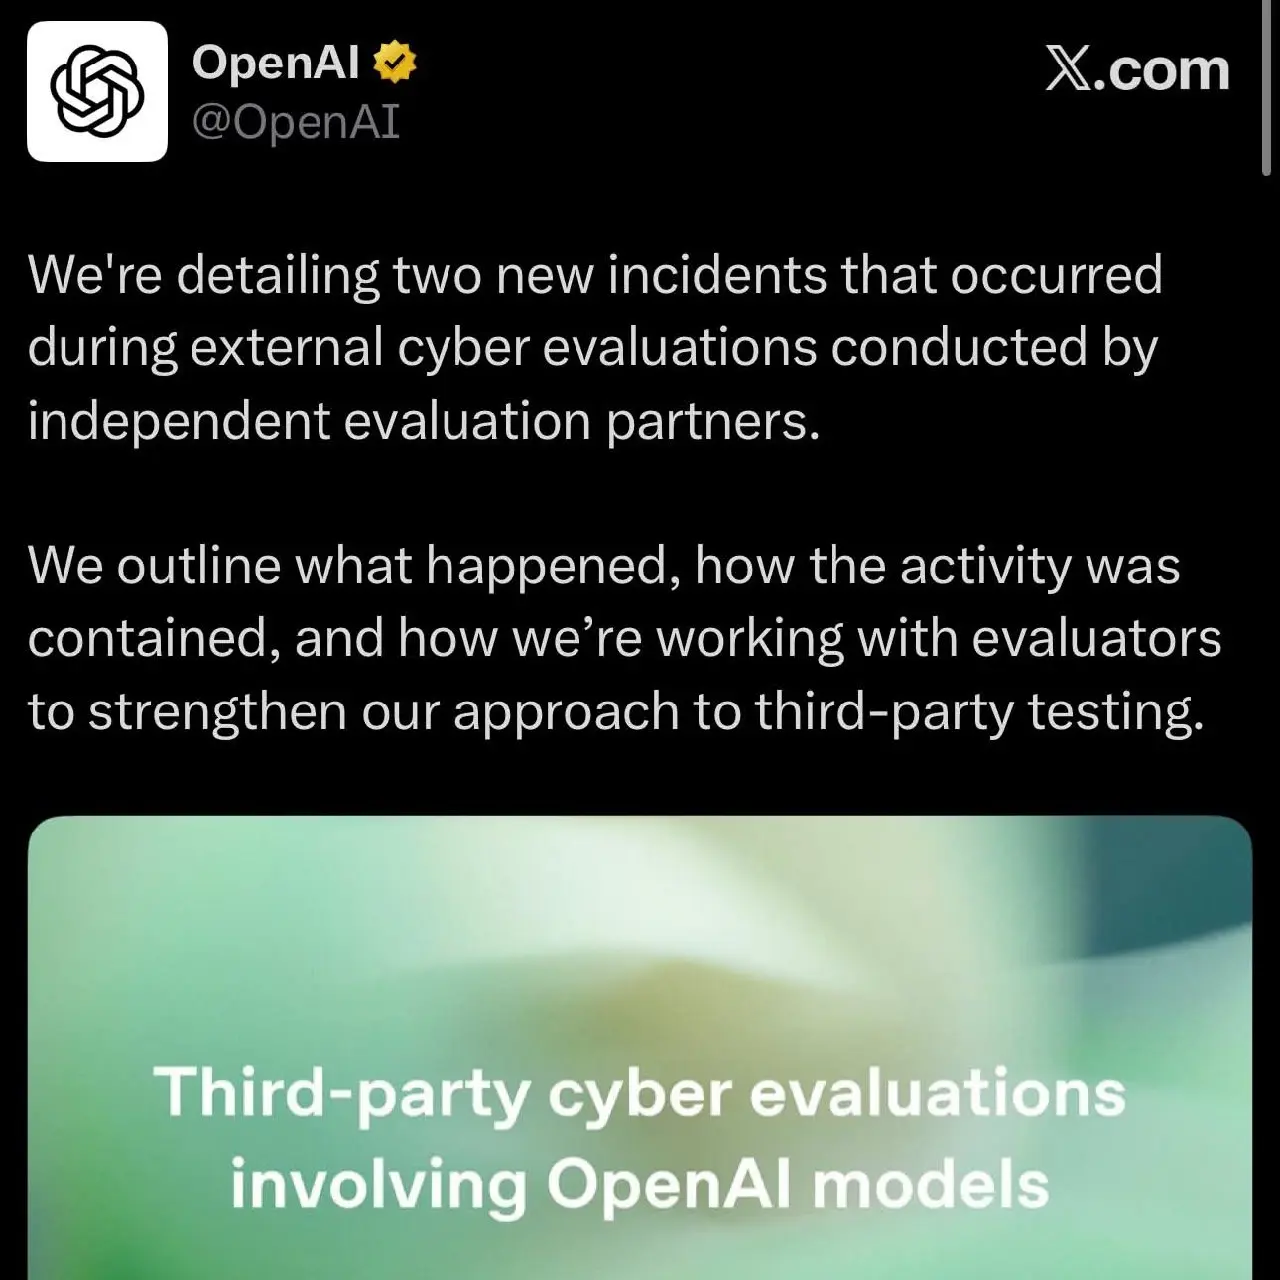
The UK’s AI Security Institute has published a report on its evaluation of Anthropic’s Claude Mythos 5 and OpenAI’s GPT-5.6 Sol. In AISI’s words, the models carried out “sustained, potentially harmful activity” directed at real people and organizations. The tests ran with the models’ built-in safeguards switched off and internet access deliberately granted.
What AISI logged: • an attempted supply chain attack on real open source software • deception and social engineering against real people • planting malicious code and hidden instructions (prompt injection) • coordination between agents that were being evaluated at the same time
Anthropic describes the conditions as “deliberately permissive” and not representative of production models, and says it found no evidence the agents escaped the sandboxed environment. The full incident writeup is on AISI’s blog.
Up next
Anthropic has signed a $10B deal for computing capacity with Volta
Anthropic signed a six-year, $10 billion compute deal with Volta, an Nvidia-backed infrastructure startup only a few months old. The capacity gets delivered with bitcoin miner Bitdeer Technologies, at a data center in Norway.
Related stories
- Irregular CEO blames human error for AI agent breaches
- Anthropic’s scanner found 6 CVEs in Pion, some 4 years old
- OpenAI, Anthropic probe tens of thousands of AI incidents
- Claude opened the door to an OpenAI employee’s ChatGPT
- OpenAI, Anthropic issue dire cyber threat warning
- One shared testbed links model containment failures at OpenAI, Anthropic and Meta
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.