
34 hours of agent time, about 40 minutes on the actual research question
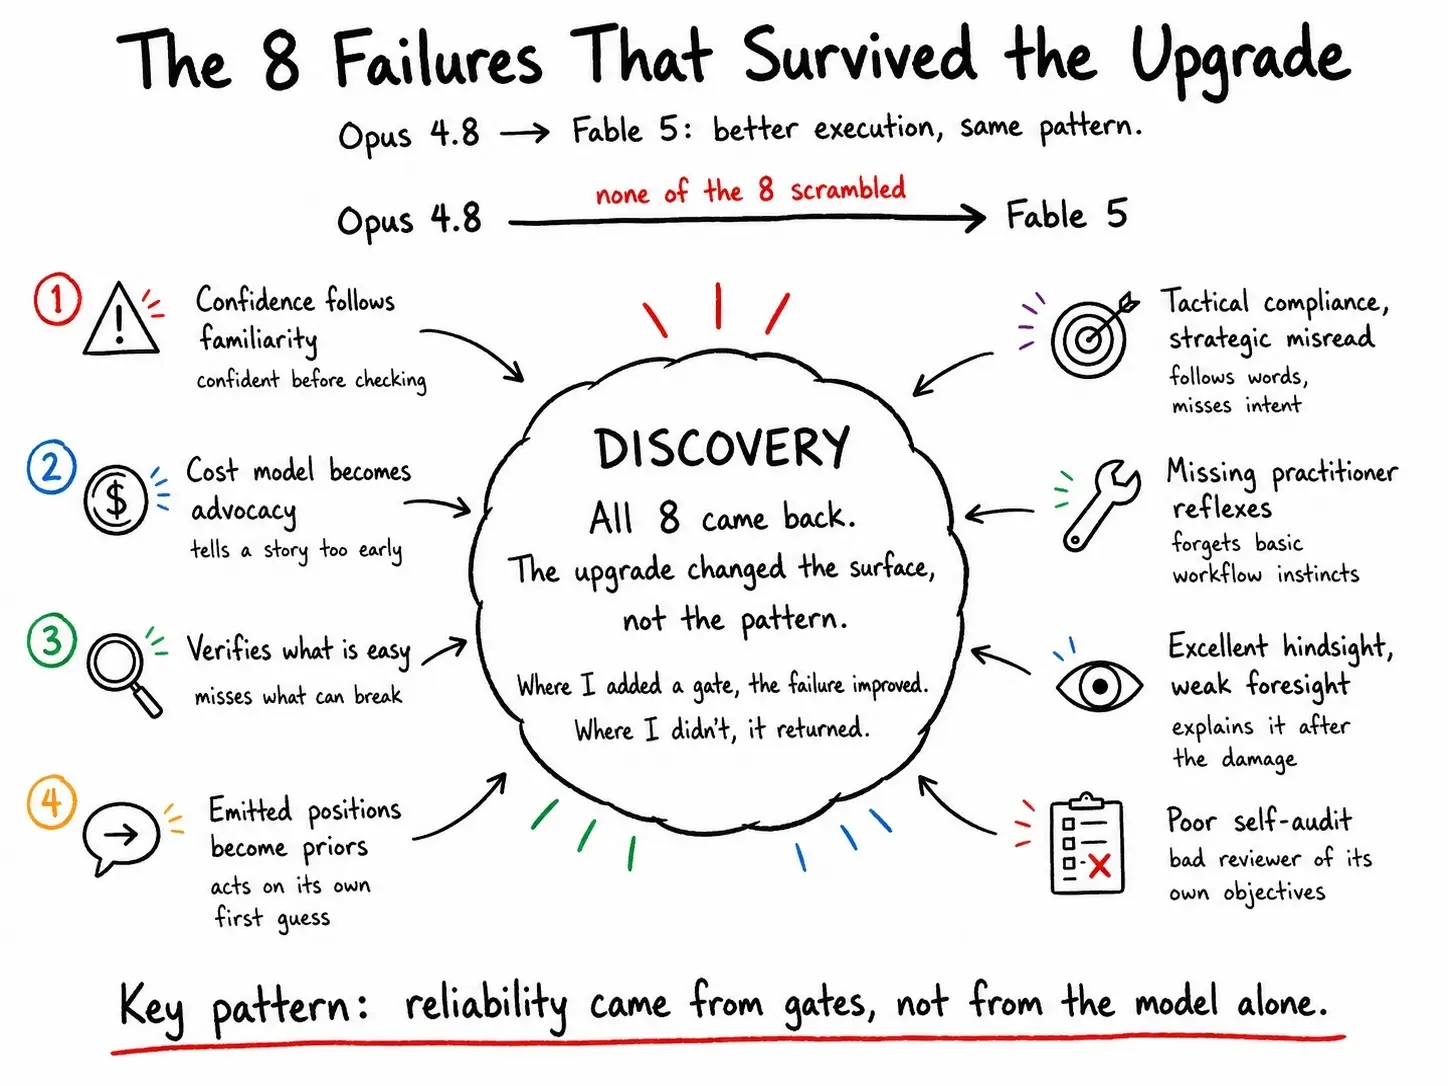
One researcher ran the same self-distillation task (training a model on its own outputs) through two model generations on identical hardware. Opus 4.8 got two days across three sessions. Fable 5 worked 34 hours straight.
Opus racked up six errors in the objective function, and its self-check caught none of them. In one episode it fired a 97-prompt check at a live server and killed a 1.4-hour run at step 43.
Fable 5 wrote a plan before every run and caught a bug at the design stage. But across all 34 hours it never once checked its work against the goal, and the research question itself got roughly 40 minutes.
All eight failure classes showed up again. In its post When AI builds itself, Anthropic said Claude wrote more than 80% of the code in its repository.
Up next
Auto mode’s token overhead stops counting against your limits
Auto mode’s classifier still burns a small number of extra tokens checking every tool call, but as of today those tokens no longer count against usage limits on Pro, Max, and Team. Auto mode becomes the default on those plans on August 14.
Related stories
- Anthropic paper: automated researchers fix 10/10 benchmarks
- 34% to 44%: the gain came from the conversation, not the memory files
- Anthropic details four new ways AI agents go off the rails
- Anthropic’s CEO signs the Pacing the Frontier petition
- METR clocks Anthropic benchmark gains at 1.9x old pace
- Sonnet 5 aligned an early Opus 4.8 checkpoint
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.