
claude-api-guard fails CI on broken Claude API calls
claude-api-guard is a GitHub Action that fails CI on Claude and OpenAI SDK calls broken by a known, dated API change. It ships with an engineering log that counts the tool’s own false positives. The project’s README on GitHub, as it stood on September 3, says the first regex-based version reported 1,576 findings across six public repos. Most of them were comments, docstrings, string literals or other vendors’ calls that happened to share a method name with Anthropic’s.
Setup is one workflow step: uses: MarkMoneyMan/Claude-api-goat@master with fail-on: HIGH. It needs no secrets, no config file and no signup. MEDIUM and LOW findings show up in the report, but only HIGH ones fail the job. Every rule ships pre-built in the repo, so a scan calls no model and needs no API key. Python is covered for both the Anthropic and OpenAI SDKs. JS/TS scanning is a first pass for the Anthropic SDK only, turned on with scan-js: "true". The license is Business Source License 1.1. Using the tool on your own project, commercially or not, is unrestricted. What it reserves is running claude-api-guard itself as a competing paid hosted service before 2030-09-01, when the code converts to MIT.
The author’s case for the tool is one line from the README: “it worked last month” is not the same as “it still works.” The rest of the log is about getting a scanner to say that without crying wolf.
From regex to syntax tree
The first version, scan.py, ran regex over whole files. It was tested against anthropic-cookbook, anthropic-sdk-python, llm, aider, OpenHands and litellm. Multi-provider code like litellm was the worst case: a pattern written for an Anthropic method also caught every other vendor’s method with the same name.
The second version, ast_scan.py, walks the Python syntax tree. It began with hand-coded checks for the nine hand-written rules. Since August 27 it also runs a generic engine, generic_scan(), which turns any rule in rules.py into a tree-level check without per-rule code, including rules an LLM extracted automatically. The engine still uses each rule’s regex, but only on the source text of a single node: a function call, an import, an assignment. It never sees the whole file. A comment or docstring is never one of those nodes, so it can’t match.
Where the noise came from
The generic engine’s first real run gave 1,720 findings in litellm alone. 1,604 came from one rule, the SDK v1.0 migration from httpx to httpx2, and 114 from a second about async .with_raw_response. Both patterns were too general. httpx is an ordinary HTTP library: litellm imports it about 40 times for its own multi-provider plumbing, and per the log it never imports the anthropic package in any of those files. .with_raw_response is a naming convention in every SDK generated by Stainless, the code generator behind both Anthropic’s and OpenAI’s Python SDKs, so litellm’s Azure calls matched it directly. The real breaking change also affects only the async client, and the pattern couldn’t tell async from sync.
The fix was one structural precondition per rule. For the first rule, the file has to actually import anthropic. For the second, the call has to sit inside an async def. The import check needed its own fix: litellm’s relative import of its own submodule named anthropic fooled the first version, so only absolute imports count now. After both fixes, litellm went from 1,720 findings to 2 and aider from 11 to 0. The 36 left in anthropic-cookbook were all real client.beta.files and client.beta.skills calls that will need updating.
anthropic-sdk-python stayed at about 1,478. The author calls it an unfair test bed, since the SDK’s own source and tests define and use the exact strings the rules look for. A real bug was hiding in that number too. A call like client = AnthropicBedrock(...) is a node inside an assignment node, so one match was reported twice. 427 of the 1,478 were exact duplicates. After a dedupe pass that keeps the more informative copy, the count is 1,051, still mostly the SDK matching its own rules.
The JS/TS scanner, built on Node and @babel/parser, went through the same cycle on vercel/ai: 1,734 findings down to 67. 1,619 of the original hits came from one rule, assistant-prefill removal, because role: "assistant" near content: describes any code that handles a chat message. The rule now counts only the last element of the messages array in an actual messages.create() call. Test-framework wrappers caused trouble too: a describe('X', () => {...}) block is one call whose span covers the whole file. The fix skips calls whose argument is a function with a body, while still walking into it, plus a 2,000-character cap on the matched text, which the log calls a safety valve rather than a precise fix.
The OpenAI rules ran into problems of their own. litellm reuses OpenAI’s openai.types Pydantic schemas as shared return types across providers. Its Vertex AI image handler imports Image from there without any OpenAI client code in the file, so type-only imports no longer count as using OpenAI. Another hit was litellm’s PromptLayer integration, which sends the string "openai.ChatCompletion.create" as logging metadata. That one was fixed narrowly, with a guard on that rule’s pattern against matches inside quotes. After these and two more fixes, OpenAI-rule findings in litellm fell from 195 to 59, each reviewed by hand. The log admits the string-literal problem is a gap in the generic engine itself and hasn’t been checked across the other 21 rules.
Rules that update themselves
Once a week, on Mondays, sync_rules.py fetches Anthropic’s release notes, keeps only the dated sections newer than the last sync, and gives that text to extract_rules.py, which asks Claude for structured rules. It drops any rule whose id already exists, appends the rest as a dated block, and opens a pull request with peter-evans/create-pull-request. A human still reviews every rule before it goes live. Adding .md to a platform.claude.com docs URL returns raw markdown, which the log says was “found by trying it, not documented anywhere.”
The first extraction, run by hand on August 27 over about eight weeks of release notes, returned 14 rules. They included all six breaking changes the author had already written by hand, among them the SDK v1.0 sampling parameters, the Opus 4.7 fast-mode removal and the Opus 4.1 retirement. They also included eight he had missed: the httpx2 migration, the compaction_control removal, AnthropicBedrock’s dropped default AWS region and the Python 3.10 floor, among others.
Each step in the pipeline found its own bug. A hardcoded max_tokens=4096 cut the JSON off mid-string. Older release notes use ordinal dates like “April 9th, 2025”, which the parser silently skipped until the suffix was stripped. The model wrote regexes with single backslashes, which isn’t valid JSON. The repair now runs before the first parse, every time, because \b is valid JSON for a backspace character but means a word boundary in regex. A fix that ran only after a crash would have shipped rules that never match. After a repo permission setting was turned on, the fourth run finished end to end in 59 seconds and opened a real PR.
OpenAI has its own parser, because openai-python’s CHANGELOG.md marks breaking versions with a ### ⚠ BREAKING CHANGES heading. Of 344 version headers in the file, only 2 carry it, and only those sections reach the model. The OpenAI side has only run in dry-run mode so far, and it calls no OpenAI API. A provider field on every rule and a per-provider config are there so a third provider means new rules and a new parser, not a rewrite. For scale, mendapi, a comparable scanner, says it tracks 84125 change records across 20 providers, fed by release feeds, changelog capture and OpenAPI spec diffing. claude-api-guard has two providers and about two dozen rules.
What auto-fix will touch
autofix.py writes real patches for 5 of about 19 rules. These are the ones where the fix is a plain deletion or a one-to-one string swap. Anything that needs a choice, like which model to migrate to or which thinking budget is right, stays detection-only. Every patched file must still pass ast.parse, or the patch is dropped and logged. That check caught a real bug on the first run. When the deleted argument was the last one and the previous argument sat on an earlier line, the engine left a stray comma on a line by itself. The check refused the patch, so the fix was skipped and no code was broken.
The scope held up on a real run. Against a full copy of anthropic-cookbook, --write made 20 edits across 9 files, all of which still parsed. A rescan showed only the 4 assistant-prefill findings the fixer was never meant to touch. One temperature= set in a **kwargs dict elsewhere in the file was left alone on purpose. A weekly template in examples/consumer-workflows/ opens a PR with the mechanical fixes.
Code it cannot see
Every rule matches the shape of an SDK call. Code that calls the API over raw HTTP looks like nothing to the scanner. litellm reimplements the Anthropic API at the HTTP level, and aider talks to Claude through litellm. Both show zero findings because there is no SDK call to inspect, not because they are safe. JS/TS support has been tested against only two repos, compared with six for Python, and the JS scanner doesn’t load the OpenAI rules yet.
The README also says the repo is private. Repos under the same GitHub account can use the action reference without extra setup. The weekly auto-fix template installs the package from that repo, so it needs a personal access token stored as a secret in the downstream repo.
The log’s clearest example of the blind spot comes from the author’s own oddsscanner project. Its live Python backend is clean, a true negative, on anthropic==0.28.0. An older Node prototype, server.js, builds a JSON body and POSTs it to api.anthropic.com/v1/messages with Node’s raw https module, with a dated snapshot, claude-sonnet-4-20250514, hardcoded. The scanner reports nothing there, and the rule format that could catch it doesn’t exist yet.
Up next
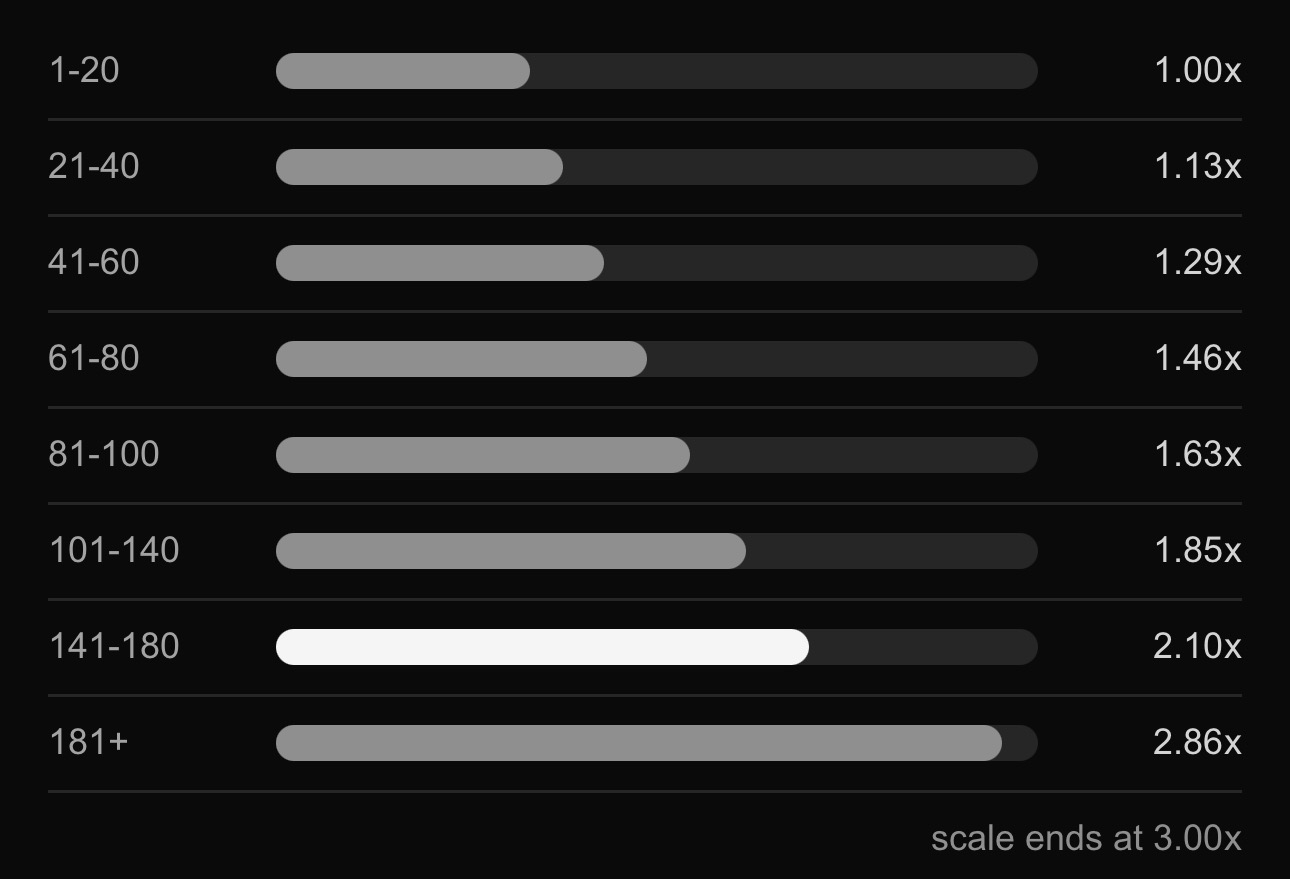
A turn at 141 costs 2.1x a turn at 20 in Claude Code
Four days after asking Claude what else was worth measuring, the author of a Show HN write-up had counted 144 sessions and found that past turn 141 a Claude Code turn costs 2.1x one from the same session’s first twenty.
Related stories
- ctok counts Claude tokens offline with no API call
- Blender addon makes Claude twice as efficient with nodes
- lcc cut one Claude Code session 49.5% without a summary
- Anthropic hands Agent Skills to the foundation behind MCP
- catnap keeps Claude Code from compacting mid-task
- Script checks whether your network breaks Claude API uploads
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.