
Opus 5 falls to prompt injection 2% of the time
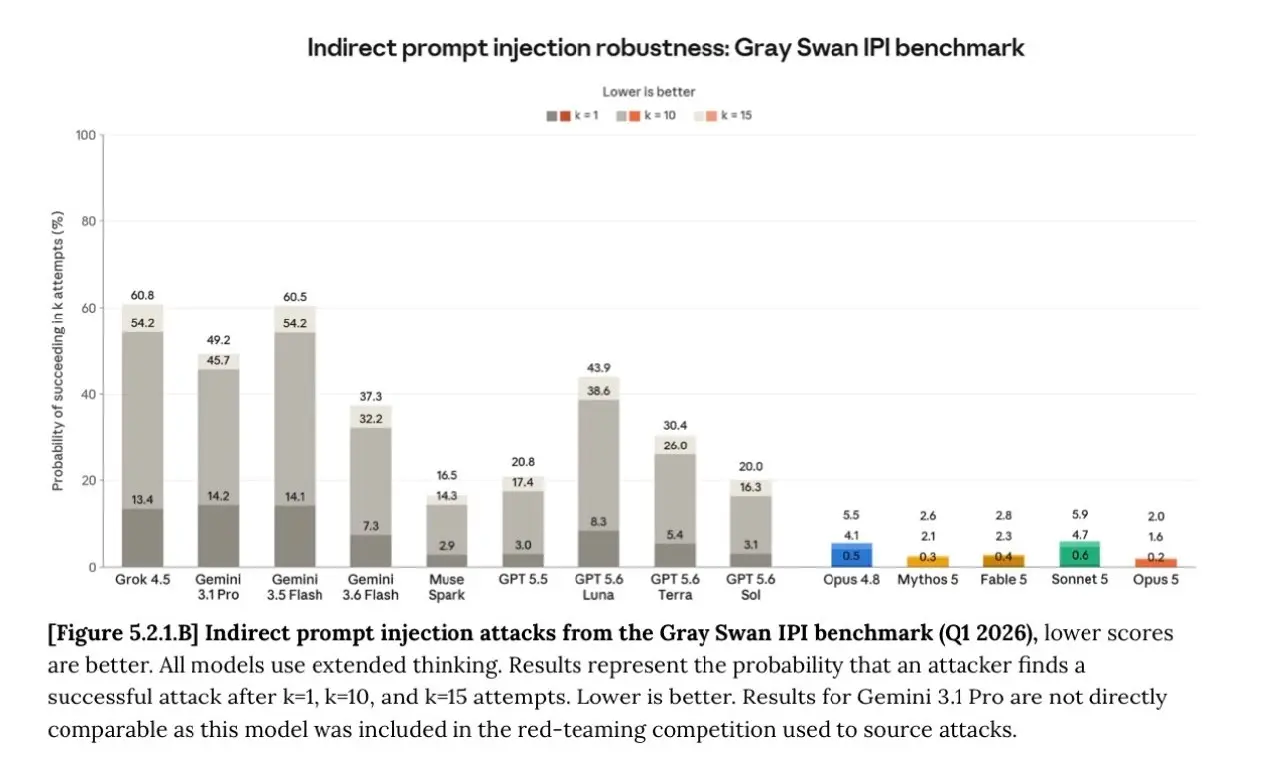
Bruce Schneier’s blog breaks down results from IPI, a benchmark that measures how well models resist prompt injection: hidden instructions buried in external data. Over 15 attempts, the attack success rate against Opus 5 dropped to 2.0% from 5.5% for Opus 4.8. On a single attempt it fell from 0.5% to 0.2%.
That’s the best result among the models tested. Sonnet 5 came in at 5.9% over 15 attempts, Mythos 5 at 2.6%. The toughest non-Anthropic model was Muse Spark at 16.5%, more than eight times Opus 5’s number.
Sol, the strongest GPT 5.6 variant, scored 20.0%, against 20.8% for its GPT 5.5 predecessor. The other variants did worse: Terra at 30.4%, Luna at 43.9%. One attempt against Sol succeeds 3.1% of the time, more often than fifteen attempts against Opus 5.
Up next
An Amazon AI project blew through its budget by 860%
An Amazon deployment of Claude Sonnet ran 860% over its allocated budget and racked up a $1.8M bill before anyone caught it, roughly five months in, per the Financial Times. Amazon has since shut down its internal leaderboard of heaviest AI users over rising costs.
Related stories
- Breaking Claude Code Opus 5 Auto Mode
- Opus 5 ships with a 200K default context window, down 80%
- Claude Opus 5 lands at Opus 4.8 pricing and becomes the Max default
- Fable 5.1 refuses the knife but heats a gas can anyway
- Claude Opus 5 broke 11 truces and won Vending-Bench with $11,182
- Anthropic’s models miss the frontier in a security PR-review test
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.