
Anthropic’s models miss the frontier in a security PR-review test
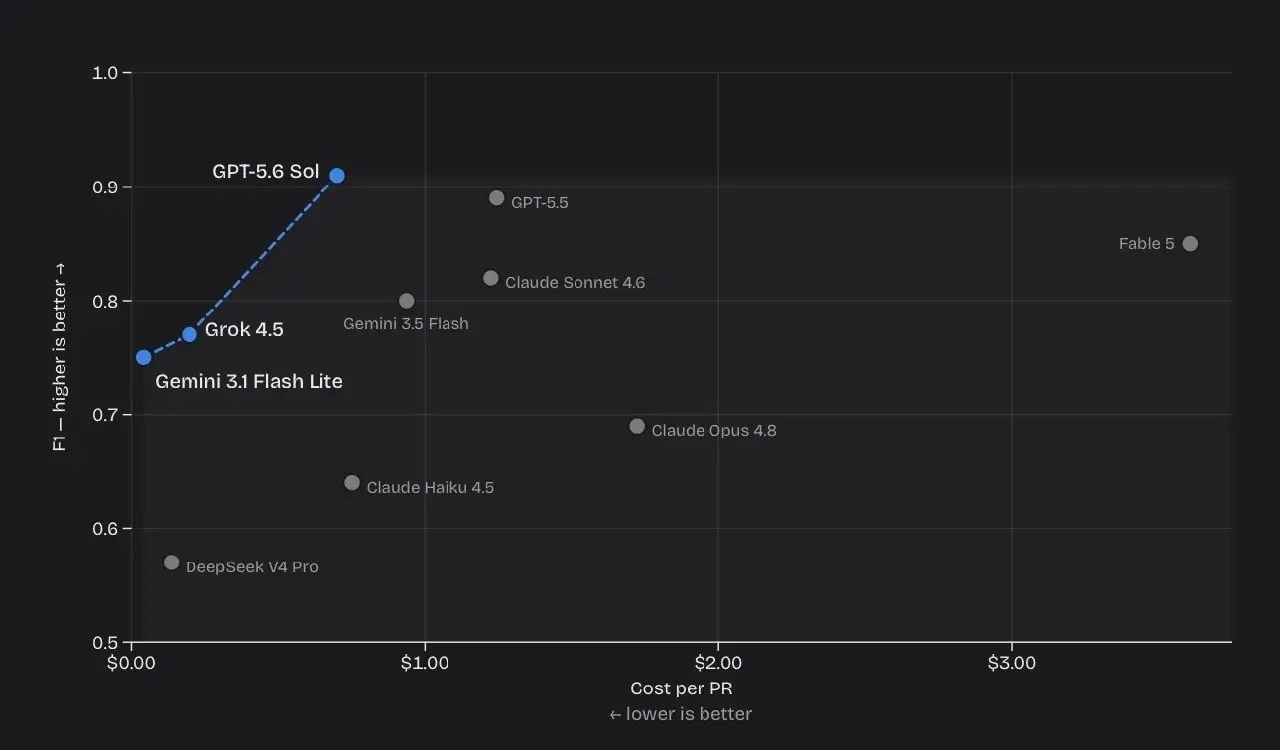
DAM Secure ran 10 models against 10 pull requests, each carrying one planted access-control bug (an IDOR with missing authorization), five runs per model, then plotted cost per PR against F1. None of Anthropic’s models landed on that cost-versus-F1 frontier.
GPT-5.6 Sol leads with an F1 of 0.91, the first 100% recall on this benchmark, at $0.70 per PR. Anthropic’s best is Claude Sonnet 4.6 (F1 0.82, roughly $1.22 per PR). A Fable 5 setup that fell back to Opus 4.8 was the priciest at about $3.61 per PR and stayed off the frontier on both axes.
The repos are synthetic and private to keep them out of training data and prevent benchmark tuning. DAM Secure got the same results on Pydantic and Claude Code harnesses. A separate measurement on full-codebase scans is promised later.
Up next
Claude Code sends 33k tokens before it even reads your prompt; OpenCode uses 7k
A blog logged traffic between the agent and Anthropic’s endpoint and found Claude Code sends around 33k tokens before it even reads the prompt, versus roughly 7k for OpenCode. They blame Claude Code’s caching strategy and heavier harness overhead.
Related stories
- Semgrep: GLM-5.2 outperforms Claude Code in IDOR detection
- GLM-5.2 (max) matches Claude Opus 4.8 on Harvey LAB-AA
- Meta shipped three benchmark charts with Muse Code. Claude Opus 5 wins all three.
- Claude reviewing Codex: 71.6% to 89.7%. Codex reviewing Claude: 91.4% down to 82.8%.
- Fable 5.1 refuses the knife but heats a gas can anyway
- Opus 5 falls to prompt injection 2% of the time
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.