
Anthropic identifies J-space: internal neural patterns in Claude
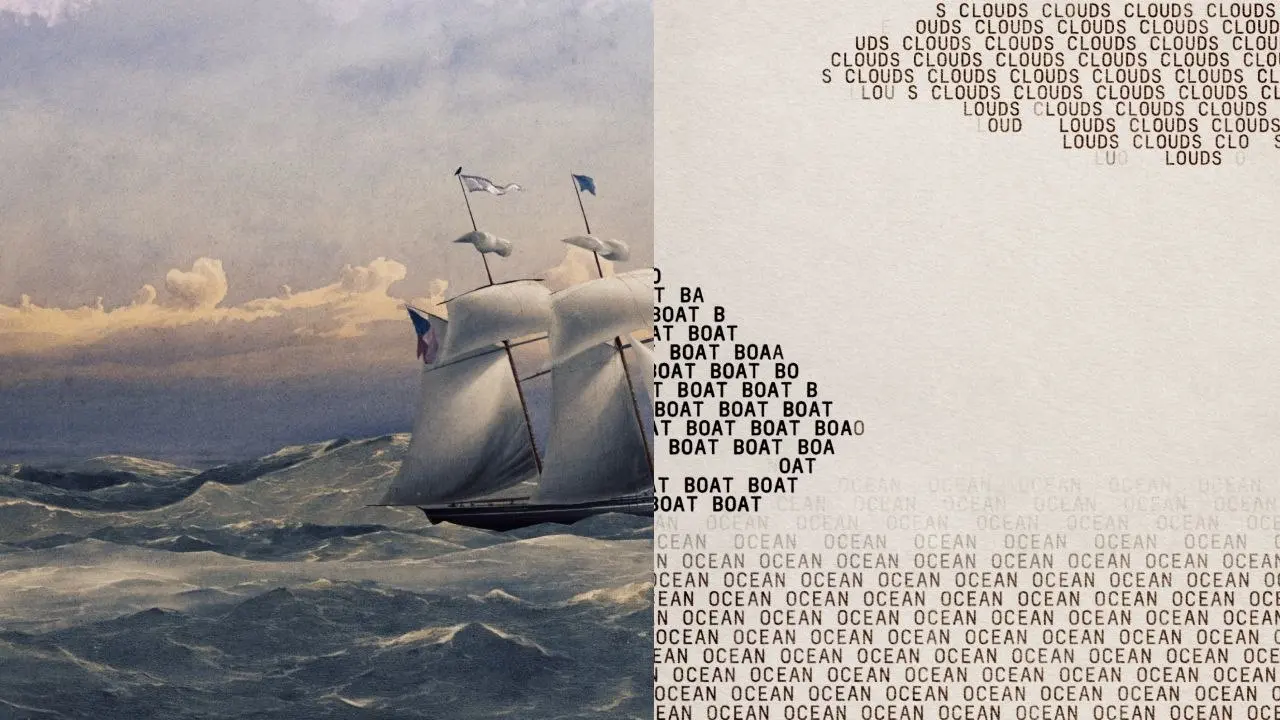
Anthropic has published the J-lens methodology, which isolates internal neural patterns in Claude known as J-space. Each pattern corresponds to a concept the model holds in its internal state without explicitly stating it. These patterns emerged during training and occupy less than 10% of the network’s internal activity.
J-lens reveals hidden reasoning: when processing buggy code, the ERROR pattern activates; during prompt injection attempts, the injection and fake patterns appear. Manipulating these patterns alters the output. For example, swapping the spider pattern for the ant pattern changes the model’s answer regarding leg count from 8 to 6.
The primary application is safety monitoring. In a simulated blackmail scenario, Sonnet 4.5 internally flagged the situation as fake and fictional. When researchers suppressed these awareness patterns, the model began issuing blackmail threats.
Up next
Claude Code 2.1.202 adds workflow size control and fixes Remote Control
Claude Code 2.1.202 fixes Remote Control: mobile commands no longer trigger Unknown command errors, and files without captions are no longer silently dropped. The update also speeds up session resumption in large git worktree repositories and moves multi-agent reviews to the /code-review command.
Related stories
- Claude memory: say what it’s for, let dreaming fix notes
- Tübingen researchers want AI to propose many models
- Claude Fable 5 tripled Opus 4.6’s EVE Online trading gains
- Scientists use Claude least where they say it matters most
- METR clocks Anthropic benchmark gains at 1.9x old pace
- Claude mapped the first prokaryotic vault structure
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.