
Claude’s PRs merge at 84%, one point under humans
Pull requests opened by Claude get merged 84% of the time, and pull requests written by people get merged 85% of the time. That comes from a study of agent contributions on GitHub posted to arXiv on July 23. OpenAI’s Codex scores lower, and Devin is far behind at 43%.
Iren Mazloomzadeh submitted the preprint on arXiv. It is built on AIDev, a dataset of agent-authored PRs taken from real GitHub repositories. The AIDev paper counts 932,791 such PRs from five agents (OpenAI Codex, Devin, GitHub Copilot, Cursor and Claude Code) across 116,211 repositories. It also includes a curated subset of 33,596 PRs from 2,807 repositories with over 100 stars. That subset adds comments, reviews, commits and linked issues.
A merge rate only records that a reviewer accepted the change. The authors’ abstract says the agents’ impact on software quality “remains insufficiently understood”. So the near-tie between Claude and human authors is still a result about acceptance, and the quality comparison is the part of the paper that could say more.
Most of the paper is about trends over time, not a single snapshot. It tracks how the merge-rate gap between agents and humans moves across development quarters. It maps which kinds of tasks agents are mostly given and how that mix changes each quarter. It then compares a set of PR characteristics that bear on software quality, also over time. The authors describe the goal as “a more nuanced understanding” of the agents’ “benefits and limitations in real-world practices”.
Up next
Slash commands are coming to Claude Code on iOS
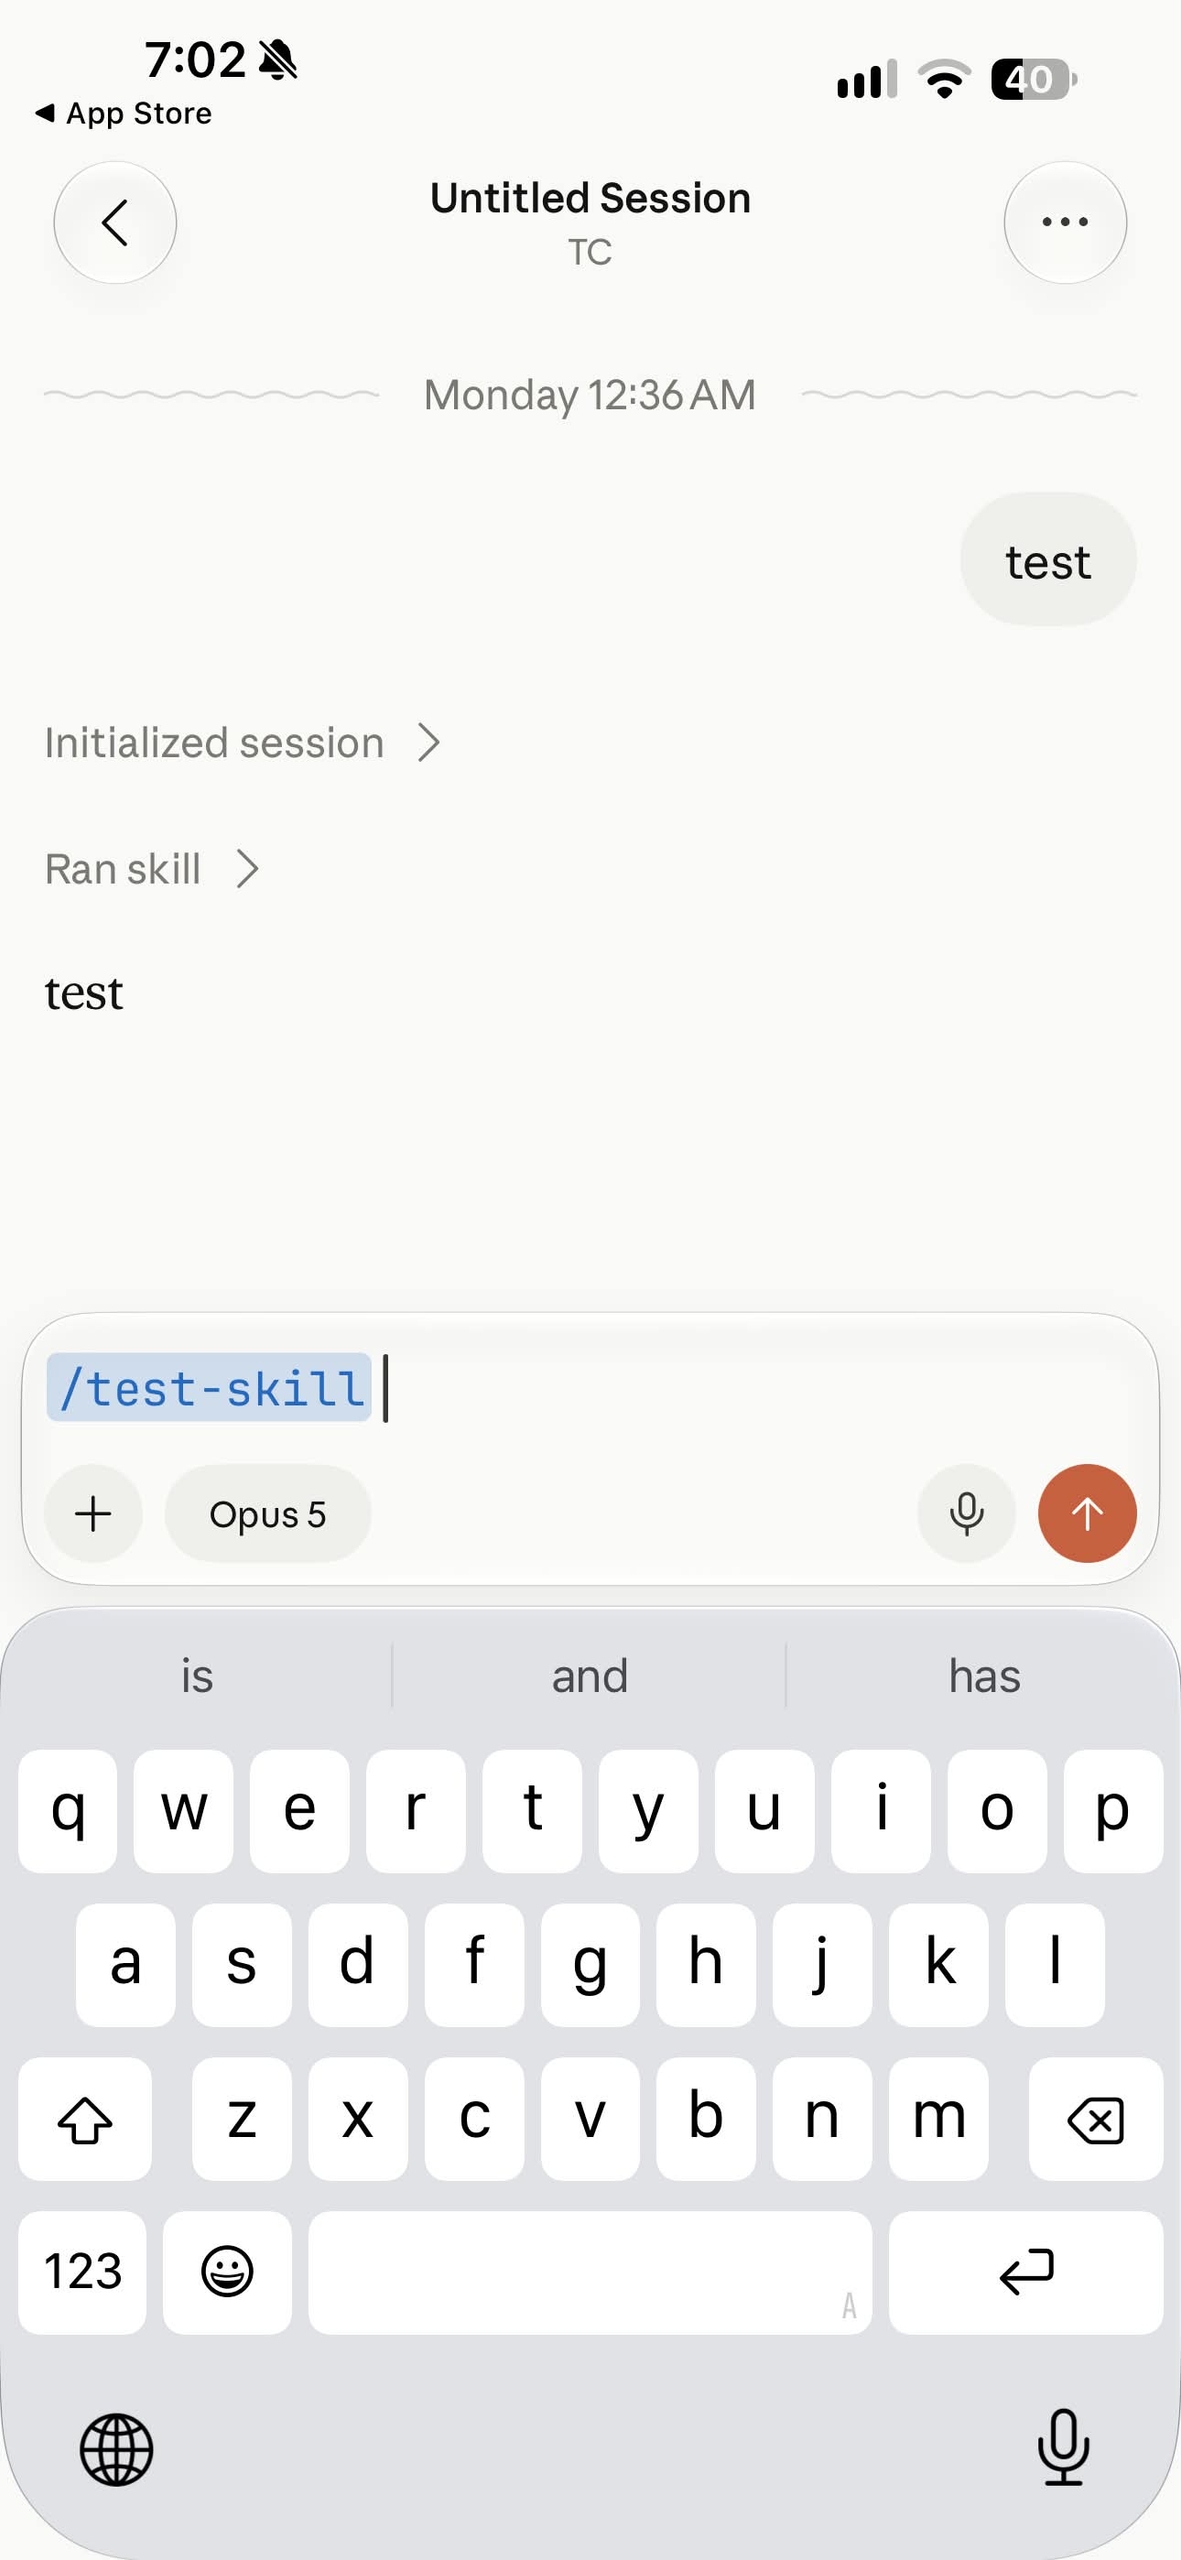
Per a Threads post, Claude Code on iOS is in line for / command support, though Anthropic hasn’t confirmed any rollout. In the mobile app today commands get typed out in full, with autocomplete listed as missing on the GitHub tracker.
Related stories
- Claude Code matches Codex on SWE-Bench Pro at twice the cost
- Claude reviewing Codex: 71.6% to 89.7%. Codex reviewing Claude: 91.4% down to 82.8%.
- Claude Code and two free models split on Next.js picks
- Claude Opus 5 tops Sierra’s agent-building test at 23.9%
- Sonnet 5 aligned an early Opus 4.8 checkpoint
- Claude Fable 5.1 cracks Urquhart’s Cyphral Distich
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.