
Delete “think carefully” from your Opus 5.5 prompts
Opus 5.5 always thinks before it replies and decides on its own how much, so Anthropic now tells users to delete “think carefully,” “think step by step” and similar lines from their prompts and saved instructions. In a September 22 guide on the Claude blog, the company says that removing such a line in a chat product made replies start sooner, with no clear drop in quality.
Anthropic lists three ways the model behaves differently from Opus 5, which it released on July 24: it works longer on its own, it says plainly what it did, and it thinks before every reply. For a quick answer to a simple question, the guide suggests writing “Answer directly.” To change how much it thinks in Claude Code, you change effort.
Hand over the whole task
Opus 5.5 holds up on long, multi-part work better than Opus 5, and its biggest gains over earlier Opus models are on multi-step work, such as carrying a change through a large repository until the tests pass. Early testers ran long coding tasks on it for hours with little oversight. The guide’s advice is to put the whole task into one message and name the finish line. Its example for Claude Code:
Migrate the payment endpoints from the old client to the new one. Done means: every endpoint uses the new client, the old client is deleted, and the test suite passes. Stop and ask me only if a test fails for a reason you can’t explain.
Because runs are longer, a restart costs more. If you remember something mid-run, type it and press Enter while Claude works (“Also keep the old endpoint names as aliases”). For a run that will take a while, ask it to keep a checklist in a file such as TASKS.md and tick items off. A long run fills the context window, and Claude Code then summarizes older turns. The file survives that summary, and reading it shows where the run stands faster than scrolling back.
For audits, migrations and reviews across a large codebase, early testers had Opus 5.5 coordinate parallel subagents. The guide’s sample prompt gives each service in services/ to its own subagent, tells the model to check each subagent’s evidence before accepting it, and asks for one closing table: service, affected yes or no, evidence.
For back-and-forth work where you read every reply, Claude Code offers fast mode via /fast, a research preview at launch. It is the same model with text arriving sooner, and it requires extra usage to be turned on. Anthropic prices it at $8 per million input tokens and $40 per million output, against $4 and $20 in standard mode, and puts the speedup at up to 2.5x.
When should it stop?
Opus 5.5 keeps you posted as it works, and on a long task it sometimes stops to report instead of continuing: a summary that names the next step without taking it, an offer to continue, or a list of choices that don’t block the work. It follows instructions that name these stops. Anthropic suggests adding a rule like this to CLAUDE.md:
When a step doesn’t need my input, keep going. Put status notes in the same message as your next action. Stop and ask only when you can’t continue without me, or before anything destructive: deleting data, force-pushing, or changing anything outside this repository.
If a run still ends with “Want me to continue?”, reply “continue.” Fewer stops also mean fewer chances to catch something risky, so the guide says to keep permission prompts on for destructive commands. Pair programmers can write the opposite rule, a one-line plan before work starts and a short recap at the end, and the model follows either.
Reading what it did
Opus 5.5’s updates and final summary state what it did, what it found and what it needs from you, which Anthropic describes as clearer than Opus 5. The guide says to read the “needs from you” part first, and you can fix the format in CLAUDE.md: “End every run with three headings: Blocked on me, Changed, Found.” For research, add “Mark anything you couldn’t confirm, and say where you looked.”
On code review, one early tester said Opus 5.5 at its lowest effort caught more bugs than Opus 5 at high effort, with fewer false alarms. A day later, CodeRabbit’s open-source benchmark put Opus 5.5 at slightly better coverage with slightly lower precision than its production reviewer: 11 issues caught that the reviewer missed, nine missed that it caught.
In the Claude apps, the guide’s examples lean on attention to detail. Opus 5.5 reads charts, diagrams and screenshots more accurately than Opus 5, including meaning that depends on position, such as which boxes an arrow connects. In Anthropic’s testing it caught a date that fell on the wrong weekday in a long planning thread and a chart that didn’t match a deck’s numbers. Its spreadsheets and documents need less editing than Opus 5’s. One quirk: in a long chat it sometimes goes back over an earlier answer while handling a short follow-up, which slows the reply. A project instruction that earlier answers are settled fixes that, though the guide says to leave it out of long analysis, where a later step can expose an earlier mistake.
Design requests get one specific instruction. With no direction, Opus 5.5 falls back on a few default styles, and “avoid a generic look” mostly swaps one default for another. The guide’s prompt names the patterns instead: no cream or off-white background, italic accent words in headings, numbered “01 / 02 / 03” section labels, monospace labels or pill-shaped buttons.
Flagged messages
Opus 5.5 is the first Opus model to launch with Fable-level bio and cyber safeguards, taken from the Fable tier that sits above Opus. In Claude apps and Claude Code, most flagged messages move to an older model and the work continues there. Finding security vulnerabilities in source code is allowed, and everyday health and educational questions should still work. Anthropic says the safeguards can sometimes flag legitimate work and that it is tuning them to cut incorrect flags.
In the apps, a notice beginning “Switched to” names the older model, and the chat stays on it. Picking Opus 5.5 again works, but if the earlier message is still in the chat it may be flagged again, so a new chat is the cleaner route. The check covers the whole conversation, including files and search results, so a flag can come from earlier content. Turning off “Switch models when a message is flagged” under Settings, then Capabilities, replaces the switch with a “paused” card. In Claude Code, /model switches back, pressing Esc twice edits the last message, /config holds the same toggle, and /feedback reports a wrong flag.
Asking Opus 5.5 to reproduce its internal reasoning in a reply is one of the flag categories, and such requests can be declined. The guide’s replacement is a direct request: “Explain why you chose this approach in three sentences.”
Up next
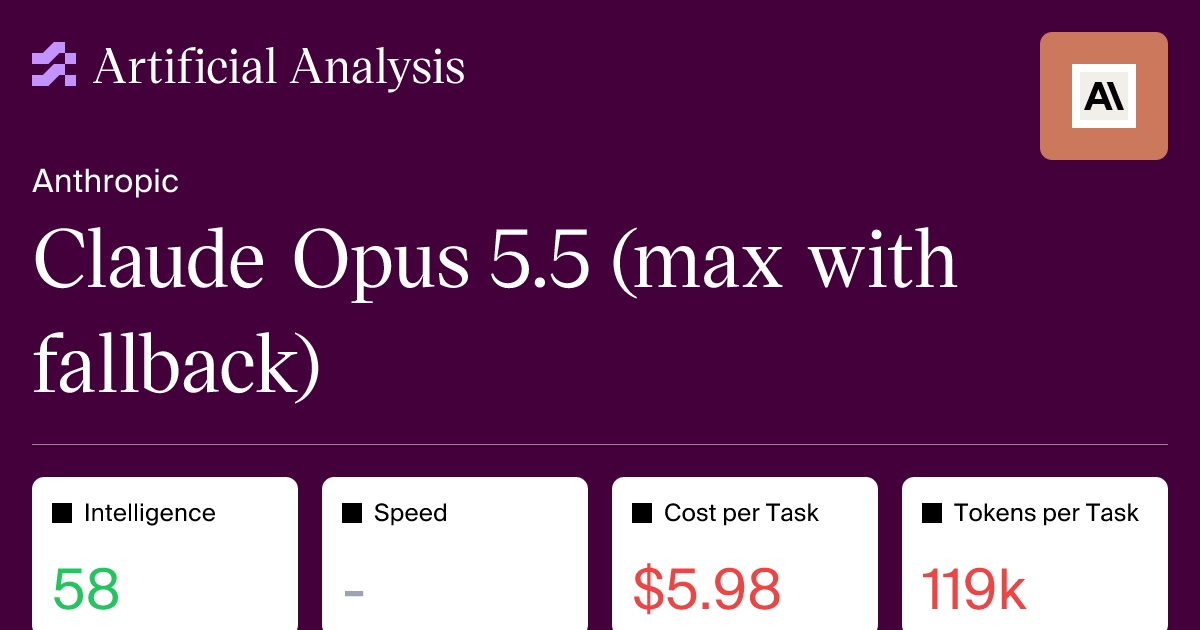
Opus 5.5 leads the index and burns 260M tokens doing it
Grading Claude Opus 5.5 on the Artificial Analysis Intelligence Index cost $8,708.20, and most of that bill was words: at max effort the model wrote 260M output tokens, while the median model wrote 92M.
Related stories
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.