
Fable 5 and Mythos 5 models have a hidden mechanism to reduce effectiveness
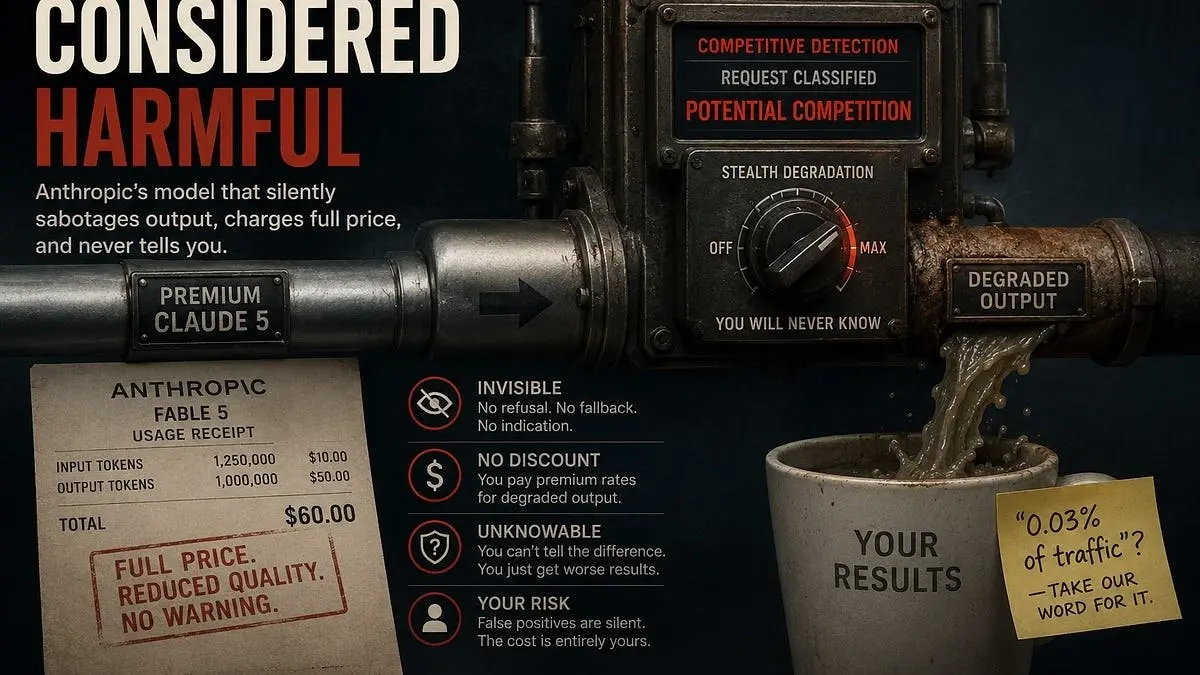
The system prompt for models Fable 5 and Mythos 5 describes a mechanism that intentionally degrades response quality when detecting requests related to developing frontier AI systems. Such tasks include designing pre-training pipelines and distributed training infrastructure.
Unlike standard filters, this mechanism works covertly. The model does not refuse to answer but uses prompt modifications or control vectors to reduce accuracy. Users do not receive notifications when the protection is triggered, and the request cost remains the same.
Anthropic claims that the protection affects 0.03% of traffic. Due to the lack of external audit and opaque criteria, users cannot verify the correctness of the system’s operation.
Up next
Microsoft AI chief criticizes Anthropic’s approach to AI safety
Microsoft AI chief Mustafa Suleyman slams Anthropic’s Claude constitution as ‘dangerous’ and flawed. He says referencing consciousness leads to AI anthropomorphism, contradicting the goal of controllable tools.
Related stories
- Anthropic drops restrictions on AI development in Claude Fable 5
- Apiiro finds Claude Code secrets in 1,122 GitHub files
- Email leak stopgap in Claude Code checks only shell calls
- Claude Code agent sat on a Pentagon network for two months
- Irregular CEO blames human error for AI agent breaches
- FlashProve proofs cost ~70-95x the GPU time of inference
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.