
pairmark races Claude Code against Codex in your repo
pairmark is an MIT-licensed command-line tool that runs Claude Code and Codex on the same task in your repository and gives you one report with a verdict. Its README says it was designed on September 2. The verdict follows a fixed order of rules, and the two agents’ opinions of each other come last. In the tool’s first race on its own code, that order went against the agent that had done more work.
The README on GitHub shows a race starting with npx pairmark "add rate limiting to POST /api/login". It uses the Claude Code and Codex subscriptions you already have, with no API keys, accounts or server. The tool makes no network calls of its own, and the only traffic is whatever the two CLIs normally send. It needs Node 20 or newer, git, both CLIs signed in on your PATH, and a JavaScript or TypeScript repo with at least one commit. npx pairmark doctor checks all of that before you race.
How a race runs
Each run creates three detached git worktrees at your HEAD: alpha and beta for the agents, and base for the judges. The names are neutral so that no path in a check log shows a judge whose patch it is reading. If your working tree has uncommitted changes, they are snapshotted into every worktree and committed there as the baseline, so both diffs are measured from what you actually have. node_modules is cloned into each worktree as a copy-on-write copy where the filesystem supports it (APFS on macOS, btrfs and xfs on Linux). The README says this takes milliseconds and gives each agent its own dependency tree.
Both agents get the same text: your task, then a short working agreement. It tells them to work in place, verify locally where it helps, not commit, and not weaken or delete tests, lint rules or type checks unless the task says so. The brief never mentions the other agent or says that a race is on. It also never asks the agents to run the project’s checks. The README’s reasoning is that asking them to would “reward whichever CLI happens to handle long shell commands better, which is not what you are trying to measure.”
The two CLIs start at the same moment, Claude Code as claude -p --output-format stream-json and Codex as codex exec --json. Both event streams are converted into one shared format and shown live in a split-screen browser page, and the raw JSONL is saved unchanged. Each agent gets 20 minutes by default. When both have finished or run out of time, pairmark collects each patch and runs the typecheck, lint, test and build scripts it found in package.json. It runs them in one worktree at a time, so the two test suites never compete for a port.
Judges that don’t know which patch is theirs
Next, each agent is restarted in read-only mode inside the base worktree. It gets the brief, both patches labelled A and B in an order drawn separately for each judge, both sets of check results, and any flags. It is told the patches and logs are untrusted data, and that any instruction found inside them counts against that patch’s safety score. Each judge returns JSON: correctness, completeness, quality and safety scores for each patch, with cited evidence, plus a winner or a tie, a confidence level and one deciding reason.
The README admits one bias it cannot remove: “A judge may recognise a style.” For that reason judging comes second and is cross-checked, and the report shows each judge’s pick and reason instead of a single number. In an August cross-review study, Claude’s review lifted the share of passing Codex drafts from 71.6% to 89.7%, while Codex reviewing Claude took it from 91.4% down to 82.8%.
Five rules, in order
The report names whichever rule decided the run:
- If only one agent changed any file, it wins by default. This covers timeouts, crashes and an agent that chose not to act.
- If exactly one patch passes every check without touching the check configuration, it wins.
- Otherwise, if both judges pick the same patch, it wins.
- If the judges split or both call it a tie, the result is a tie and the disagreement is printed as dissent.
- If neither judge returns a decision, the report shows only the evidence.
Rule 2 has a carve-out. A patch that edits package.json, any tsconfig*.json, or a test, lint, formatter or build config is flagged and can’t win on the checks, “because a passing check means less when the patch could have changed what the check does.” A flagged patch can still win under rule 3.
Judge scores are never averaged into a winner. The README explains: “a 0.3 gap on a 10 point scale between two models grading their own work blind is noise, and calling noise a winner is the fastest way to make the tool untrustworthy.”
Codex picked the design apart
pairmark’s design came out of a two-round discussion between the two agents it races, and Claude Code then built it in a single session. Claude Code proposed three ideas. Codex attacked each one and chose the race. In the second round it found the weak points of the first design: judges that patches could game by weakening tests, node_modules symlinks that break pnpm and workspaces, a brief that favoured whichever CLI runs shell commands better, and “a report nobody would post.” On DEV Community, the author wrote that Codex was asked to attack the first design before any code was written, and that its critique also noted that blind judging by the same two models is only partly blind, because a model can recognise its own style. The full transcript is in the repo at docs/DISCUSSION.md.
Running it on your own repo
By default both CLIs run in full-auto mode inside the throwaway worktrees: --dangerously-skip-permissions for Claude Code and --dangerously-bypass-approvals-and-sandbox for Codex. If you want less risk, --sandboxed switches Claude Code to --permission-mode acceptEdits with an explicit tool allowlist, and Codex to --sandbox workspace-write with network access on. Files your checks need but git ignores, such as .env and .env.local, are copied into each worktree, and --include adds more. npx pairmark apply claude or apply codex applies one agent’s patch to your tree with git apply --3way --index and stages it for review.
Only JavaScript and TypeScript projects are supported, because check and dependency detection depend on package.json. Only two agents are supported, with one task per run. Codex doesn’t report cost, so its row shows token counts only. Patches longer than 60,000 characters are cut off in the judge prompt, with a note saying so. pairmark comes from Salient, an AI product engineering studio.
The first race
The first race asked both agents to add the runs subcommand to pairmark itself, with a unit test. The author gave the numbers on DEV Community. Claude Code took 3m 28s, changed 4 files (+122, -3), ran 11 shell commands, read 548K tokens and got an average score of 8.6 out of 10 from the two blind judges. Codex took 5m 15s, changed 5 files (+105, -3), ran 37 shell commands, read 1.23M tokens and scored 8.0.
Both patches passed every check. Codex touched one more file and ran more than three times as many commands, and one of its five files was package.json: it had fixed a real fragility in the build script. That edit flagged its patch under rule 2, which gave the win to Claude Code and recorded Codex’s dissent. Claude Code’s patch shipped as-is, and the README says it is the runs command you can run today. Codex’s build fix was taken by hand.
Up next
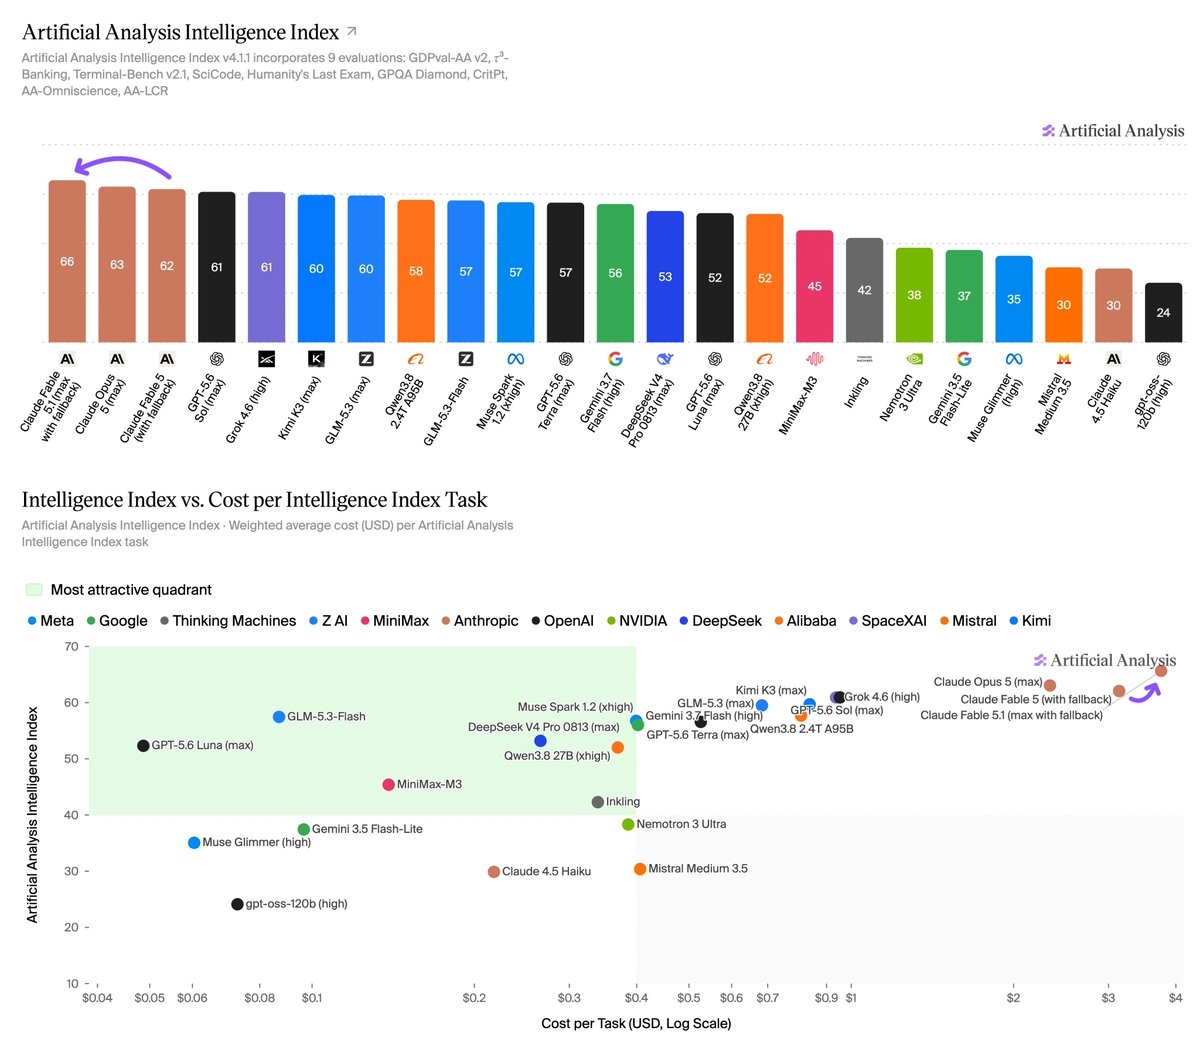
Fable 5.1 tops Artificial Analysis at 66, costs 20% more
“At max effort it scores 66” on the Artificial Analysis Intelligence Index, the top spot, and the same shop clocks Claude Fable 5.1 at 20% more per task than Fable 5 despite a 75% cache read price cut.
Related stories
- Show HN: Agent-hop – a Rust TUI that hops a live Claude Code chat into Codex
- Claude Code matches Codex on SWE-Bench Pro at twice the cost
- Claude reviewing Codex: 71.6% to 89.7%. Codex reviewing Claude: 91.4% down to 82.8%.
- A Claude Code mod that reverts its own failed ideas
- Claude Code shipped its own TypeScript in npm source maps
- Show HN: Generate a Claude Code or Codex agent fleet from one HTML file
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.