
Sonnet 5 keeps telling testers it’s GPT-4
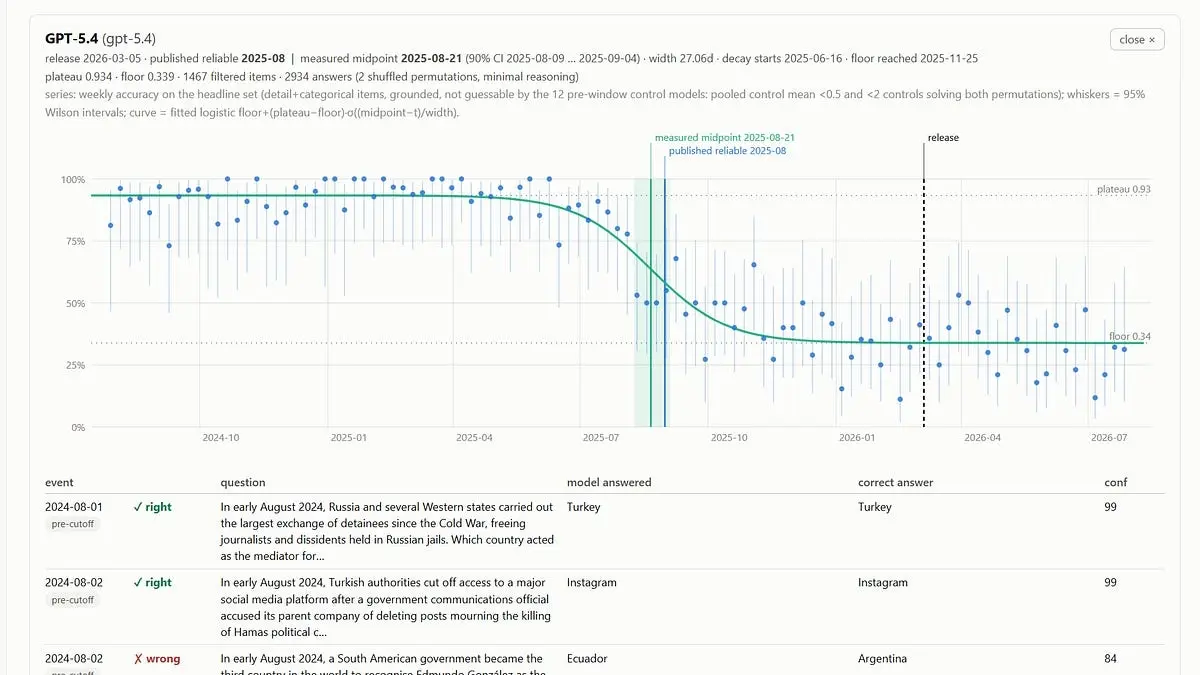
An independent researcher probed the pretraining cutoffs of Claude and GPT models through the official APIs, using an 8-option quiz built from daily Wikipedia facts to find the point where a model loses the signal from its training data.
His read: Anthropic’s models from Opus 4.7 onward came out of a single pretraining run with a cutoff around the end of December 2025. Opus 5 is the odd one out. Its stated knowledge cutoff is in May, but on the measurements it knows no more than models cut off in January.
The self-identification probes are stranger. Across 50 queries per model, Sonnet 5 regularly called itself GPT-4, while OpenAI’s models never once claimed to be another lab’s model. Claude models reproduced the measured quirks of OpenAI models 68% of the time; OpenAI models did the same for Claude in 8% of cases. The researcher’s guess is that old ChatGPT conversations ended up in Claude’s training mix.
Up next
Claude pushed the zeta-zero lower bound from 41.6% to 67.2%
An unreleased research version of Claude pushed the lower bound on the share of Riemann zeta zeros lying on the critical line from 41.6% to 67.2%. It took two Claude Code sessions and 31M output tokens; the Riemann hypothesis itself is still unproven.
Related stories
- Claude’s cipher project writes off the gold bar codes
- Claude’s raw thinking never leaves the server
- Claude stamps 2026 onto “best X” search queries
- Claude memory: say what it’s for, let dreaming fix notes
- Tübingen researchers want AI to propose many models
- Claude Fable 5 tripled Opus 4.6’s EVE Online trading gains
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.