
A four-model Claude ensemble scored 78% on Terminal-Bench 2.1, at double the cost of first place
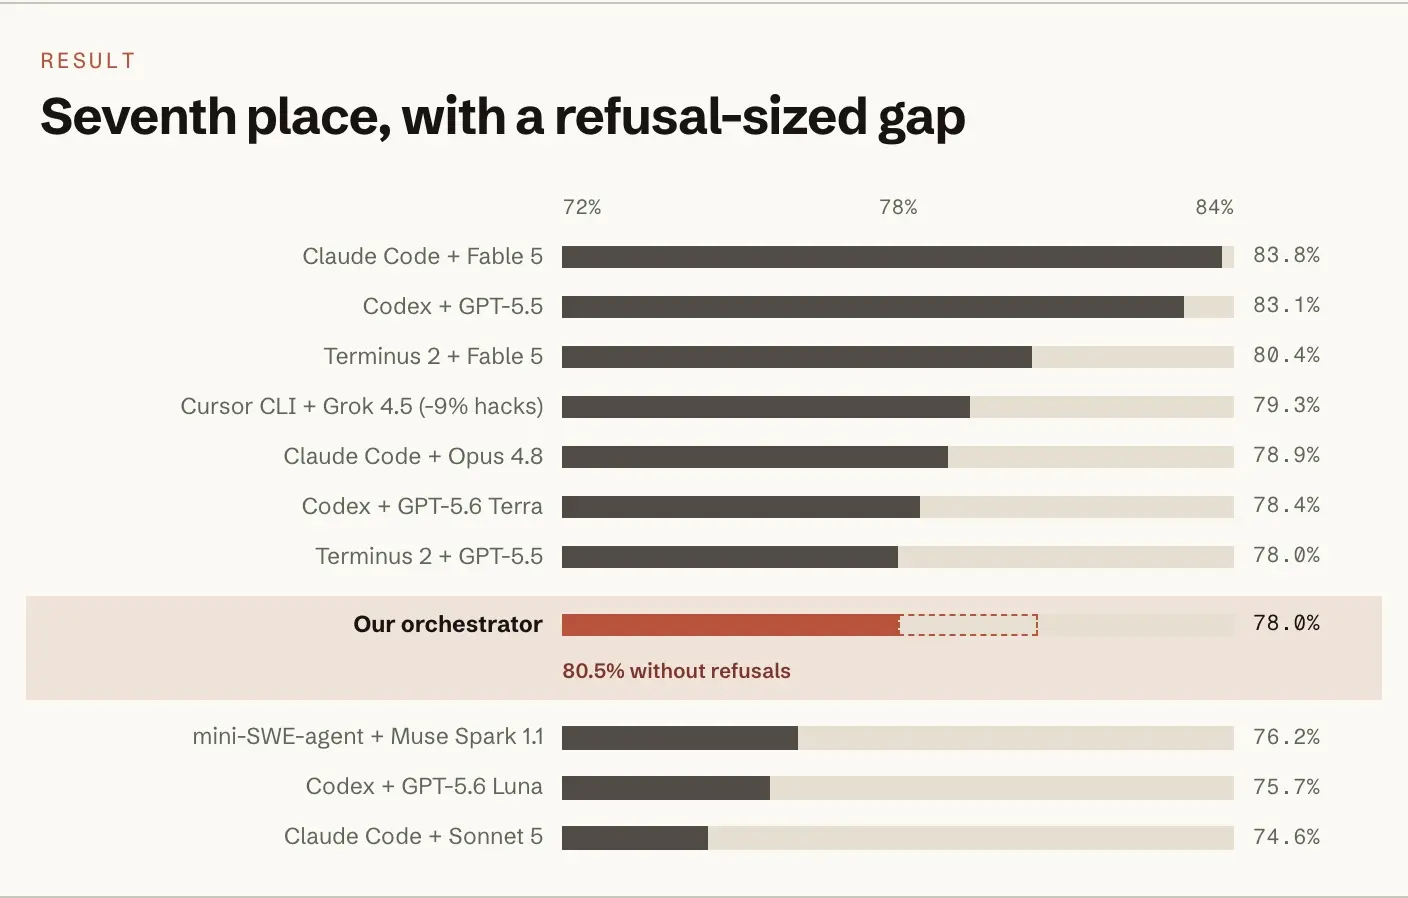
The run placed seventh with a bill of $1,178, roughly twice what the top entry spent. The division of labor: Fable 5 plans and delegates, Haiku 4.5 scouts, Opus 5 edits code, Sonnet 5 verifies the work.
Three security tasks went unsolved because the executor refused to run them: zero out of 14 delegated attempts. In a control run without delegation, Opus 5 solved the same tasks six times out of six. Credit those three and the ensemble lands at 80.5% and third place.
Verification did most of the heavy lifting. Tasks that went through the verifier passed 91% of the time, versus 43% without the check. Opus 5 in the executor role accounted for 58% of total spend, or $689.
First place on the board still belongs to Claude Code with Fable 5 at 83.8%.
Up next
Subagent coordination in Claude Code costs zero tokens
In Claude Code’s dynamic workflows, Claude writes a JS orchestration script that spawns subagents, and intermediate results stay out of the model’s context, so coordination costs zero tokens. 0xCodez’s guide: split any ‘and then’ where the next step doesn’t read the prior output.
Related stories
- Claude Code and two free models split on Next.js picks
- Claude Code matches Codex on SWE-Bench Pro at twice the cost
- Auditing one Claude session: 7.5M tokens, 4,038 tool calls
- Claude Code adopters merged 24% more PRs, study finds
- Claude Code sends 33k tokens before it even reads your prompt; OpenCode uses 7k
- Cloud sessions in Claude Code now set up your repo
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.