
Anthropic’s 225 bug finds, one attack in the wild
As of September 21, 225 vulnerabilities had been credited to the Anthropic team, to Project Glasswing, or to both, and attackers are confirmed to be exploiting exactly one of them: CVE-2026-26980, a critical SQL injection in the Ghost publishing platform. VulnCheck researcher Patrick Garrity keeps the count and puts the exploited share below 0.5 percent, The Register reported.
Garrity started tracking soon after Anthropic announced Glasswing on April 7. The program gives vetted partners access to Claude Mythos Preview for defensive work: finding and fixing flaws in their own products and in the open-source code those products depend on. Anthropic kept the model out of public release, saying its skill at finding and exploiting bugs surpasses all but the most skilled humans.
How the tracker counts
The tracker lists every CVE credited to the Anthropic team and/or Project Glasswing. It then checks each one against VulnCheck’s index of known exploited vulnerabilities, which Garrity says he does “to get a better read on the real Glasswing ‘danger factor.’”
“There’s a big difference between finding vulnerabilities and whether they’re actually useful to and will be used by threat actors,” he told The Register.
Garrity also gives a baseline. Historically, he said, somewhere between just under 1 percent and 2 percent of vulnerabilities get weaponized and used in the wild. His reading of the Glasswing list is that it behaves like any other batch. “The main thing this data highlights is that what Anthropic is discovering and disclosing is fairly limited in impact, and from what we can tell, isn’t resulting in different outcomes from a threat perspective than a random selection of other vulnerabilities would,” he said.
That sits awkwardly next to Anthropic’s own case for holding Mythos Preview back. The company said Glasswing would give defenders a head start, a window to find and fix vulnerabilities before models with similar capabilities became generally available or reached malicious actors. Five months of disclosures have so far produced only one bug attackers are confirmed to be using.
“A lot of the hysteria we’re seeing assumes that every vulnerability or bug is likely to be used by threat actors,” Garrity said. “But the reality is that only a small fraction ever get used in exploitation campaigns.”
Where the gap is
Garrity does not dispute that AI finds bugs. Microsoft, Apple and Palo Alto Networks have all shipped very large patch drops recently, and open-source projects have been flooded with reports too. Nor does he think the skill belongs to Anthropic alone: it is not “a capability unique to one model or harness,” he said, the harness being the tooling wrapped around a model. Curl is a case in point. Six curl CVEs, all rated Low, came from reports by the startup AISLE after maintainer Daniel Stenberg posted on August 24 that Mythos could not find any more bugs in the codebase.
Fixing is a different matter, and two recent studies put numbers on it.
1Password’s research team generated and analyzed 6,080 patches from two frontier models, OpenAI’s ChatGPT-5.5 and Anthropic’s Opus 4.8. Just 26 percent of the fixes fully resolved the vulnerability. About 54 percent failed to resolve it, introduced a new vulnerability, or did both. Separately, Veracode tested more than 100 models on 80 coding tasks and found an average security pass rate of 56 percent for AI-generated code. The Register’s conclusion is that developing and applying security fixes still requires humans, and Garrity draws the same line.
“The bar for vulnerability discovery is much lower with AI, but the real gap lies downstream in coordination, triage, remediation, and patch deployment, which is still largely people-intensive work, as Anthropic itself has acknowledged,” he said. “It appears they might not have realized this until after they launched the project.”
Up next
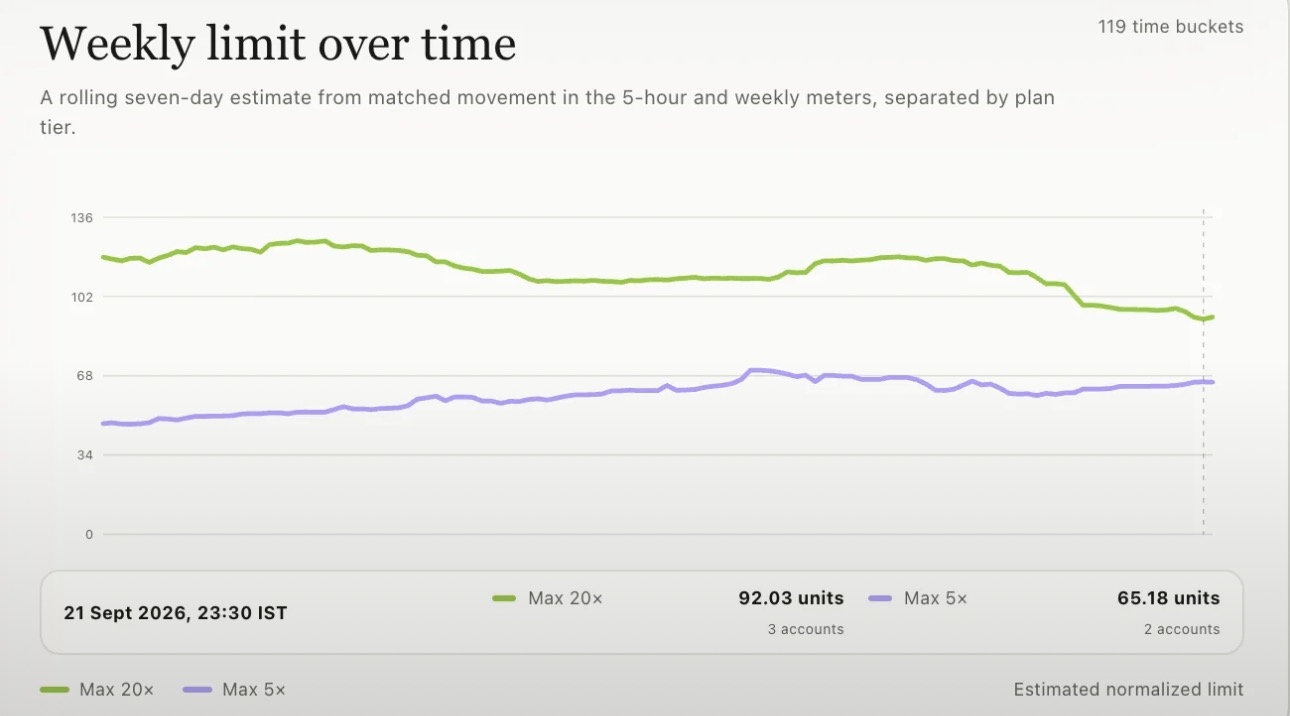
Max20x buys only 1.5x of Max5x, says one team’s tally
A team pools its Claude Code subscriptions and routes GitHub reviews to whichever account still has capacity. By their own normalized tally, the Max 20x edge over Max 5x has shrunk from about 2.5x to about 1.5x.
Related stories
- Attackers hit a Mythos-found HFS bug within a day
- FlashProve proofs cost ~70-95x the GPU time of inference
- A Claude sandbox memory dump yielded a valid Google token
- Claude model wrote a no-login Linux root exploit
- Claude grades its own chats for misuse, catching 78%
- Unreleased Claude model built a one-click Chrome exploit
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.