
By the end of a long session, strict solutions drop to 0.5%
Model accuracy falls apart long before the context window fills up. On the NoLiMa benchmark, 11 of 13 models with a claimed context of 128k or more scored below half their short-prompt baseline once they hit 32k tokens. GPT-4o managed 69.7% against a 99.3% baseline.
SlopCodeBench (arXiv 2603.24755, March 2026) put 11 models to work revising their own code across 93 checkpoints. Not one agent solved a task end to end. The best single checkpoint score was 17.2%, and by the final checkpoint strict solutions had fallen to 0.5% while cost climbed 2.9x. Structural degradation showed up in 80% of runs.
The author’s advice: run /clear at task boundaries and fire /compact early, while there’s still headroom. In Claude Code 2.1.220, /context prints the Autocompact buffer on its own line, the space held back for the future summary.
Up next
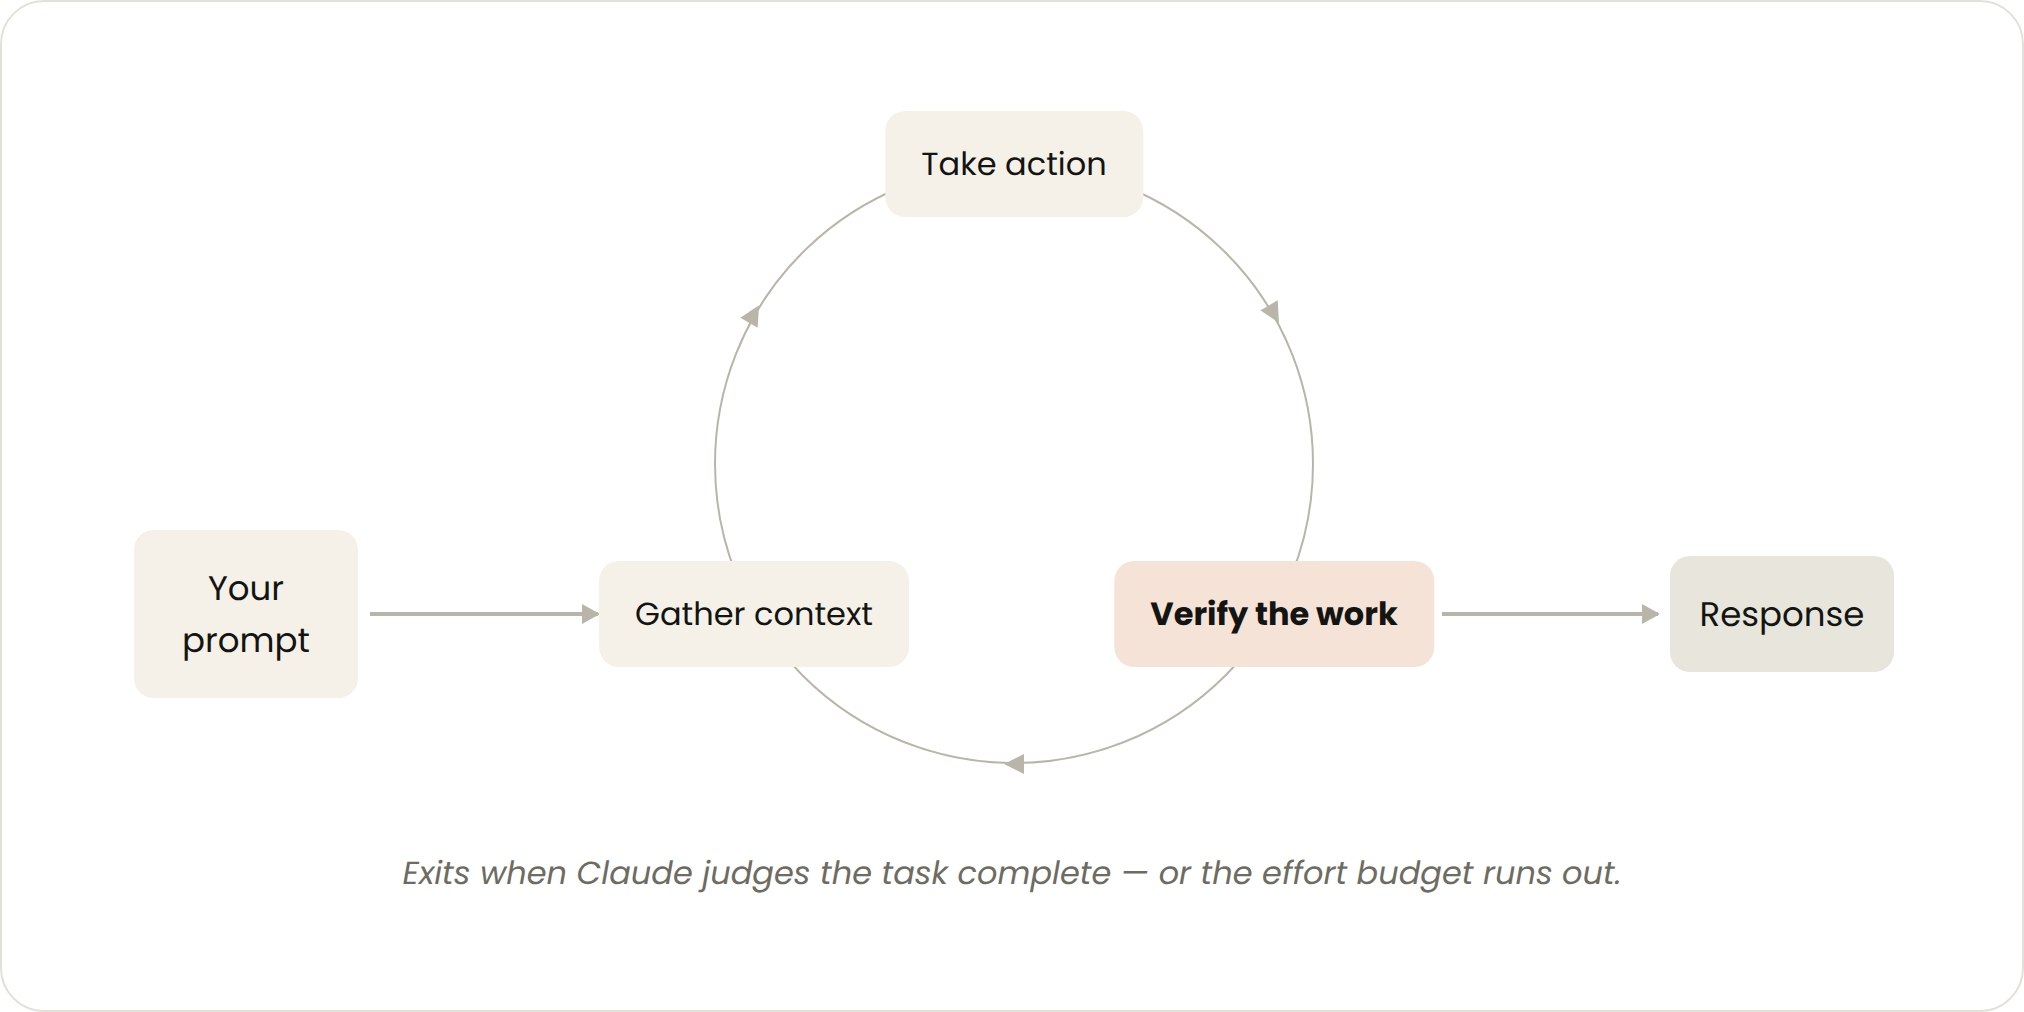
Claude Code has four kinds of agent loops: /goal, /loop, /schedule
“Get the homepage Lighthouse score to 90 or above, stop after 5 attempts”: that’s the kind of criterion /goal sets in Claude Code. Every time Claude tries to stop, an evaluator model checks the condition and sends it back to work.
Related stories
- Why output tokens in Claude Code cost about 5x what input does
- Claude Code sends 33k tokens before it even reads your prompt; OpenCode uses 7k
- ponytail’s token savings: 10.3% off the bill, not the promised 20%
- Apiiro finds Claude Code secrets in 1,122 GitHub files
- No multiplayer in Claude Code Projects yet, Anthropic says
- Email leak stopgap in Claude Code checks only shell calls
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.