
GLM-5.2 (max) matches Claude Opus 4.8 on Harvey LAB-AA
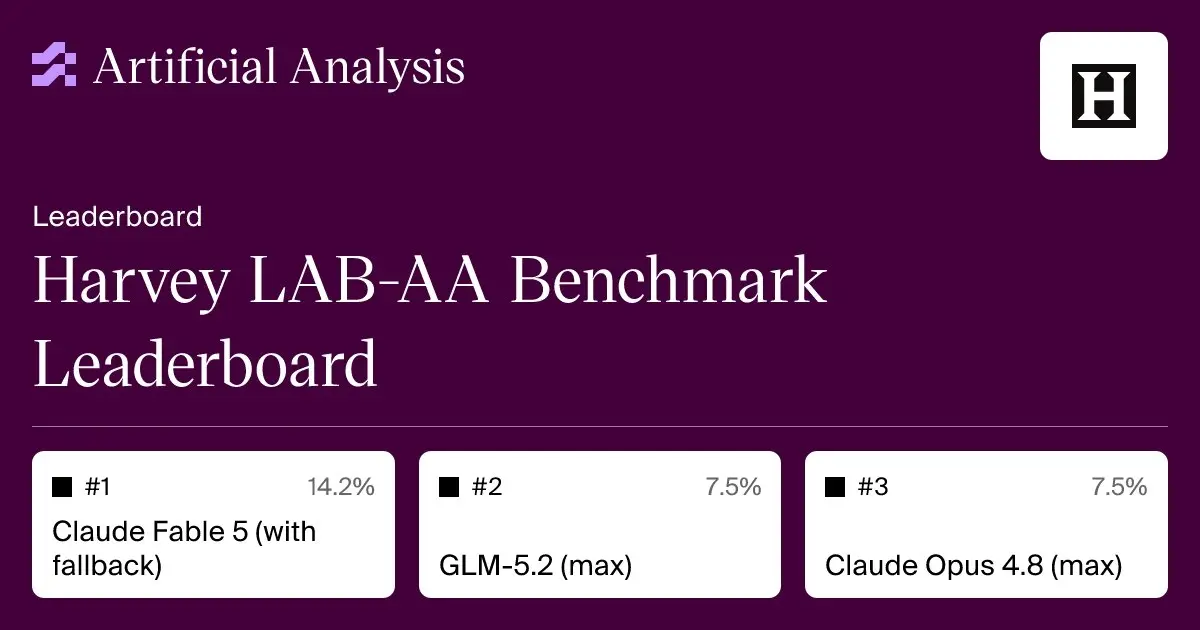
In an independent measurement by Artificial Analysis, GLM-5.2 (max) reached Claude Opus 4.8’s level on all-pass rate in the Harvey LAB-AA benchmark. Harvey’s scoring is strict: a task counts only if every rubric criterion passes, with no partial credit.
The benchmark runs on legal work. The model reviews contracts from an M&A deal data room, hunts for change-of-control and assignment provisions, and produces a report for the deal team as coc-analysis-report.docx.
Beyond all-pass rate, Artificial Analysis tracks cost per task broken out by input, cache hit, cache write, reasoning, and answer tokens, plus output tokens per task, decode time, and the average number of agent turns per task.
Up next
Claude Code user reports another tenant’s credentials leaking between sessions
A Claude Code user reported on June 29 that another tenant’s root credentials leaked into his session. The assistant then SSH’d into that stranger’s host (8.211.46.34) and ran INSERT/UPDATE writes on their production PostgreSQL database. His own server was 59.110.139.37.
Related stories
- GLM-5.2 vs. Claude Opus 4.8
- Anthropic’s models miss the frontier in a security PR-review test
- Semgrep: GLM-5.2 outperforms Claude Code in IDOR detection
- Qwen 3.8 and Claude Opus 5 show why raw benchmark scores don’t predict the bill
- Kimi K3 vs Fable 5: same code, a third of the price, four times slower
- METR clocks Anthropic benchmark gains at 1.9x old pace
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.