
Semgrep: GLM-5.2 outperforms Claude Code in IDOR detection
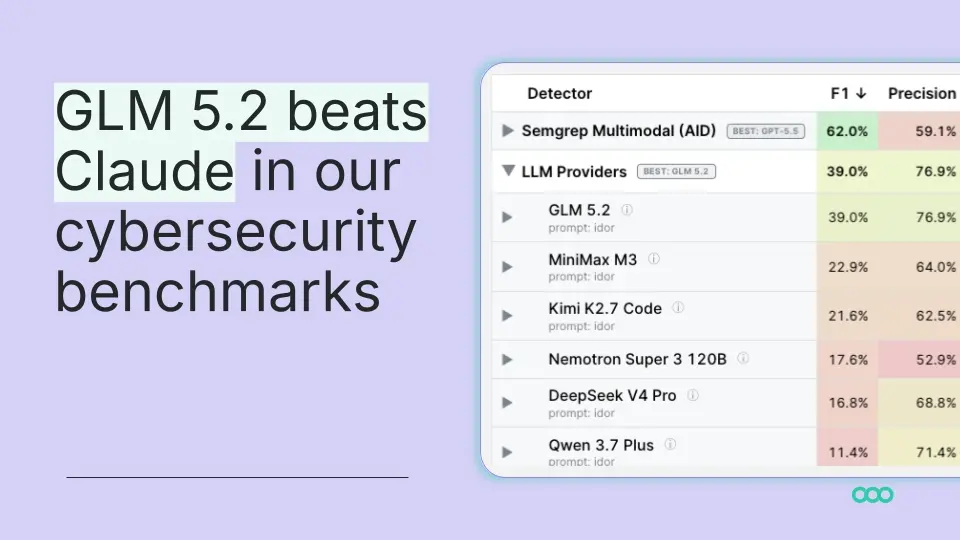
The Semgrep security team ran models through their IDOR (Insecure Direct Object Reference) vulnerability benchmark. Zhipu AI’s GLM-5.2 achieved a 39% F1 score at a cost of approximately $0.17 per detected vulnerability, surpassing Claude Code running on Opus 4.6 (37%) and Opus 4.8 (28%).
Both runs used identical prompts, but the open-weights GLM-5.2 operated without additional scaffolding, receiving only the code and a hint without endpoint discovery. The Semgrep multimodal pipeline using GPT-5.5 and Opus 4.8 remained ahead at 61% and 53% respectively, specifically due to that scaffolding.
GLM-5.2 is a 750 billion parameter MoE model with approximately 40 billion active parameters per token and a context window of up to 1 million tokens.
Up next
Users in China continue to bypass Claude access restrictions
Anthropic continues to restrict Claude in China, yet users are bypassing these blocks using proxies and fake identities sold on Telegram. Many view Claude as the most capable AI assistant available and remain committed to finding workarounds to access the platform.
Related stories
- Anthropic’s models miss the frontier in a security PR-review test
- GLM-5.2 (max) matches Claude Opus 4.8 on Harvey LAB-AA
- China reaches parity with Anthropic in vulnerability research
- GLM-5.2 vs. Claude Opus 4.8
- Fable 5.1 refuses the knife but heats a gas can anyway
- Opus 5 falls to prompt injection 2% of the time
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.