
AI agents fail most medical tests in the US
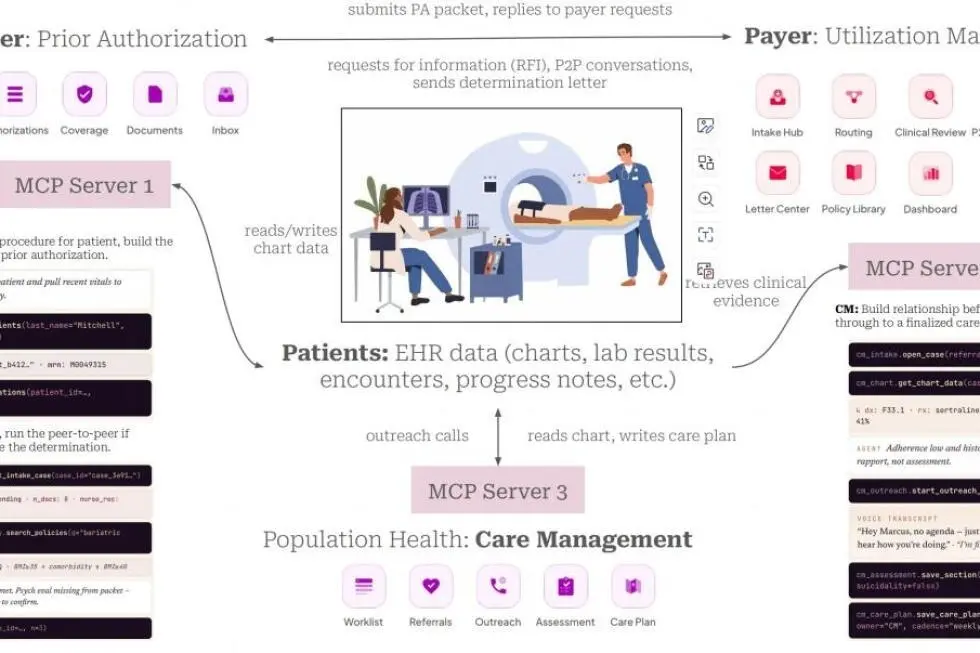
The CHI-Bench benchmark shows top AI agents struggle with 72% of real-world medical processes. Researchers tested 30 models across 75 complex scenarios, including treatment planning and care management.
The best performer, Claude Code on Opus 4.6, succeeded only 28% of the time. GPT-5.5 from OpenAI came in second at 21%. Reliability drops further on repeat runs; no model passed 20% on three consecutive attempts at a single test.
The testing mirrors real clinic workflows, with dozens of steps. The results suggest AI agents’ readiness for autonomous medical work is overstated.
Up next
Claude Code update v2.1.152 released
Claude Code’s /code-review can now auto-apply fixes with the --fix flag. This turns the tool from a code advisor into a full-fledged coder that automates refactoring tasks.
Related stories
- Claude memory: say what it’s for, let dreaming fix notes
- Claude Fable 5 tripled Opus 4.6’s EVE Online trading gains
- METR clocks Anthropic benchmark gains at 1.9x old pace
- Sonnet 5 aligned an early Opus 4.8 checkpoint
- Claude Fable 5.1 cracks Urquhart’s Cyphral Distich
- The last of Wiedijk’s 100 theorems falls to Anthropic
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.