
Intelligence Index v5: Opus 5.5 at 58, GPT-6 Astra at 57
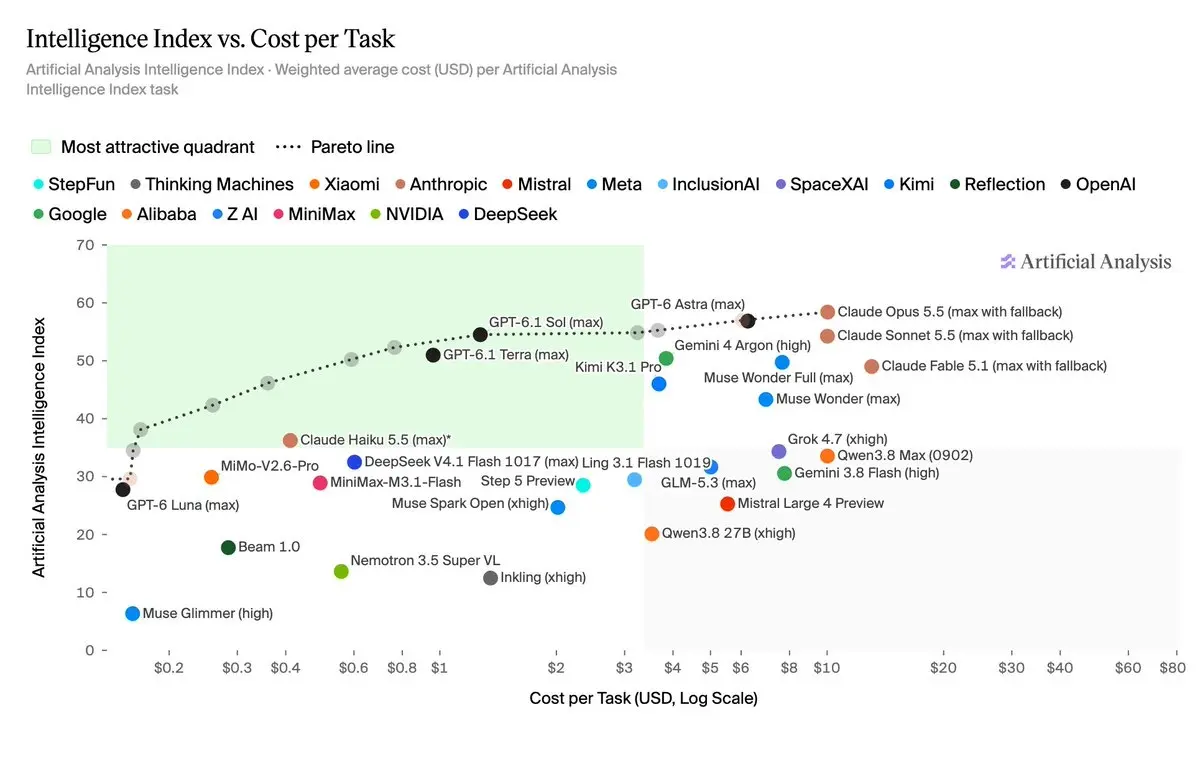
Claude Opus 5.5 at max reasoning effort scores 58 on version 5 of the Artificial Analysis Intelligence Index, released on October 28, which puts it one point ahead of GPT-6 Astra (max) at 57. Version 5 swaps out much of the test suite, so a score quoted without its index version and effort setting no longer tells you what was measured.
Behind the top two, GPT-6.1 Sol (max) scores 55, and Anthropic and OpenAI hold all of the top five places. Gemini 4 Argon is next at 50, and it was scored at high effort, not max. Artificial Analysis runs every evaluation itself, and most of the index is built on private datasets.
The index is now nine evaluations. According to the Artificial Analysis changelog, two of them are new. FrontierCode 2.0 is Cognition’s private benchmark of real-world coding tasks, and it grades the agent on whether a repository maintainer would merge its change. Terminal-Bench-Science is 70 agentic research tasks run in a terminal. Three more were upgraded. HLE-Diamond replaces Humanity’s Last Exam with 1,000 questions, split evenly between reasoning and knowledge. AA-Omniscience v1.1 drops saturated questions and every question from the public set. CritPt v2 is a private hard subset of 40 questions, run with a code-execution tool. GDPval-AA v2, SciCode and AA-LCR are gone.
Opus 5.5’s 58 matches the 58 it scored in September, but the test underneath is different. Version 4.3.2, which Opus 5.5 still led at about 58 as of October 14, averaged ten evaluations weighted 30% agents, 30% general knowledge, 20% coding and 20% scientific reasoning. Before this release the index had already been rebuilt five times since August 6.
The effort setting changes the score just as much. Artificial Analysis lists several variants for each model (max, xhigh, high, medium, low), and the same model name can score quite differently depending on which one ran. On an older version of the index, Claude Opus 5 went from 52 at Thinking Low to 63 at Max (With Tools).
Up next
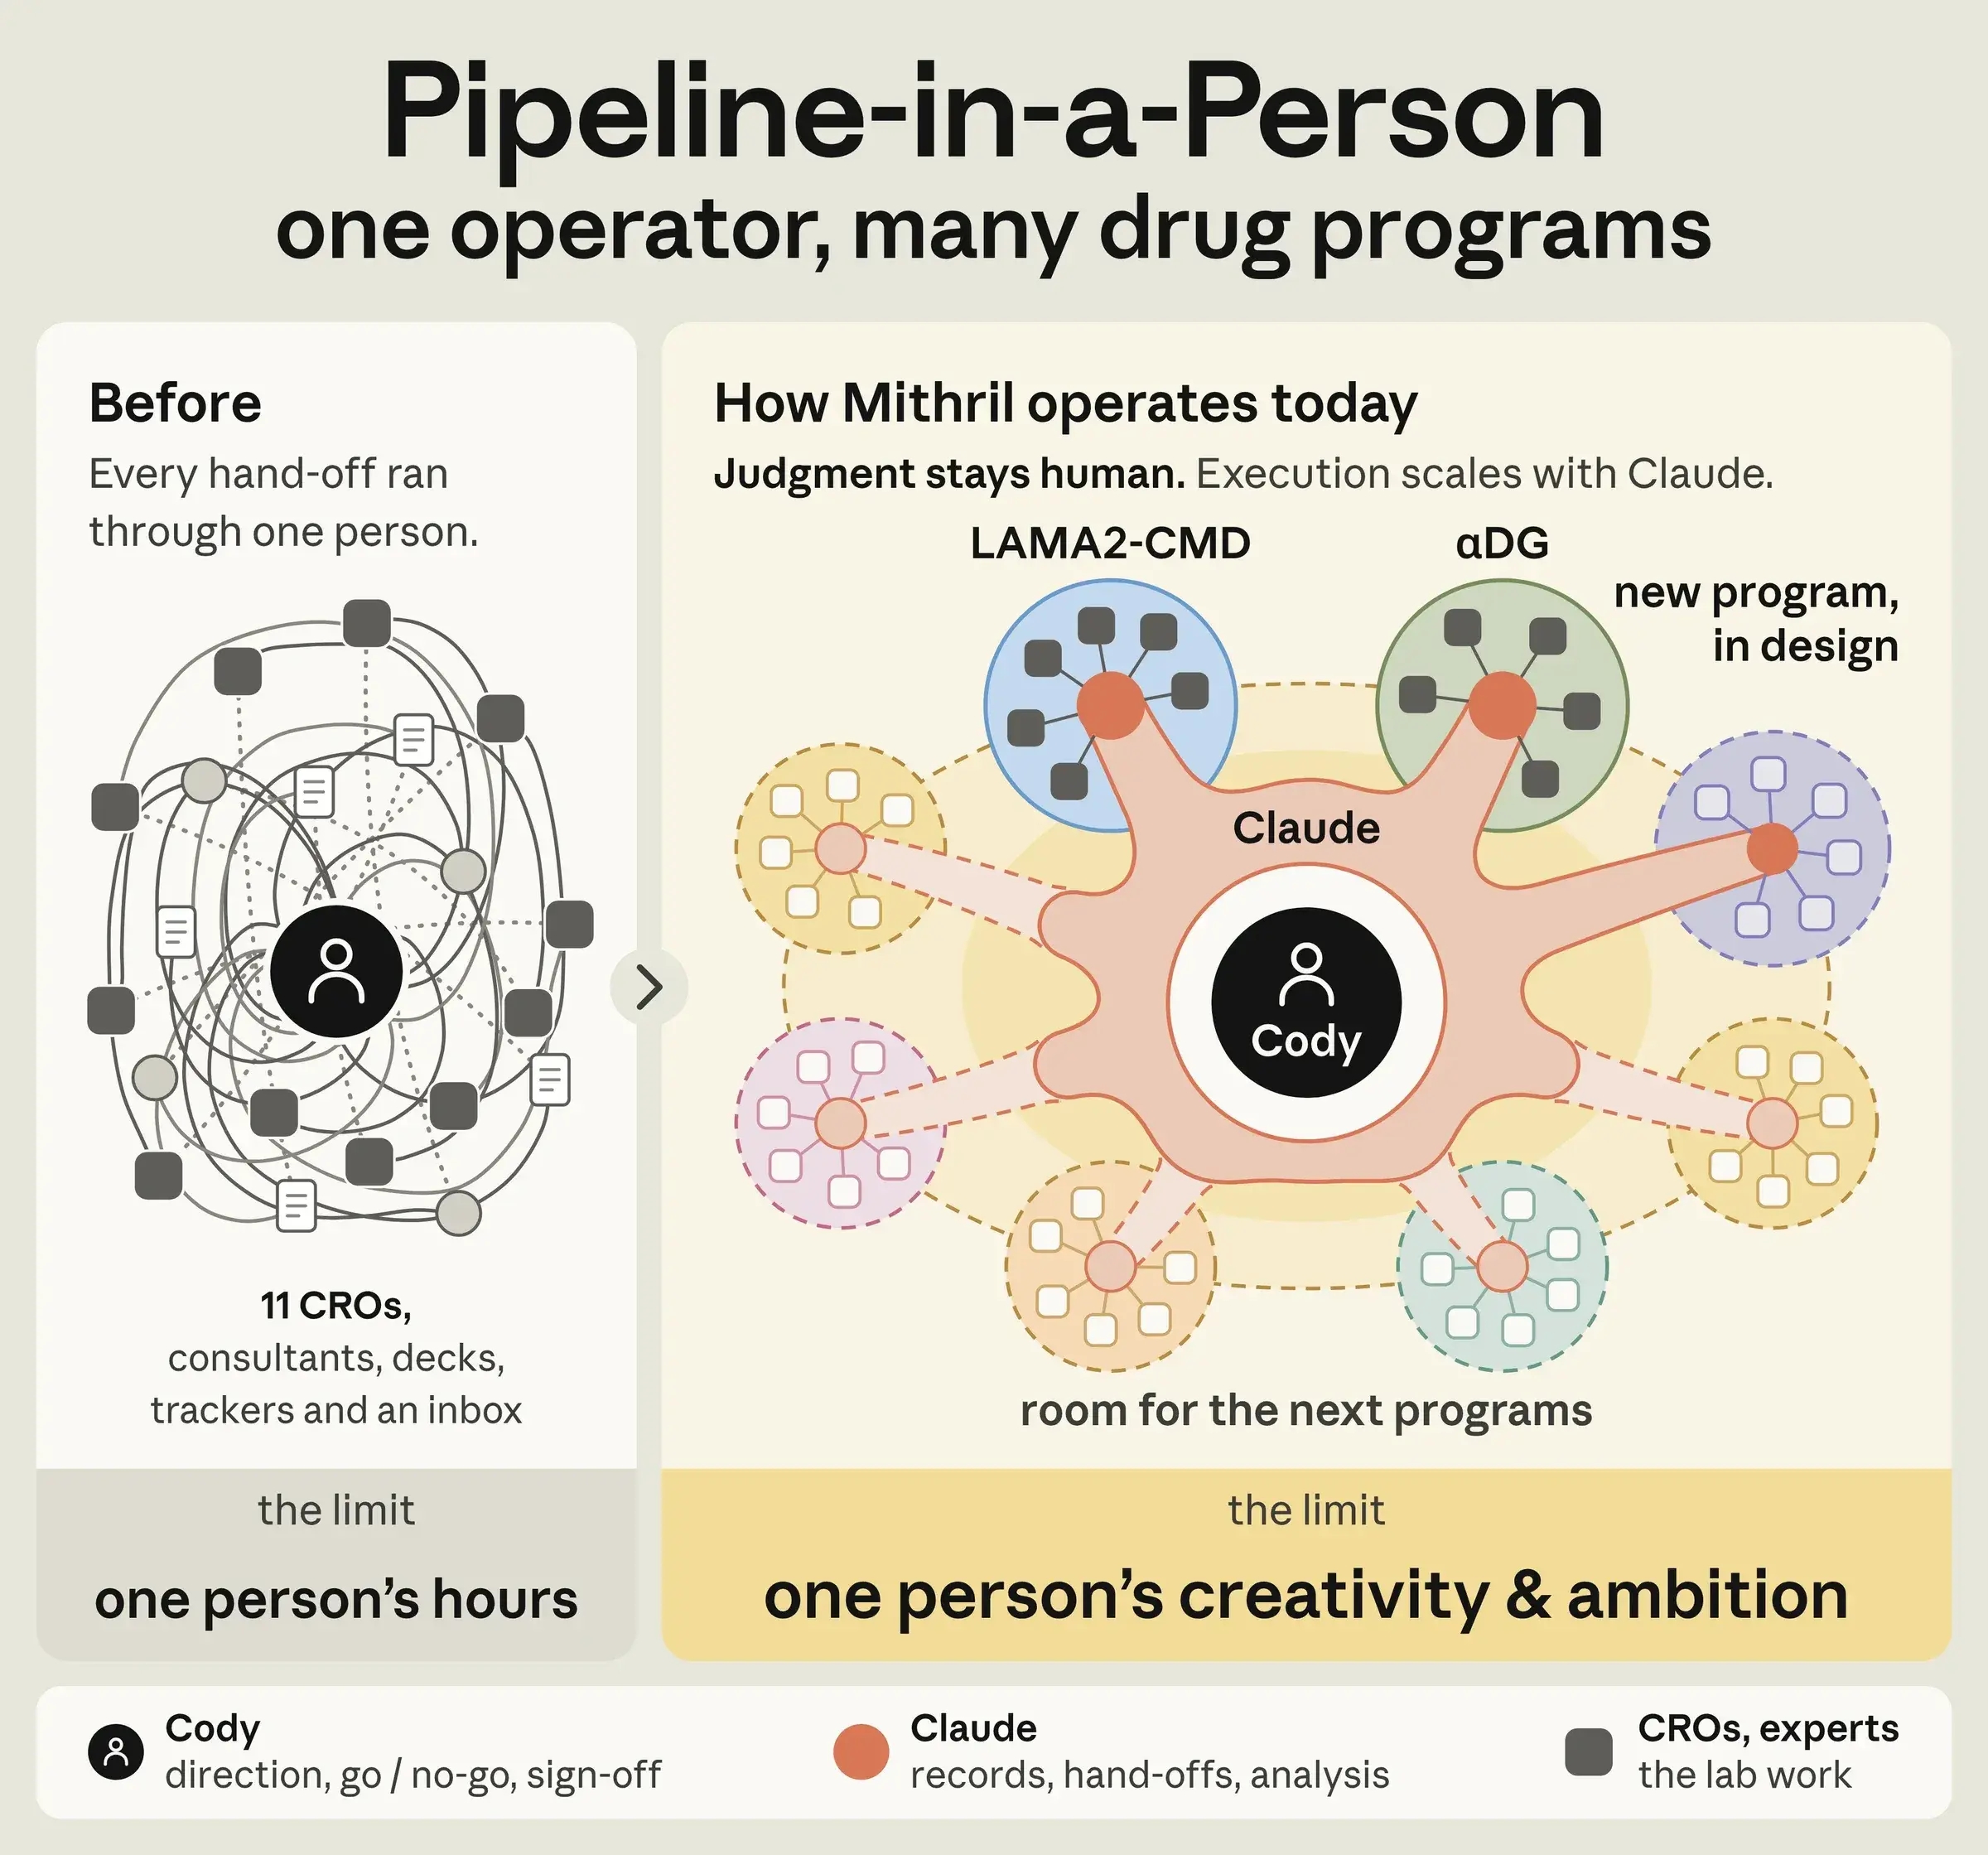
Anthropic buys Mithril, a one-person biotech run on Claude
Mithril Medicine had one full-time employee, who used Claude to run contracts and experiments with 11 outside labs. Anthropic bought it and sees human trials as soon as late 2028. How many outside vendors would you let Claude coordinate for you?
Related stories
- Opus 5.5 leads the index and burns 260M tokens doing it
- Andon Labs puts GPT-6 Astra ahead of Claude Fable 5.1
- GPT-6 Astra edges past Claude Fable 5.1 on WebDev Arena
- Claude Fable 5 vs GPT-5.6 Sol: a $100 music video bake-off
- Opus 5.5 cut cache reads from $0.50 to $0.20 per MTok
- Sweden’s Government Offices block Claude and ChatGPT
Comments
No comments yet. Be the first.
Join the conversation
Sign in to leave a comment. It appears after moderation.